
1. A useful map changes the next probe
A proposal gets no reply. That observation leaves several explanations alive: the buyer may not have opened it, the proof may be weak, the offer may miss the request, or the work may no longer be available. Changing the opening sentence is one possible response. Checking whether the buyer saw the proposal is another. Hyperrelevance Cartography gives that choice a record the next response can correct.
Take that as an illustrative decision, not a diagnosis of any particular buyer. The useful question is which observation would distinguish the explanations well enough to choose the next action. A reply, an objection, a view or a defined period without a response can each change the decision, but they don't establish the same thing.
A clap in a dark room makes the sensing loop easier to picture. Sound reaches nearby and distant objects at different times, and different materials change the return.
A second clap from another position changes the evidence. What first seemed like a continuous wall may have an opening. The map becomes usable through repeated contact, with each return informing the next movement and probe.
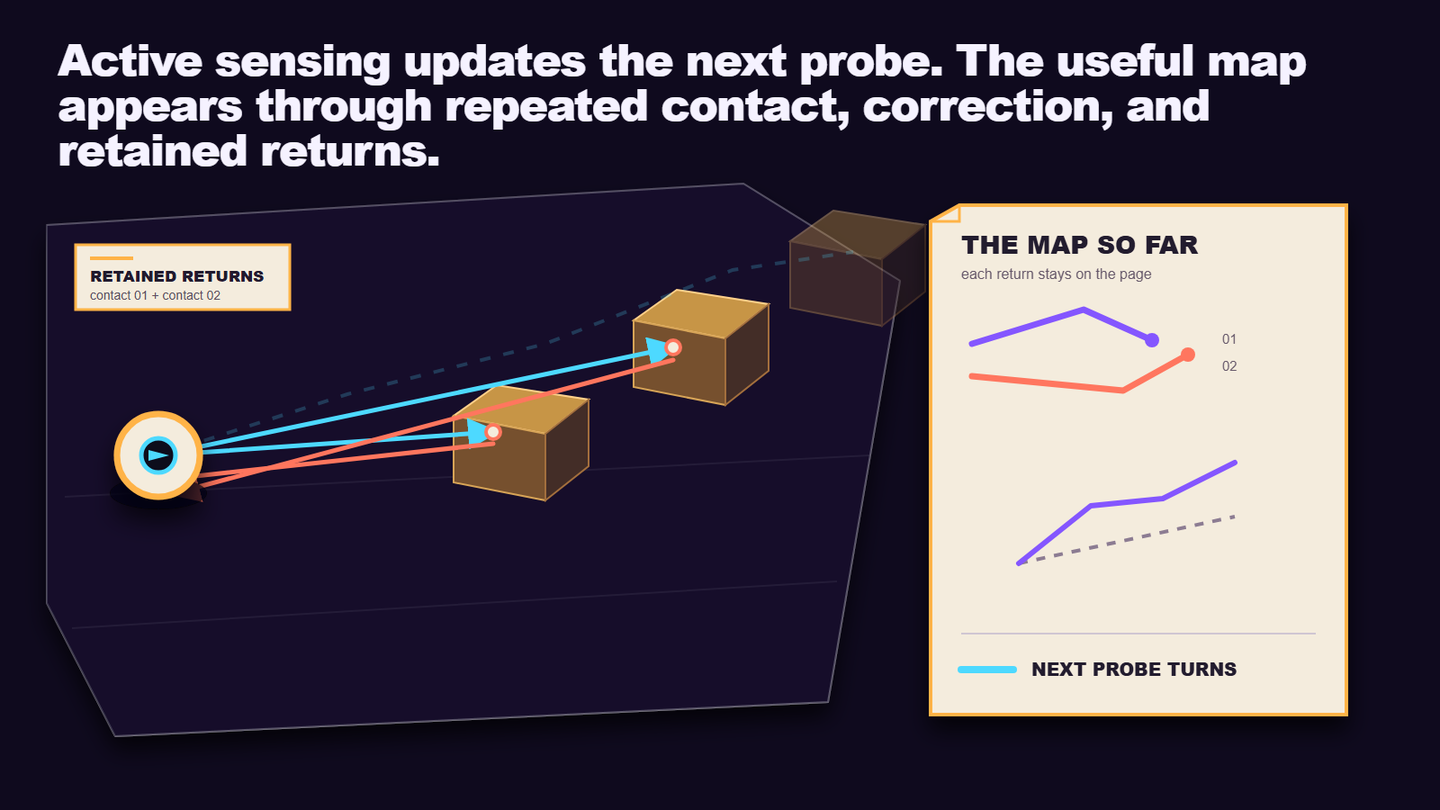
Bats do the same thing with far more precision. Echolocation is a form of active sensing: the animal produces a signal, receives what comes back, and adjusts its next signal to the task and the surroundings. An adaptive echolocation study shows bats changing the structure of their calls in a difficult auditory scene. The return doesn't hand the bat a finished map. It gives the bat evidence for its next movement and its next call.
Hyperrelevance Cartography applies that loop to markets, audiences, and decisions.
An operator sends a probe into a market: a customer interview, a search query, a proposal, a small ad, a pricing page, a field note, a joke, a demo, or a direct question. Something comes back. People click, ignore it, reply, object, buy, share, hesitate, or use words the operator didn't expect.
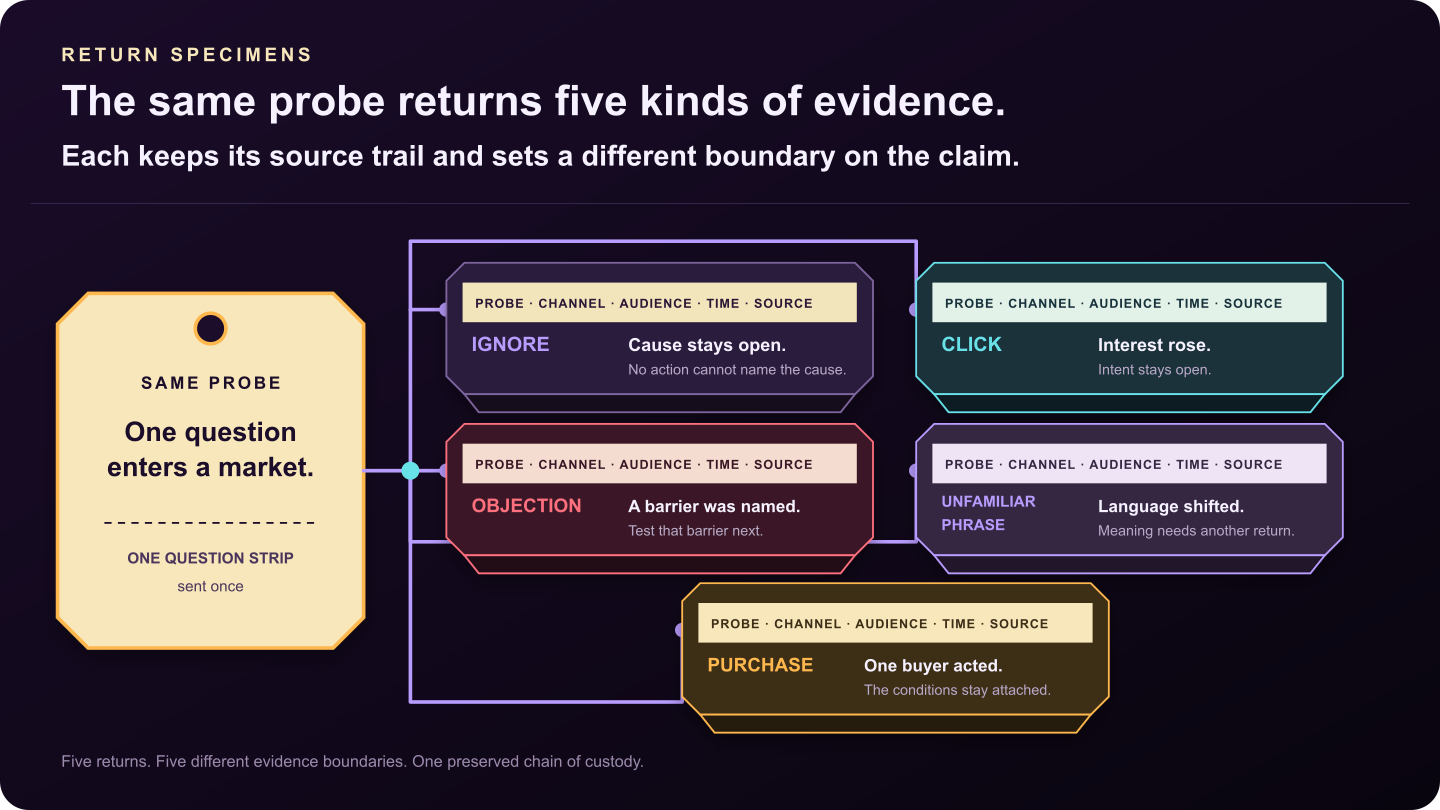
The operator records that return, updates a provisional map, adjusts how much confidence the map deserves, and picks the next probe.
Every useful probe starts from a decision. The decision tells the operator what to listen for, which instrument can hear it, and which result would change the next move. Evidence rules out some paths and real constraints rule out others. The operator then chooses one bounded action, watches what comes back, and changes the map.
The sequence starts with possible explanations, then a question and an instrument. Evidence and constraints narrow the options. A bounded commitment produces a return that updates the next question.
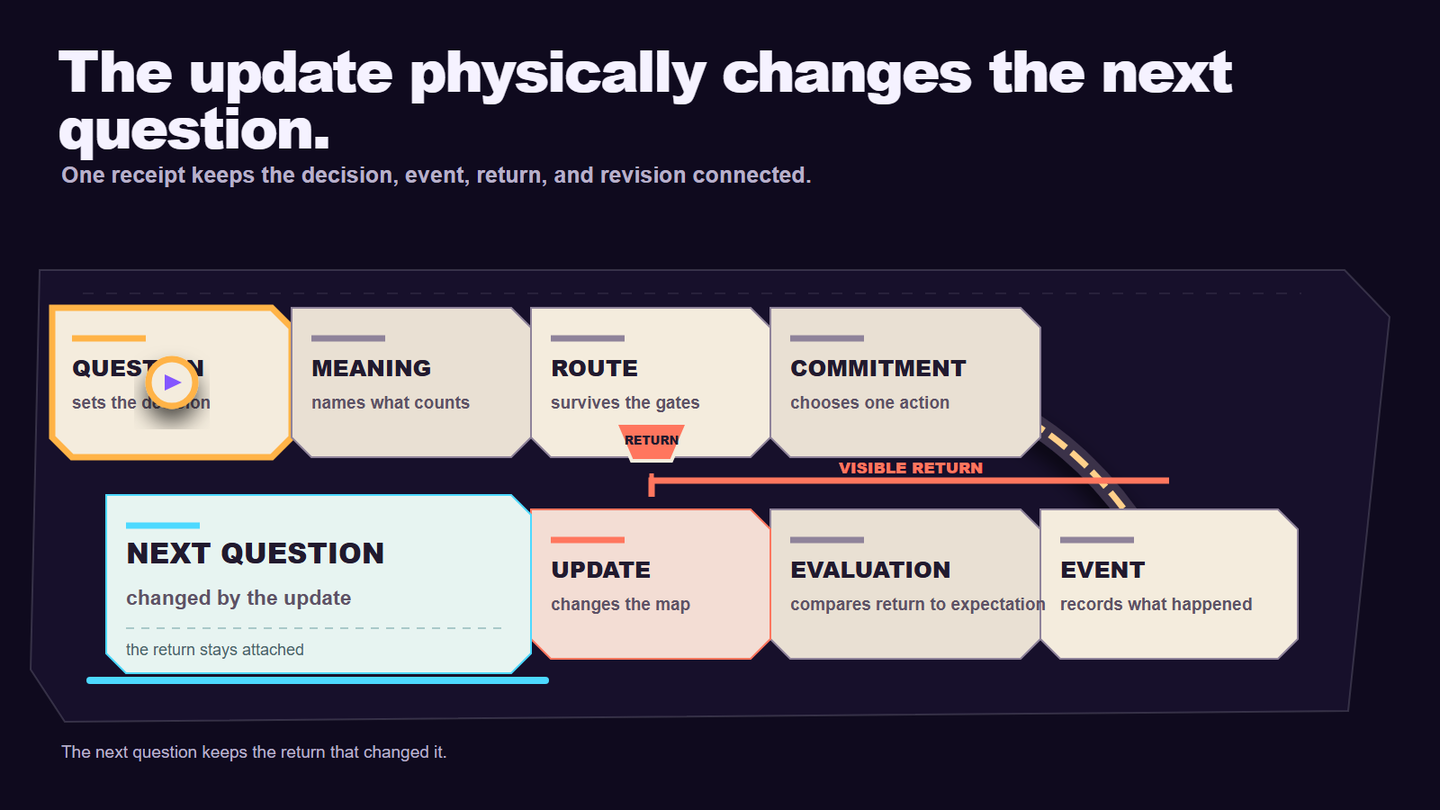
Consider an illustrative team deciding which proof belongs on a landing page for excavation contractors. Its candidate claims concern price, machine accuracy, less rework, support and onboarding. The question is which supported claim would justify inviting an equipment owner to inspect a demonstration. Interviews, search behavior and past calls can narrow the options. The available proof, audience and budget narrow them further. The team chooses a downtime calculator only if it can support the calculator's inputs, records the response it expects, and releases it to a bounded audience.
The return might be booked demos, confused questions, silence, or requests for a different kind of proof. None of those responses finishes the map, and each one changes the next test. That cycle is the practical core of intelligence engineering: sensing becomes useful when an observation changes an action and the result of that action changes the model.
The connection between the steps is what makes the sequence useful. Research tends to turn into a warehouse, where people collect interviews, reports, screenshots, analytics, and transcripts until the pile feels like knowledge. A pile isn't a map until it changes a decision, and a map doesn't stay current unless later returns can correct it.
Cartography is the right word for this work, because a useful map leaves most of the territory out. A road map ignores tree species, a weather map ignores property lines, and a subway map bends geography so the transfers are easy to read. Each view keeps the differences that matter for one kind of movement.
A market map works the same way. It might show current vocabulary, buyers, objections, channels, competitors, price pressure, trust signals, or the path from attention to purchase, and a different decision needs a different view. The map stays useful as long as it admits what it can't see.
People interpret a probe before they respond
The echo comparison breaks down in one place. A wall doesn't care that a bat measured it, but a person may change what they do because a company asked them a question. An interview subject may protect a colleague, try to impress the interviewer, forget a detail, or say whatever sounds polite. An ad can create the interest it's trying to measure, and repeated contact can build familiarity or irritation.
A market probe lands inside a social system, and the people in that system interpret the probe before they answer it.
A social return needs its conditions recorded before the operator interprets it. Each response should carry the question, channel, audience, timing, source, and conditions that produced it, and the map entry should carry a confidence level along with the reason for it.
One proposal without a reply is weak evidence. A repeated pattern among comparable, recorded proposals may point to a problem worth testing. A direct objection from a qualified buyer carries different weight from a guess made inside the team. A recorded sale establishes that a buyer acted. The message's contribution and its usefulness for another buyer remain separate questions.
A careful cartographer resists promoting every return into a law. The Mirror Ocean goes further into the hard part: a response comes from another person interpreting the probe, not from a passive surface reflecting it.
A trustworthy map stays unfinished
A provisional map carries a correction rule alongside its current answer.
Once a map is declared finished, people start defending it, and new evidence turns into an annoyance because the answer is already on record. A provisional map expects revision. It keeps the old state, records what changed, and shows which return caused the update.
That history lets another operator inspect the reasoning, and it lets the system learn from being wrong.
Suppose a company believes small contractors care most about price, and interviews support the idea. A pricing test then shows buyers choosing a more expensive package when it includes faster field support and clearer onboarding. The map shouldn't erase the interviews. It should keep both observations, narrow the original claim, and ask a better question next: under which conditions does service certainty outweigh price?
The new probe is better because the old map failed in a specific way. Keeping the old prediction beside the new outcome stops the team from rewriting its expectations after the result comes in. Separating prediction, execution, and observation is the working discipline behind the Observability Manifesto.
Hyperrelevance grows out of that correction loop. The system gets more useful without pretending the uncertainty has gone away.
2. A cartographer keeps decisions inspectable
The work begins with a decision someone can act on and a record another person can inspect.
A hyperrelevance cartographer keeps a changing situation legible for a decision maker.
The cartographer finds current evidence, separates observations from interpretations, connects related objects, tracks when claims were true, records confidence, and turns the result into a view somebody can use. After the decision, the cartographer records what happened and updates the map.
That's a different job from general research, which might explain a whole industry. Hyperrelevance work explains the part of the industry that matters for a choice someone is making now: which Upwork job deserves a proposal, which audience deserves a new offer, which client objection deserves a field note, which creative deserves production, or which agent workflow deserves more authority. In every case, the decision sets the lens.
A decision bounds the research question
"Learn everything about construction marketing" has no stop condition. "Decide which supported proof to show an excavation contractor" has edges. The question names the buyer, the choice and the event that would change it. Start with the customer's problem independently of the product being sold.
The sharper question tells the team which equipment owners matter, which job conditions matter, which downtime costs need proof, which vocabulary signals familiarity, which existing tools compete for attention, and what response would change the decision.
The first research pass maps the domain: who participates, what objects move through the system, what events change its state, which terms carry precise meanings, and which sources own which kinds of truth.
The next pass maps mechanisms: how a buyer moves from problem to search to comparison to purchase, which constraints block that movement, and which signals reveal urgency, budget, trust, or fit.
The third pass tests the map against current evidence. Do the latest job posts, conversations, search results, product releases, and customer actions still support it? Where has the vocabulary changed, and which claims have expired?
Then the team produces a practice artifact, such as a proposal, a piece of content, a tool, a demo, or a campaign. The artifact forces the map to make a prediction, and the market returns evidence. That makes the artifact a test as well as an output.
Five records make the loop inspectable
Every meaningful probe should leave five records:
- The question. What uncertainty was the operator trying to reduce?
- The return. What happened, and what source produced the observation?
- The interpretation. What might the return mean?
- The confidence change. Which belief became stronger, weaker, or more specific?
- The next probe. What test now has the highest value?
The records keep research from turning into theater. A hundred sources can look impressive and leave the decision untouched, while one clean return that eliminates a bad path is worth more. Between them, the five records keep what the team believed before acting, what it did, what came back, how it judged the result, and what it carries into the next run.
They also stop memory from turning into folklore. A team may remember that “customers hated the old offer” when nobody can find the calls, the segment, the date, the offer version, or the exact objections. Later operators then inherit a conclusion stripped of the conditions that made it reasonable, and hyperrelevance depends on those conditions.
Mapping, engineering and action carry different responsibilities
Three roles overlap in this work. The cartographer builds and updates the map. The engineer builds the instruments and workflows that make mapping repeatable. The operator uses the map to act, judges the return, and holds authority over consequential choices.
One person can wear all three hats, but the distinction still helps.
An automated pipeline that tags named entities can pick out people, companies, products, locations, and relationships, and a retrieval system can bring related evidence into a decision. Both are engineering. Deciding that a cluster represents a new buyer concern takes a cartographer's judgment, and choosing whether to change the offer takes the operator's authority.
Mixing up the roles produces predictable failures. An engineer may build a beautiful graph and assume the visible cluster means something to the business. A cartographer may spot an important relationship and underestimate the work of keeping it current. An operator may act on a dashboard without knowing which assumptions shaped the view.
The loop holds up when the instruments show the choices they made and people can inspect those choices.
Relevance has a clock
Hyperrelevance adds time to ordinary relevance.
A source can be accurate and stale. A tactic can be effective in one platform regime and harmful after a policy change. A buyer objection can dominate one season and disappear after a competitor changes pricing. A voice model can preserve phrases a person stopped using years ago.
Every important claim therefore needs a time boundary.
When was the observation recorded, and when did it become valid? Has later evidence contradicted it? Does the decision need today's state, a historical trend, or both?
The map should be able to say, “This was true then,” without saying, “This is true now.”
That sounds simple, yet many systems either overwrite old facts or keep every fact forever with no visible expiration. Both habits damage reasoning: overwriting destroys the history, and facts that never expire turn old states into current noise.
A map with time built in keeps the sequence. Shape of Data: Provenance explains why a fact needs both a source trail and a clock before another decision can safely reuse it.
3. Expertise needs current evidence
Expertise stores compressed experience.
A senior operator has seen patterns repeat, watched tools fail, learned which questions expose weak thinking, and built instinct around consequences. That compression is valuable because nobody can re-derive an entire field before every decision, and the same compression can hide drift.
A paper road atlas can be beautifully made and show every town and highway that existed when it was printed. The atlas becomes dangerous when a bridge closes, a bypass opens, and the driver keeps trusting the old page because it once worked.
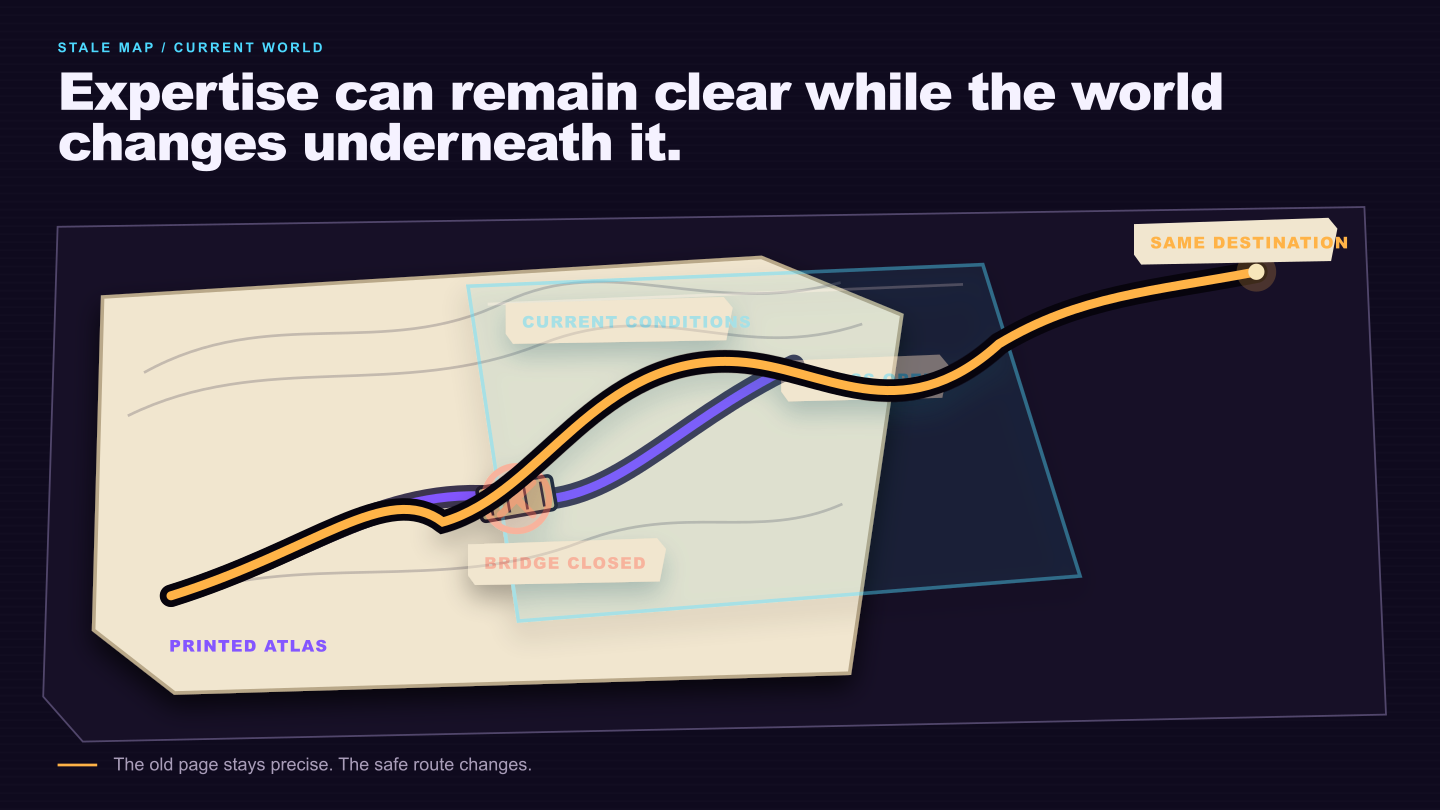
Markets rebuild their roads all the time. Platforms change their ranking systems, buyers learn new vocabulary, and AI tools lower the cost of common outputs. Regulations move, competitors copy successful offers, and audiences develop banner blindness to formats that worked last year. A tactic can decay while the expert's confidence stays high.
Experience and recency solve different problems
Experience helps you interpret a return, and recency tells you what the current state is.
A junior researcher may retrieve the latest release notes and still miss the mechanism that makes the change important. A senior expert may understand the mechanism and miss that the release happened. The strongest system combines current retrieval with experienced judgment. Market Research goes deeper on sensing a changing market without discarding the experience needed to interpret it.
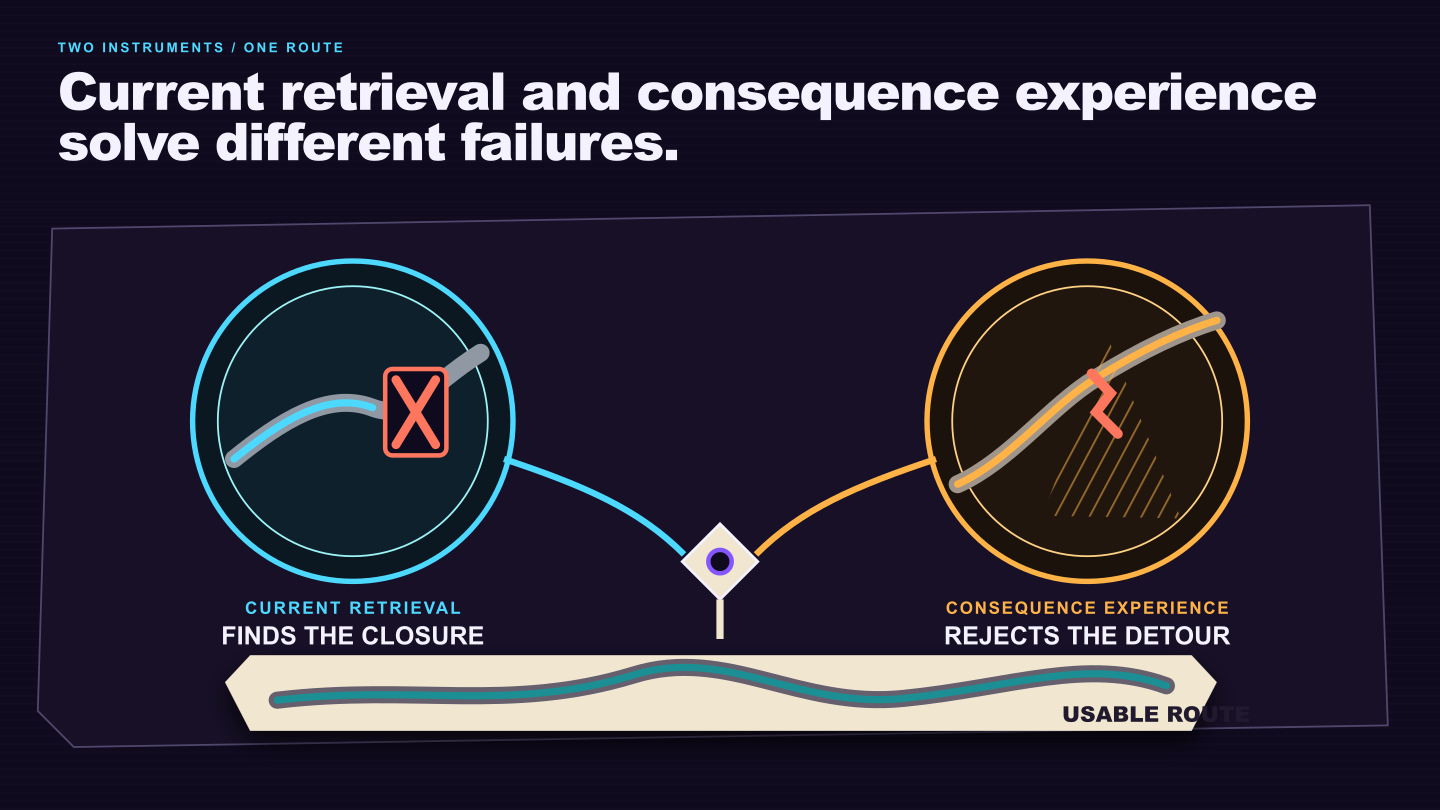
That split changes the familiar junior-versus-senior argument.
A junior backed by a good research platform can gather sources, map vocabulary, compare claims, and run bounded tests at a speed that once took a large team. The junior still needs evaluation, calibration, and a feel for consequences, because the platform doesn't supply experience of consequences.
A senior expert gets a different advantage from the same system: current evidence can challenge stored assumptions before those assumptions get expensive. The system works as an external memory and as friction against confident recall.
The competition that matters is unaided judgment against judgment connected to current, inspectable evidence, not junior against senior.
Changed conditions require a newly tested route
Some drift is harder than a new software release.
A business can lose the conditions that made an earlier approach work. A familiar channel changes, a service becomes harder to deliver, or buyers demand different proof. The old procedure can remain perfectly clear while the route it describes is no longer available.
Treating improvement as a return to the old procedure can keep the team testing an assumption whose conditions have disappeared.
Consider a team rebuilding a service after a failed delivery. It starts with one bounded engagement, adds one dependency at a time, and checks whether the work still holds. A wider audience or a second market comes after the narrower operation has produced evidence.
The team records what changed, what still works, and which additional load caused the next failure. That sequence gives awareness, skill and mastery something observable to mean.
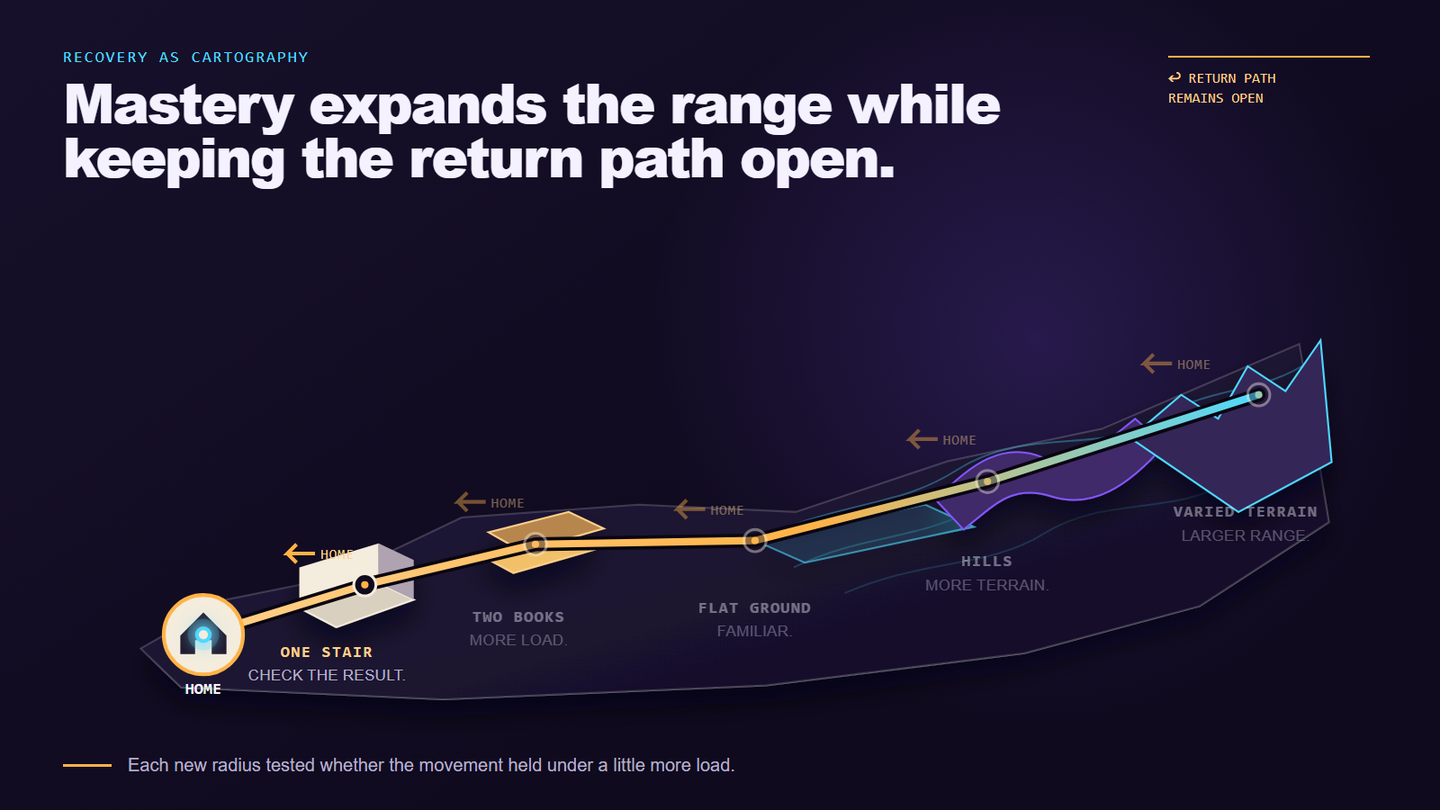
The first map records the changed condition. The next records a method that works within it. Later tests establish how far that method can travel before it needs revision.
Awareness, skill, and mastery are names for the same progression.
Awareness finds the changed condition. Where does the pain start? Which assumption belongs to the old body, old business, or old market? What can still carry weight?
Skill builds a movement that works inside a controlled range: one stair, one offer, one audience, one test market. The range stays small enough that a bad assumption shows up before it gets expensive.
Mastery expands the range while keeping the return path open, adding more workload, a larger market or another culture. The operator acts under present conditions instead of assuming the earlier conditions have returned.
Buyers and communities retain lessons from earlier failures. A buyer who paid three agencies and received three polished failures reads a new promise through those losses. A community that watched outside capital arrive, extract value, and leave will treat the next outsider's language as evidence. A technical audience that spent a year correcting confident AI answers will look for receipts before it accepts fluency.
Demographic labels can't hold this history. "Small-business owner," "crypto user" and "construction company" describe broad groups. A useful customer record asks what happened, what changed afterward, which words now prompt caution, which proof addresses the stated risk, and which observed behaviors support the interpretation.
That history is what turns a customer model into more than a persona card.
Problem, Story, and Transformation provide a useful sequence. A problem is the observable condition. A story is the belief built from repeated contact with that condition. A transformation is a new movement that becomes possible when the person gains enough evidence, skill, and courage to act.
The story layer explains why two people with the same problem choose different routes. One failed campaign may teach a buyer to demand stronger proof. Another may teach the buyer that every agency lies, and a third may teach the buyer to avoid marketing altogether.
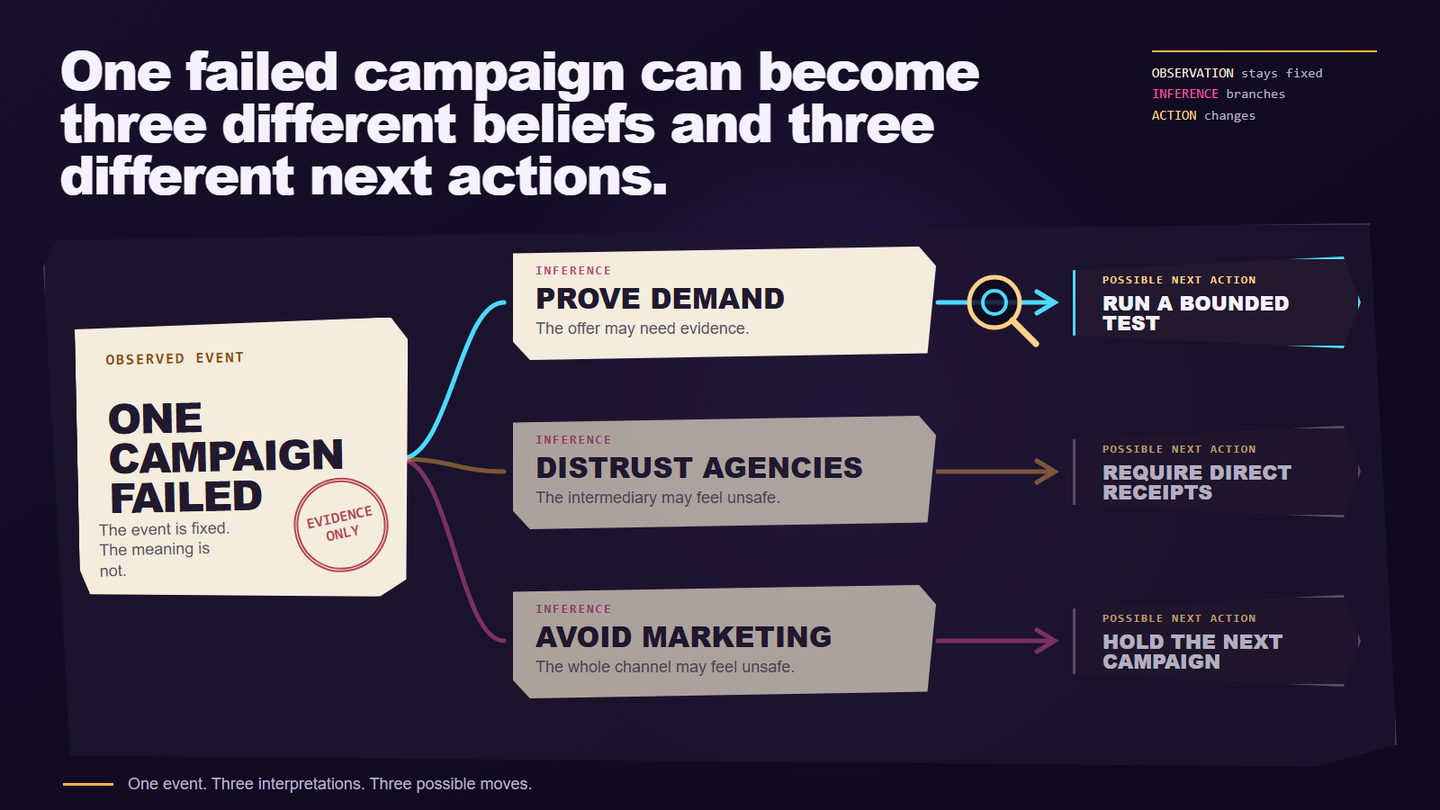
Hyperrelevance Cartography keeps those differences. It links language to experience, experience to belief, belief to behavior, and behavior to a possible next step, and it marks which links came from a source and which remain inferences.
Geographic expansion follows the same rule. A market an operator knows from years of unfiltered contact can serve as a close practice radius. A neighboring market adds load. A national market adds more cultures, channels, and failure modes, and international expansion adds translation, law, history, and local trust networks.
Skipping a radius hides the source of failure. If a message fails across five countries at once, the team may see one low conversion rate and invent one broad explanation. A smaller test can reveal that the offer works, the proof feels foreign, and one phrase carries a local meaning the team never learned.
A cartographer earns each expansion through returns. Every market sends back language, objections, actions, and outcomes, and those returns update the world model before the next radius opens.
The goal is movement that works under present conditions and keeps learning as those conditions change, not a perfect return to an earlier state.
Vocabulary reveals belonging and drift
Every field develops words that carry compressed meaning.
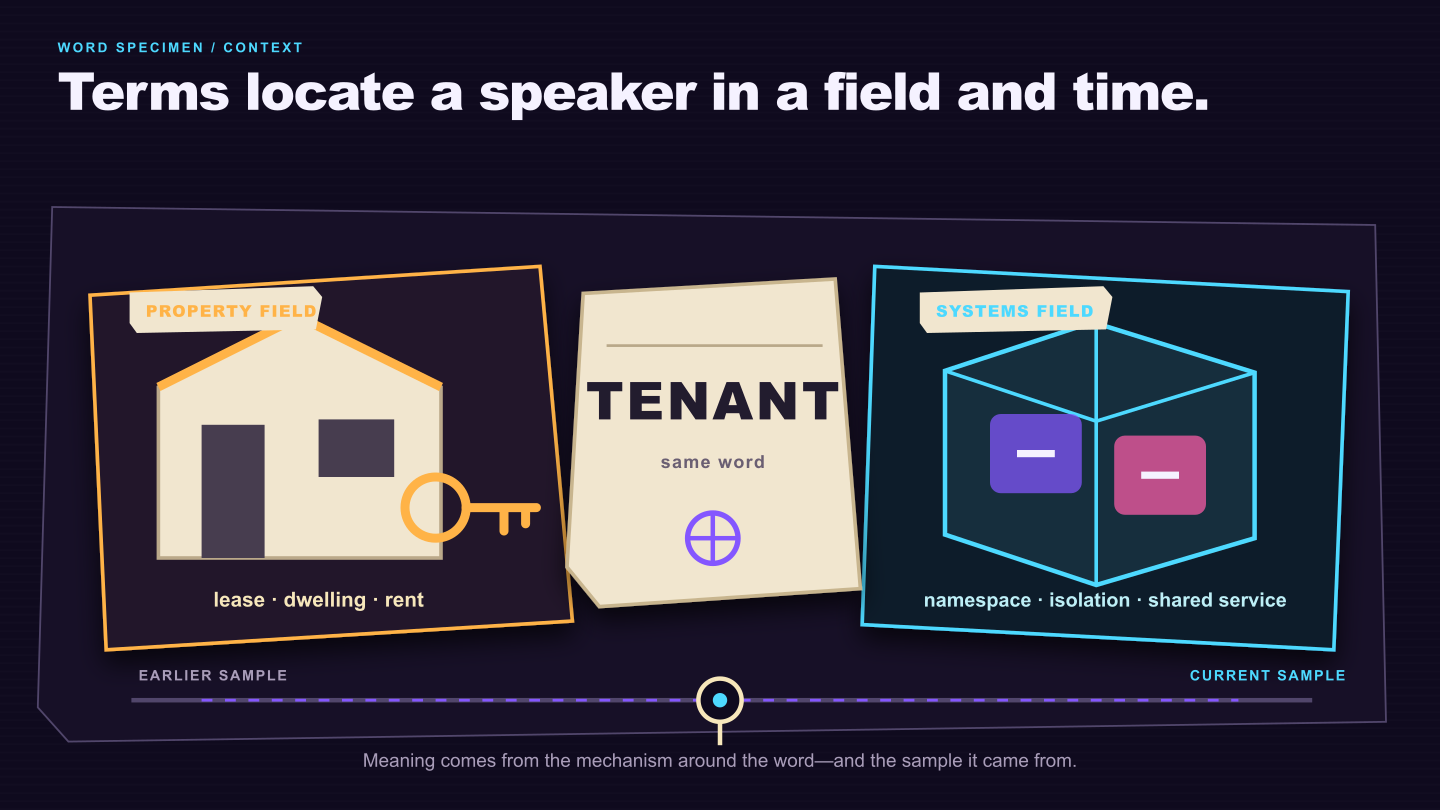
An excavator operator, quantitative trader, creative director, and multi-tenant systems engineer may use the same ordinary word in different ways. “Grade,” “spread,” “scene,” and “tenant” each point to specific mechanisms inside their fields.
Generic vocabulary tells the audience that the speaker sees the category from far away. Correct vocabulary can signal that the speaker is close to the work, and current vocabulary can signal that the speaker is still doing it.
A cartographer maps terms alongside entities and facts. Which groups use the term? What does it distinguish? When did it appear, and which older phrase did it replace? Which words look similar but should never be collapsed?
Sprinkling jargon over weak thinking makes the work worse. Vocabulary matters when it carries distinctions the model must preserve.
A voice fingerprint adds another layer. Phrase frequency, sentence shape, parts of speech, preferred examples, rhythm, topics, and repeated transitions can describe how a person communicates. The fingerprint becomes useful when it helps preserve authorship across a large production system.
A fingerprint also ages. A living voice changes after new work, new audiences, and new failures, so the system needs drift audits rather than a frozen imitation.
Constraints make best practices local
Advice often goes stale because the constraint moved.
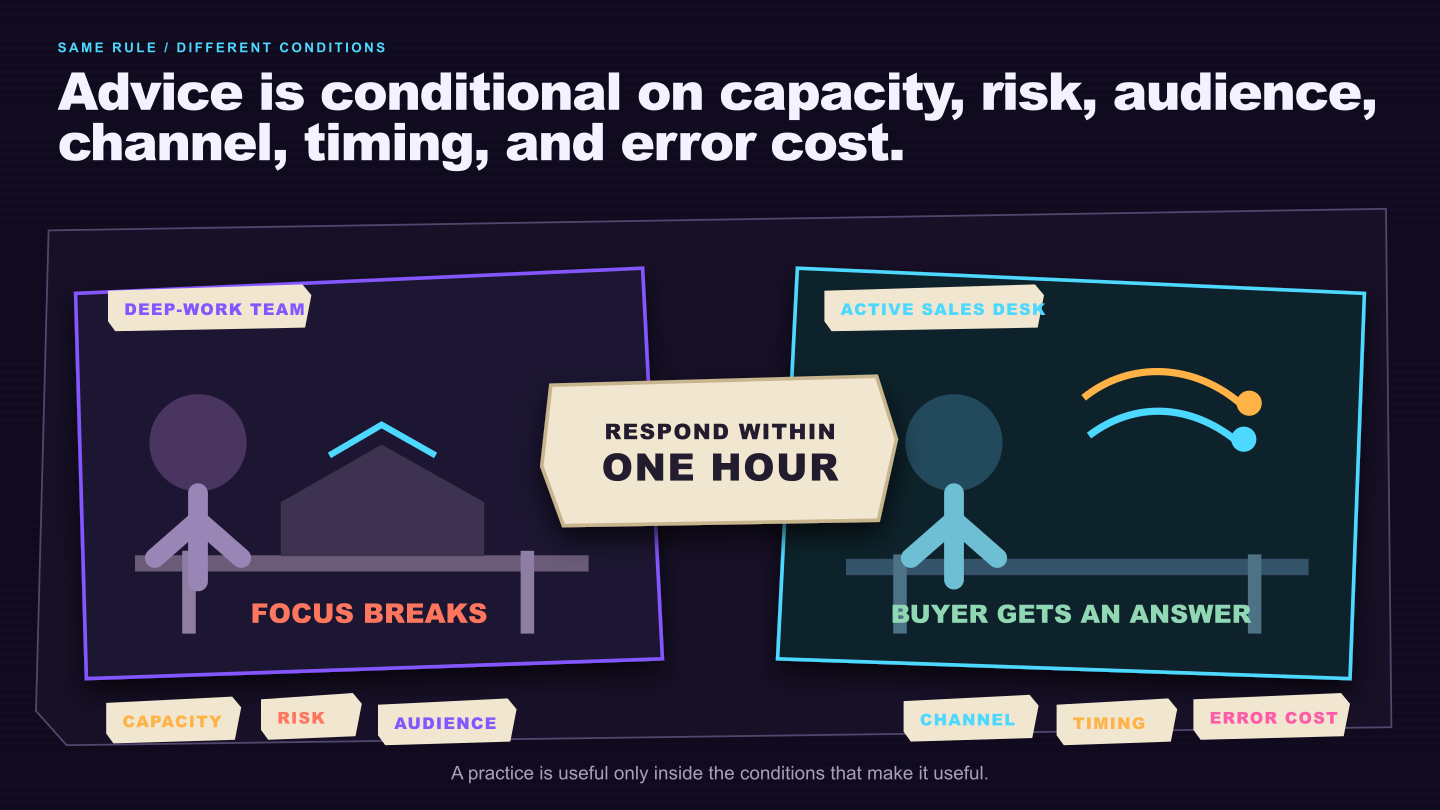
“Post every day” may work for a creator with a large production team and fail for a specialist whose trust depends on primary-source depth. “Respond within an hour” may improve one sales process and destroy another team's focus. “Use the winning template” may raise short-term conversion while teaching an audience to ignore the brand.
The expert answer depends on capacity, risk, audience, channel, timing, and the cost of error.
Hyperrelevance records those constraints as part of the claim. The system asks where a practice works, for whom, under what load, with which failure modes, and how the operator will know when the practice has decayed.
The result is a set of routes with their conditions attached.
Conditional routes put demands on the data underneath them. One current decision needs one clear view, and the system beneath that view has to keep enough structure to support many other views.
4. A question determines which shape matters
Dump a thousand puzzle pieces onto a table.
If the question is “Which pieces form the sky?” color matters. If the question is “Which pieces touch the border?” straight edges matter. If the question is “Which pieces connect these two faces?” location and pattern matter together.
The pieces haven't changed. The question decides which differences are useful.
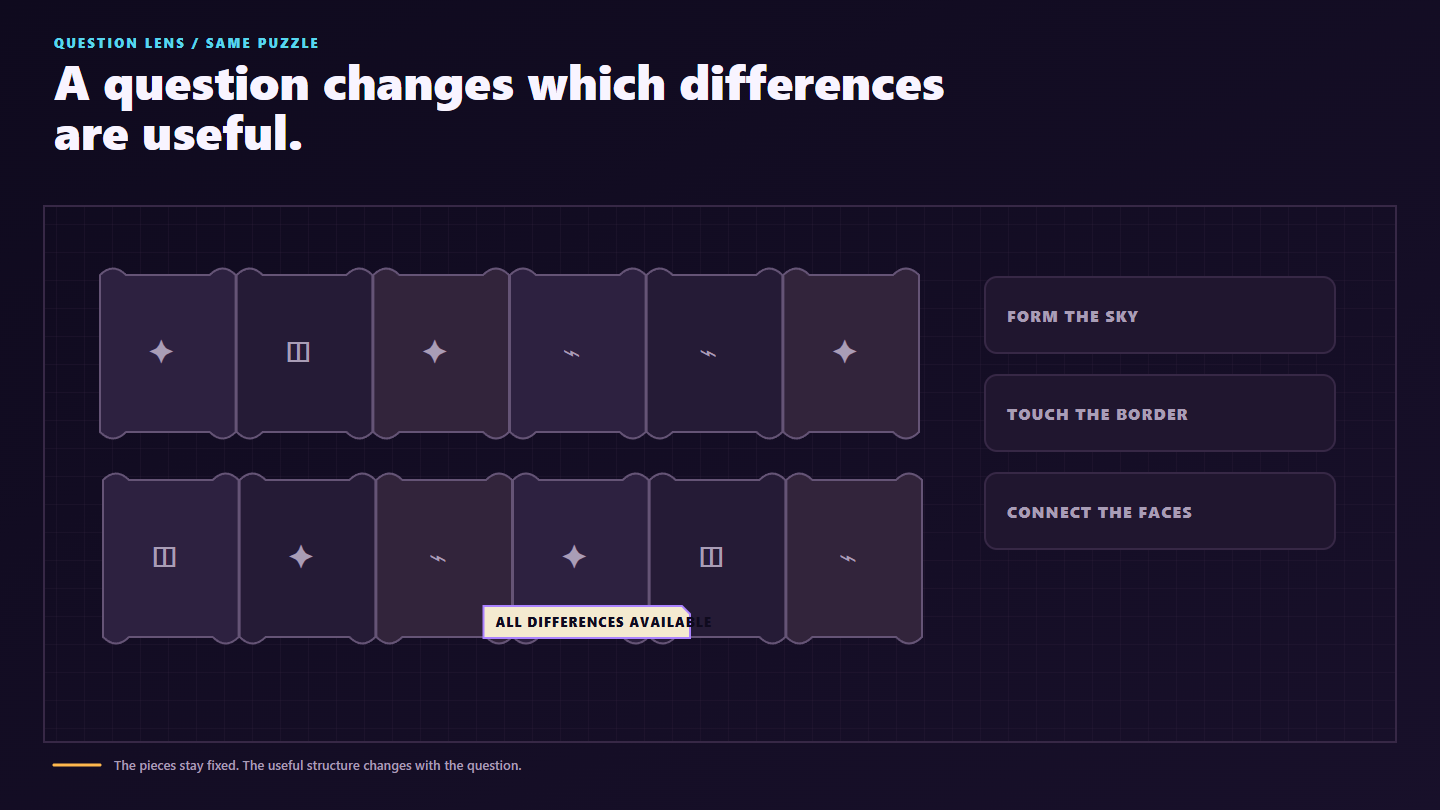
Data systems work the same way. A corpus can be viewed by topic, recency, confidence, source, audience, entity, voice, or business outcome, and each lens brings some relations forward and pushes others back.
A visible map is a constructed view of selected relations.
Remembering that protects a team from its most persuasive graphics. A glowing cluster in three dimensions feels discovered, yet it still depends on what was collected, how the items were represented, which distance rule and projection were chosen, and what threshold separated one group from another. The instrument shapes the picture.
Data can have measurable shape
Topology studies properties, such as connections and holes, that survive certain changes in shape. Topological data analysis applies those ideas to data.
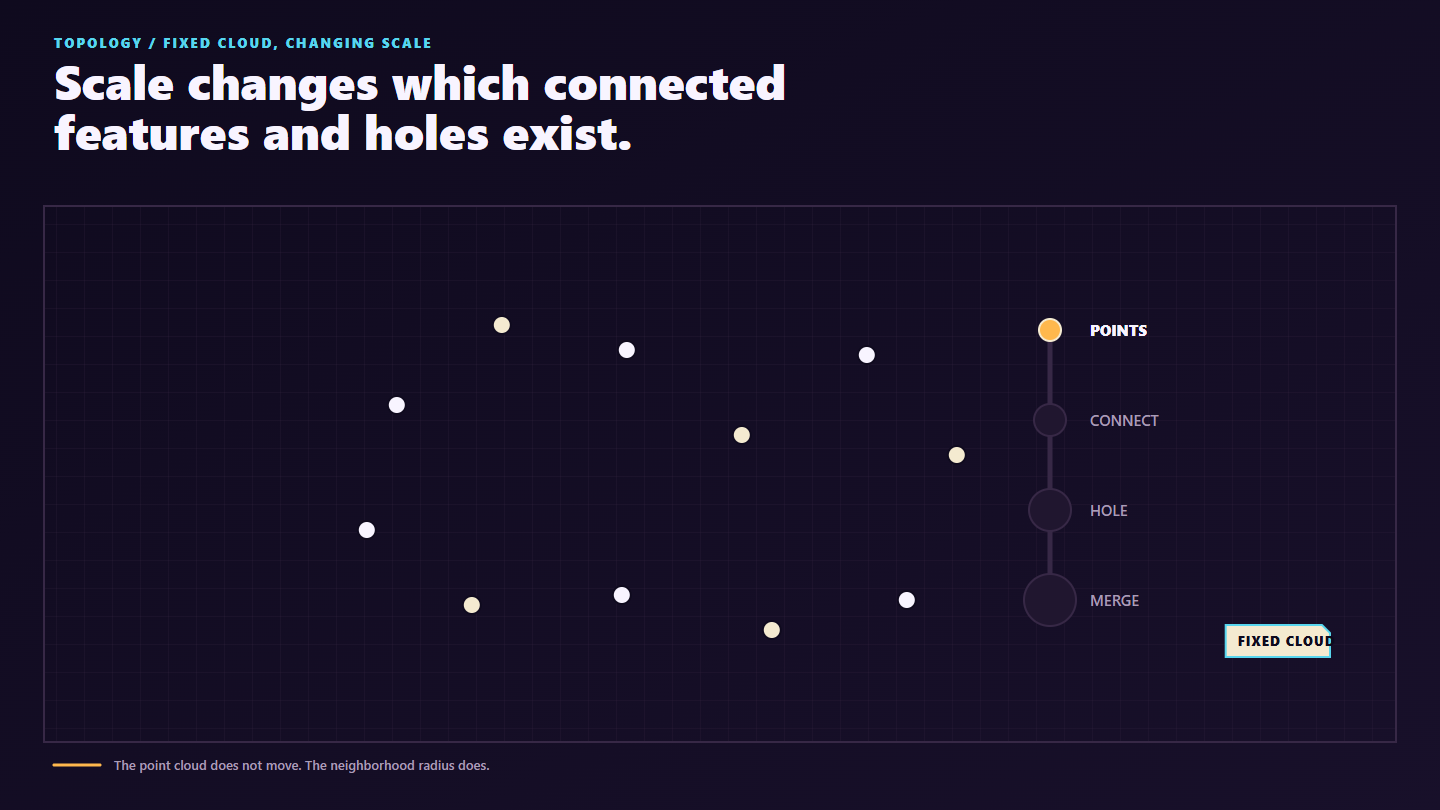
One method, persistent homology, watches features appear and disappear while a chosen scale changes. Imagine drawing a small circle around every point in a field and then slowly expanding the circles. Nearby points connect first and larger groups merge later. Some holes appear briefly and vanish, while others survive across a wider range of scales.
The result can be recorded as a barcode. A longer bar means the feature survived more of the chosen scale sweep.
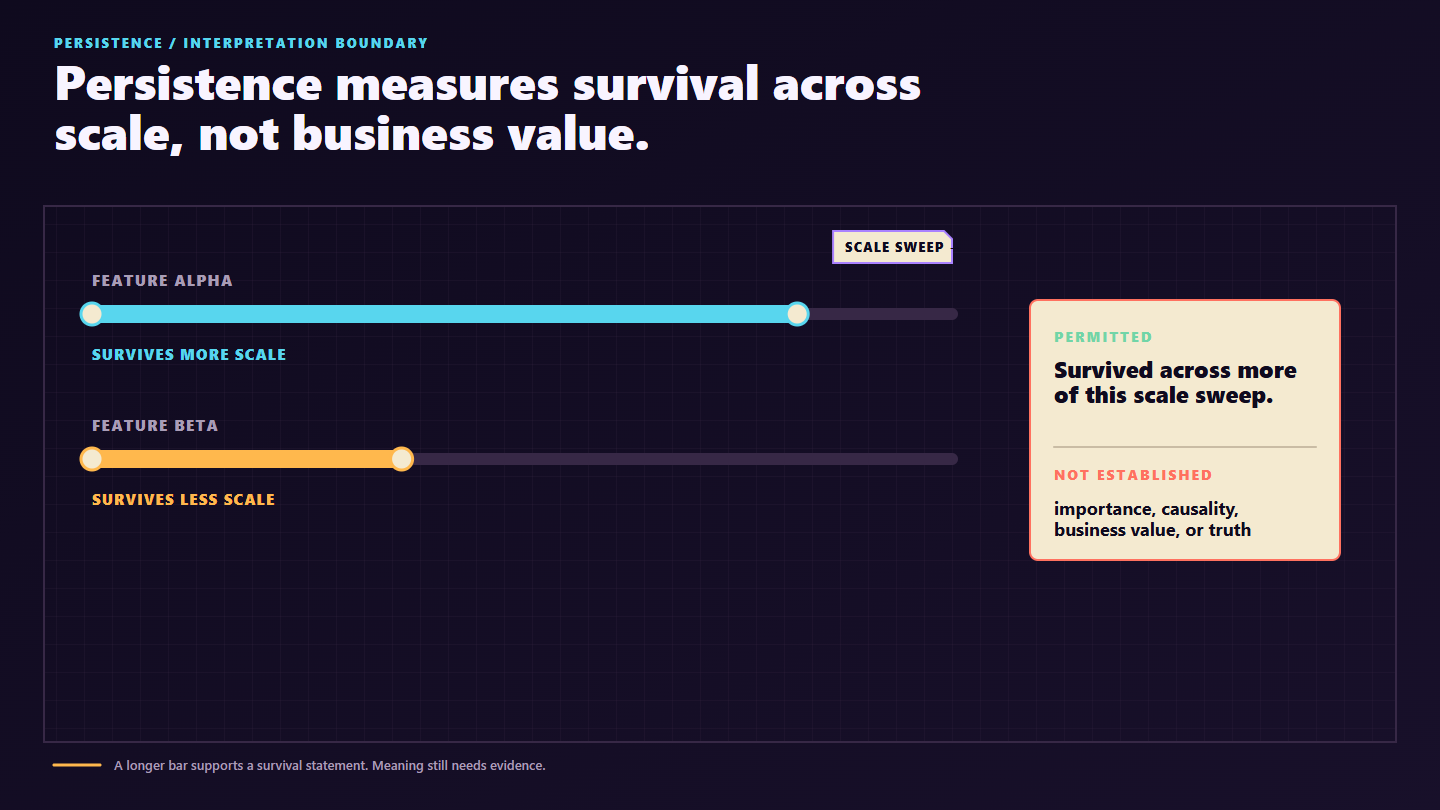
A long bar doesn't mean the feature is important, causal, valuable, or universally true.
The method gives a stable summary under stated mathematical assumptions, but the business interpretation still depends on the representation, the metric, the sample, and the question. A persistent loop might indicate a meaningful cycle, a sampling artifact, or a structure the embedding model created.
The mathematics detects a pattern, and a person or a tested rule decides what the pattern means.
A lens can turn a field into a graph
Mapper is another method from topological data analysis. It starts with a lens, which is a function that assigns a value or position to each data item. The method divides the lens range into overlapping areas, groups similar items inside each area, and connects groups that share items.
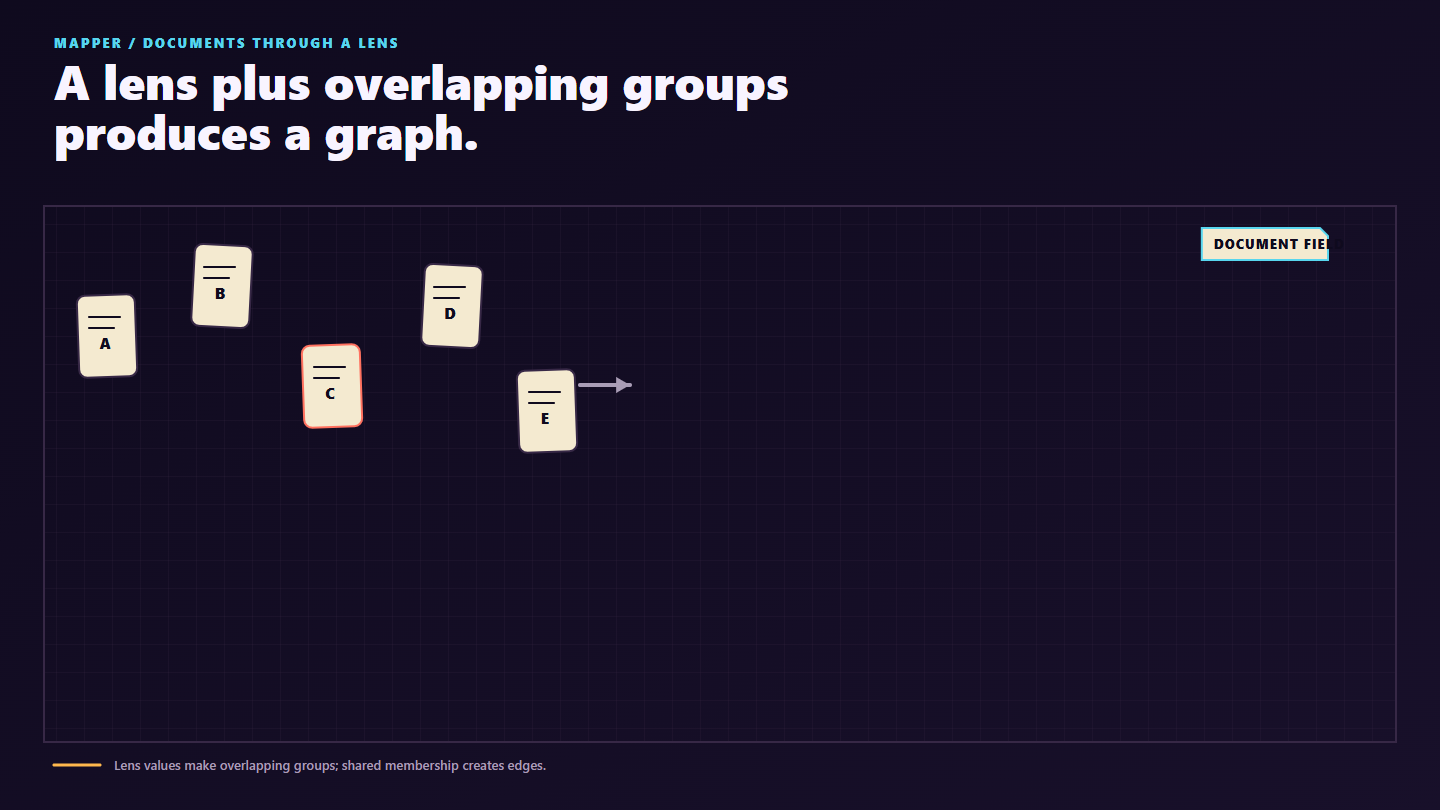
The result is a graph. In plain language, Mapper asks: when we look at these items through this particular question, which neighborhoods appear, and where do they overlap?
A recency lens may reveal old and new vocabulary connected by transition documents. A confidence lens may separate well-supported claims from speculative clusters. A demand lens may reveal several buyer groups that share one problem but differ in budget or urgency.
Change the lens and the graph changes. Change the cover, clustering rule, distance metric, or sample and the graph may change again.
That flexibility is useful because no neutral master view exists, and it turns dangerous when the choices disappear behind the interface.
A cartographer should be able to say why a lens exists and which decision it serves.
Direction carries meaning
Many relations run in one direction only.
“A cites B” differs from “B cites A.” “A happened before B” differs from “B happened before A.” “A supports B” differs from “B supports A.” Flatten those arrows and the map can keep proximity while destroying the mechanism.
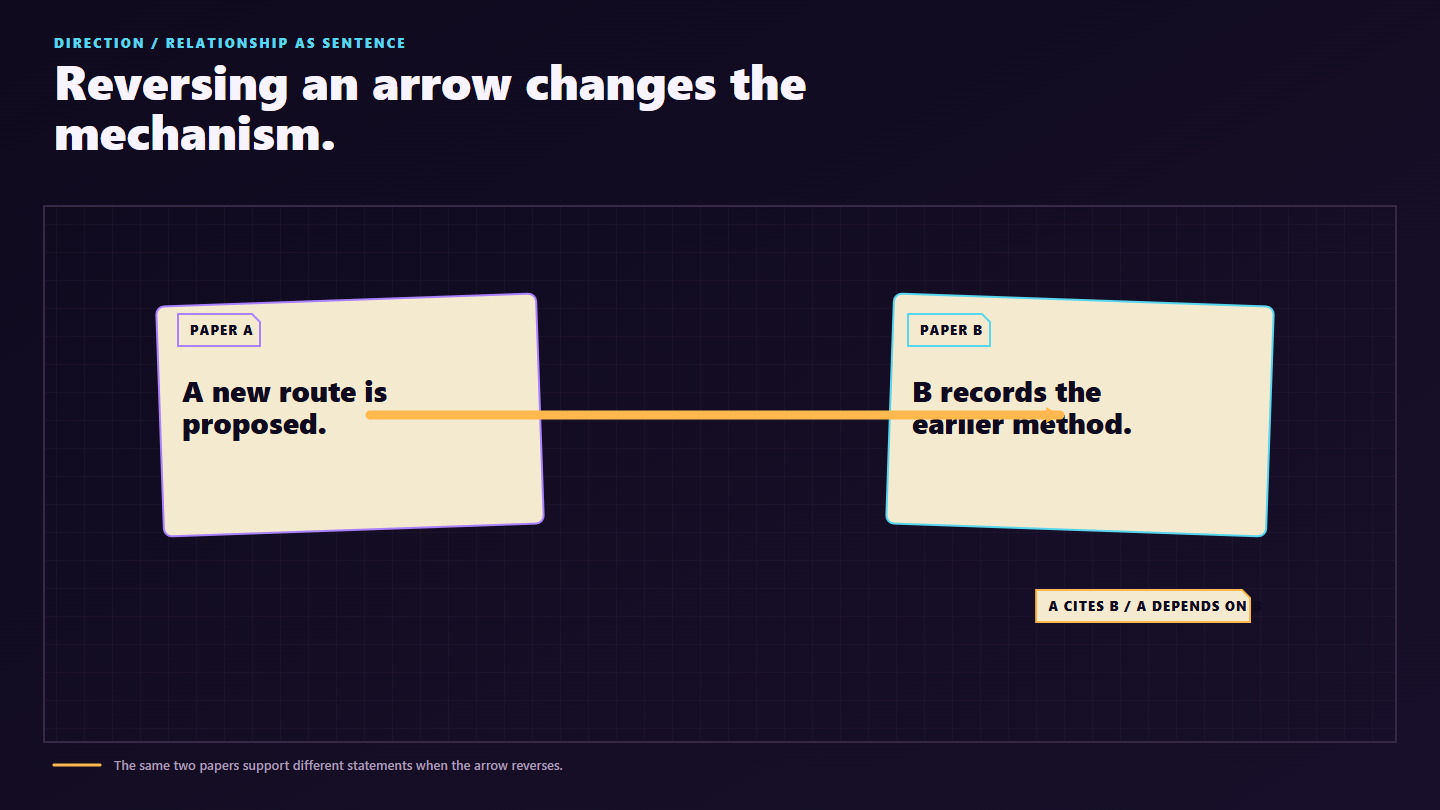
Topological methods built for directed graphs can detect structure that ordinary point-cloud methods miss, but their output still needs interpretation. A directed cycle may be a feedback loop, circular reasoning, repeated citation, or an ingestion defect.
The system should preserve the arrow first and argue about its meaning second.
Evidence and constraints narrow a decision
Several explanations and routes can be reasonable at the same time before a team acts.
A prospect may be ignoring a proposal because it arrived late, the offer felt generic, the proof was weak, the budget changed, another freelancer won trust sooner, or the buyer hasn't opened Upwork again. Uncertainty here means the team has several candidates with different evidence behind them, not that the team knows nothing.
The decision question creates the first boundary. “Why did this proposal fail?” is too loose because failure hasn't been observed. “Should we change the opening for the next five recent posts aimed at technical buyers?” names the actor, the change, the sample, and the next observable event. Evidence outside that decision can wait.
The instruments set the next boundary. The first keeps the work aligned from its purpose down to the action and the event that ends it. The second starts from the buyer's problem, the future the buyer wants to live in, and the change needed to cross that gap. Used together, they stop the team from choosing an elegant answer to the wrong problem. The linked essays explain diagnosing a customer's problem and the choices a data shape preserves.
Evidence and constraints then narrow the field. A route dies when the source contradicts it, the budget can't support it, the operator lacks permission, the claim has no proof, or the action can't produce a readable return. Several routes may survive, and convergence reduces the uncertainty without pretending to erase it.
Committing changes the world the team works in. The team selects one bounded action, records what it expects, and crosses a state boundary. The routes it didn't choose stay in the decision record, because a later return may make one of them useful. A reply, a view, a sale, an objection, a silence window, or a failed render becomes the return. The team compares that event with the prediction, changes its confidence, and reopens the decision when the conditions no longer hold.
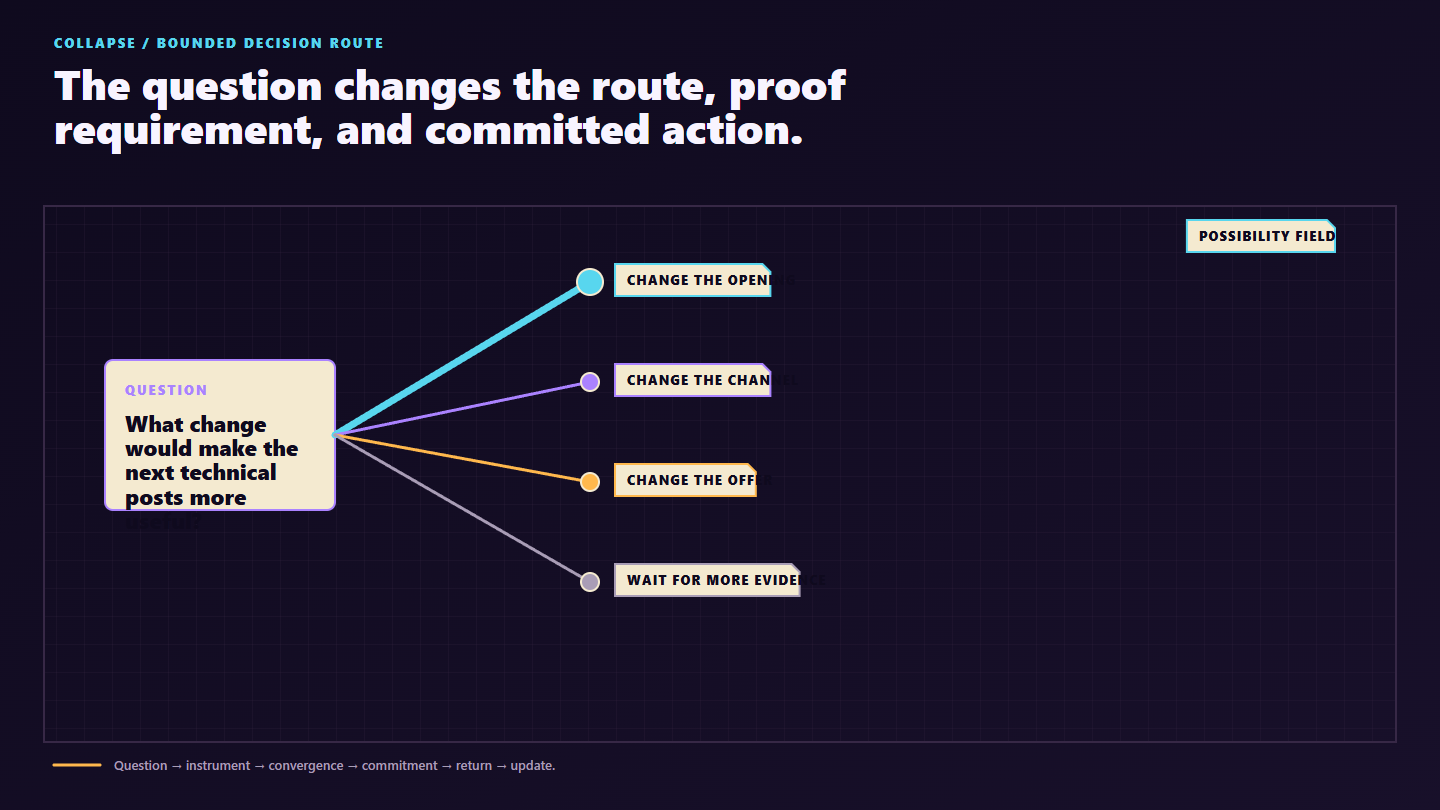
Quantum measurement supplies an image for the moment a range of possibilities gives way to an observed result. This business sequence is an operational rule: retain the alternatives, name the instrument, commit one observable act and let the return revise the map. Customer decisions don't obey quantum mechanics, and observation doesn't make a market claim true. The physics image supplies no evidence for the commercial method.
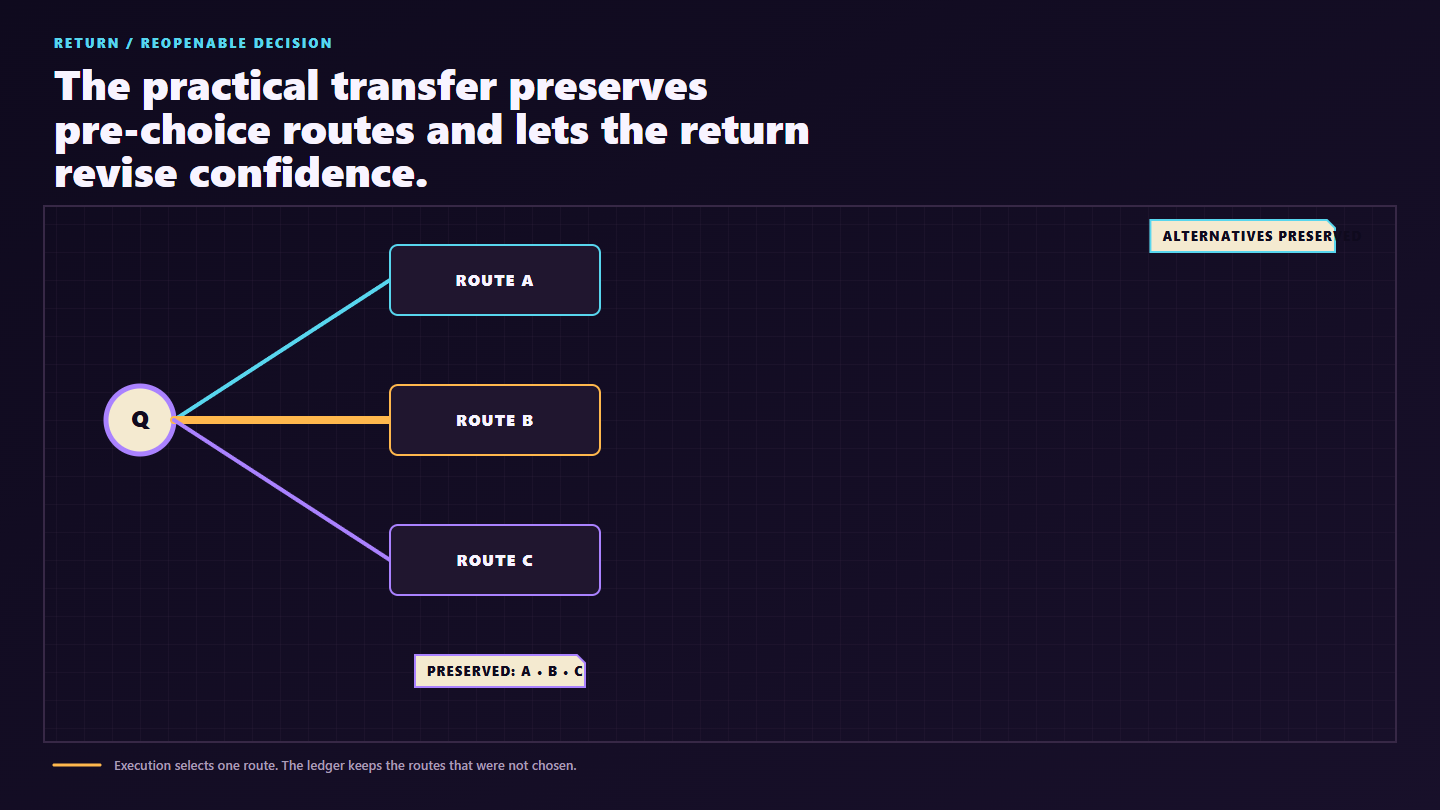
Objects Are a Position follows this idea into a deeper question: what appears to be a stable object may be a view produced by a particular instrument, scale, and purpose.
The system underneath the view now needs a way to keep objects, relations, time, confidence, provenance, and many possible maps, and that's the metagraph's job.
5. A metagraph preserves structure beneath many views
A city contains many maps.
The street map connects intersections, the property map records ownership, the water map follows pipes and pressure, and the transit map shows routes and transfers. The weather map moves across all of them. A delivery driver, a city planner, a plumber, a landlord, and a tourist can stand on the same corner and need different views, and the city is larger than any one of their maps.
A metagraph gives a data system a way to preserve the shared objects, relations, and views beneath those maps. It can hold documents, people, companies, products, events, facts, claims, questions, workflows, artifacts, decisions, and the relations among them. It can also hold graphs as objects, connect one graph to another, and keep the provenance and time that tell an operator how a relation came to exist. The Research-Layer Metagraph Compiler shows how that structure can support a public research and compilation pipeline.
Implementations vary, and the idea that matters stays stable: the underlying model keeps enough structure to produce many decision-shaped views without rebuilding reality for every question.
Nodes and edges are the beginning
A basic knowledge graph represents things as nodes and relations as edges.
Andy is a person, SuperHarness is a system, and a Field Note is an artifact. “Andy authored Field Note” is one relation, and “Field Note explains Hyperrelevance Cartography” is another.
Even that simple structure beats a folder of documents. A search for SuperHarness retrieves files containing the word, while a graph can also follow the authors, projects, decisions, artifacts, dependencies, and evidence related to it.
The simple picture breaks down when the system needs to reason over real work.
Was the relation observed or inferred? Which source supports it? When was it valid? Did a later event expire it? How confident is the extraction? Does the relation belong to one customer, one project, or the public corpus? Is the object a claim, an event, a policy, or a generated guess?
None of those distinctions can live safely inside one unlabeled line.
A metagraph adds typed objects and relations around the graph. A claim can point to supporting episodes. A workflow can point to the artifacts it consumed and produced. A decision can point to the evidence available at the time. A later correction can invalidate a fact for current use while preserving the historical record.
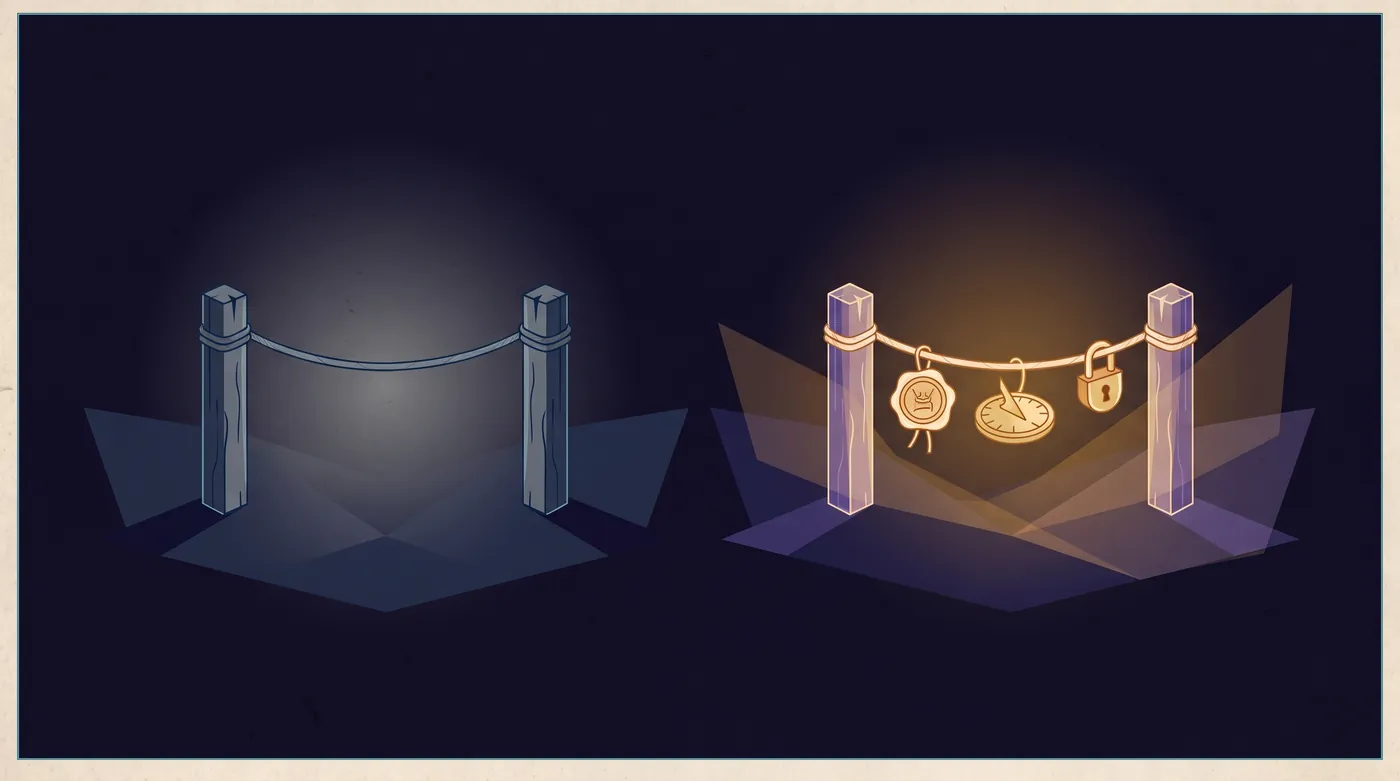
The model records how knowledge moved and which claims still need checking.
The extra structure preserves what accompanied a decision. A graph can show that an opportunity connects to a proposal. A hyperedge can bind the opportunity, buyer, proposal version, evidence package, and submission event into one encounter. A metagraph can make that encounter addressable, then attach its confidence, timing, source, evaluation, and later buyer response. The relationship becomes something the system can inspect and revise.
The rejected routes stay available too. If several proposal angles survived research and one was sent, the others don't vanish, and a later objection can strengthen one of them. A contradiction doesn't overwrite the original claim. It becomes a visible conflict with its own source and time. A maintenance pass can then lower confidence, mark the relation stale or reopen the decision. The graph stores representations of the territory. The correction loop keeps those representations useful.
Facts need clocks
Suppose the system stores “Product A costs $99.”
The statement may be well sourced and still fail tomorrow. A price record needs the time, market, currency, plan and source for that price. Later evidence should create a new state and close the old one rather than overwrite history or leave both prices active forever.
Temporal knowledge systems attach validity to facts and episodes. The operator can ask what the system believed on a date, what is current now, and which event changed the state.
Clocks matter far beyond prices. A person changes roles, a company changes names, a tool removes a feature, and a customer objection becomes less common. A voice changes, a job post goes cold, a policy expires, and a relationship moves from proposal to interview to verbal yes to silence.
The map should represent those state changes directly.
Probability and confidence add another clock-like dimension. “This objection causes churn” may begin as a hypothesis, strengthen after several verified cases, narrow to one segment, then weaken after the product changes. The claim's history is part of the knowledge.
Provenance lets another operator inspect the derivation
Provenance answers where something came from and what happened to it.
A generated brief may derive from a transcript, three research reports, a database query, and an evaluator's correction. A provenance trail can record those inputs, transformations, authors, tools, and timestamps, so another operator can reconstruct the route.
The trail doesn't prove the output is true. Git Kept Every Copy follows the same principle through source history: keeping the route makes a correction inspectable even when it can't make the earlier state correct.
A false source can have perfect lineage. A flawed transformation can be documented precisely. A citation can exist and still fail to support the sentence beside it. Provenance makes inspection possible, but evaluation still has to test the claim.
Keeping provenance and truth apart stops the graph from dressing up as an authority. The system can say, “Here is the source and path,” and then let a human or a tested rule decide whether the evidence is sufficient.
Access checks enforce the scope a namespace identifies
One engine may support several projects or customers, so the shared model needs addresses.
A namespace can scope documents, entities, facts, workflows, voice models, and outputs to a tenant or project. Public research may be available to many namespaces. Customer files may stay inside one. A reusable evaluation rule may apply everywhere. A tenant-specific conclusion may never cross the boundary.
The namespace does more than filter a screen. Retrieval, generation, evaluation, export, retention, and deletion all need to respect it.
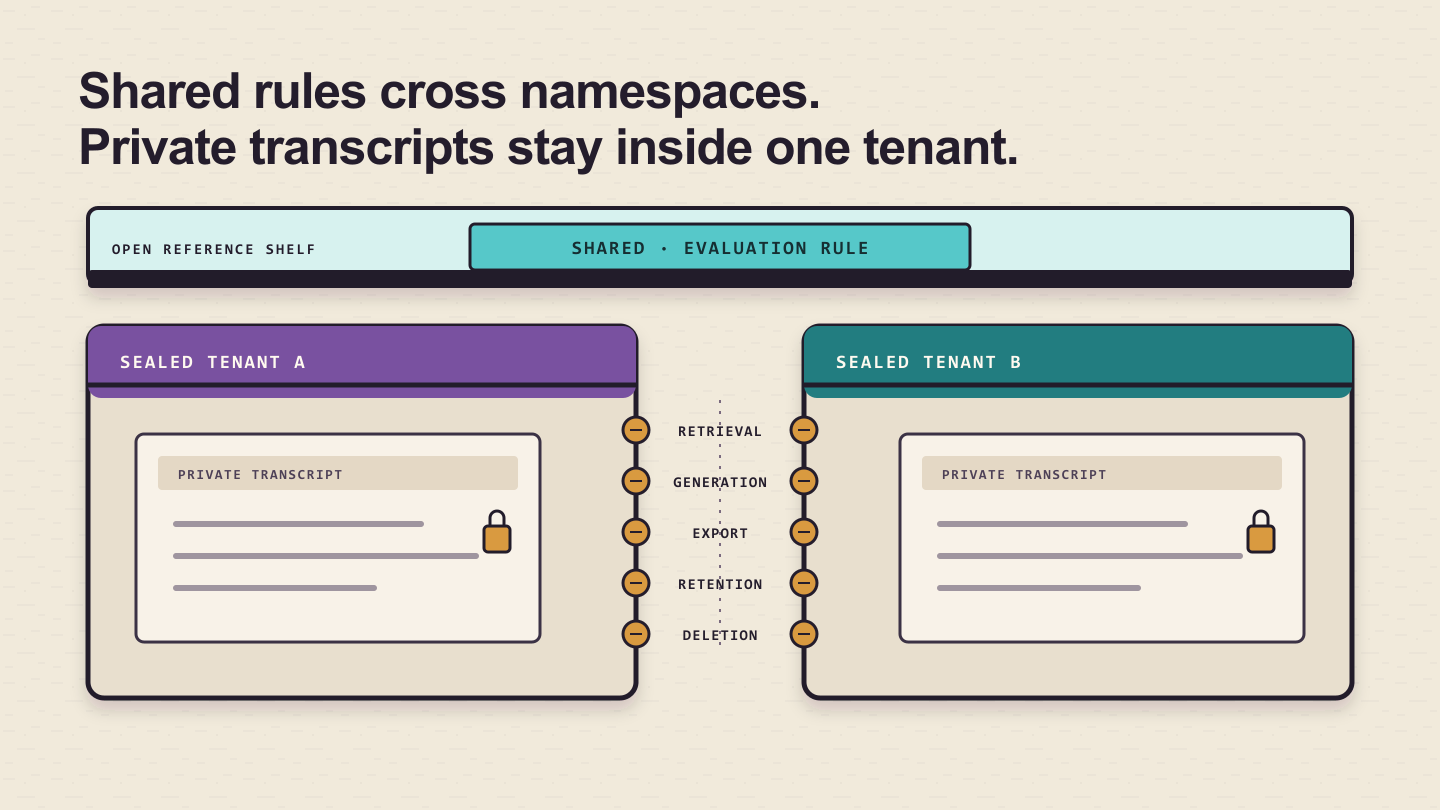
Namespaces identify which customer or project a record belongs to. Access checks must enforce that scope at every operation; the label alone can't prevent a leak.
A map view is a query with a purpose
Once the underlying relations are preserved, the system can construct views for different decisions.
A sales view may show open opportunities, last contact, confidence, expected next event, and deal rot. A content view may show audience questions, source coverage, existing assets, distribution results, and drift. An operator view may show workflows, dispatches, receipts, evidence, and reopen actions. A voice view may show recurring phrases, syntax patterns, topics, and changes over time.
Each view is deliberately smaller than the metagraph.
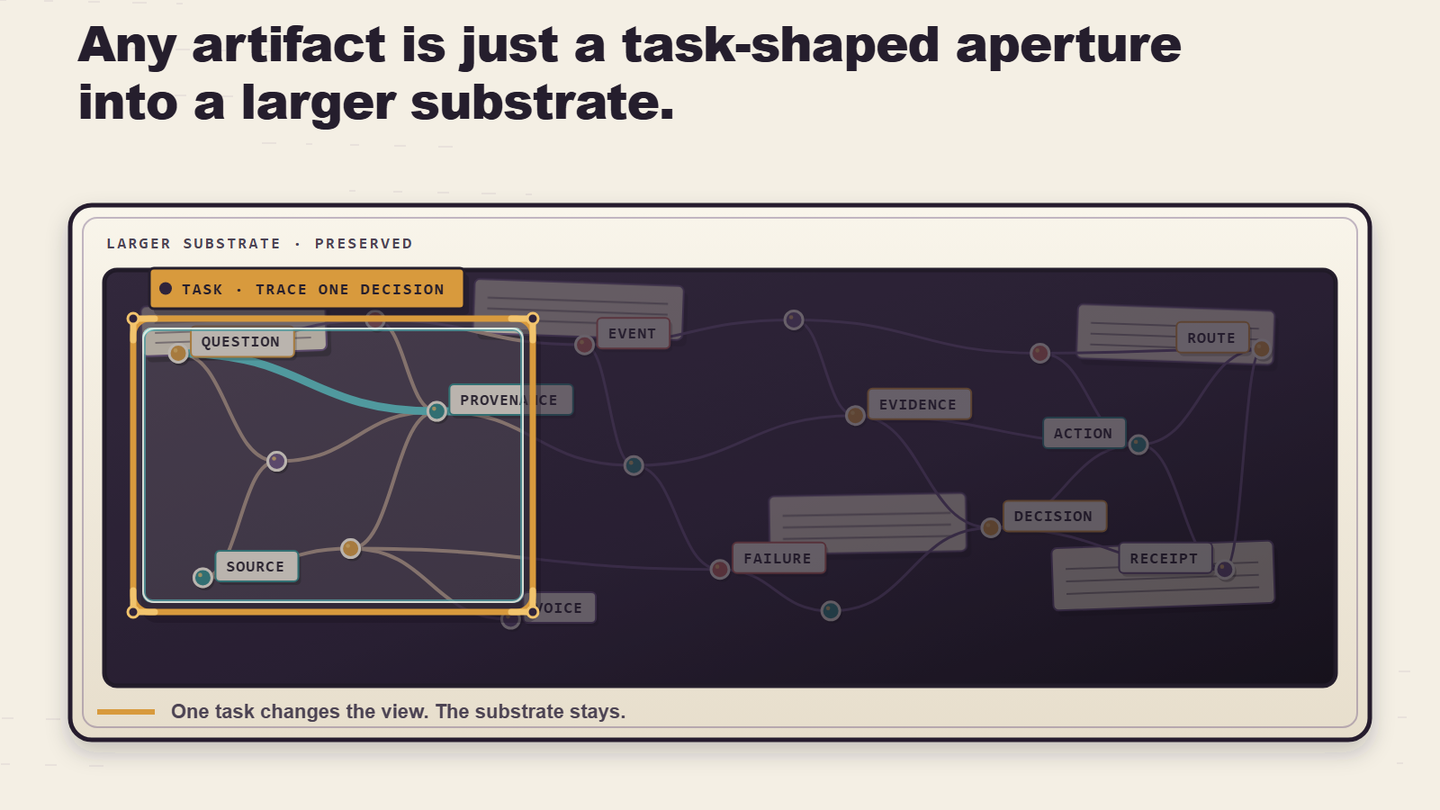
The operator should see the few objects and relations needed to understand, decide, and act. The system beneath the surface keeps the larger context available for inspection. Shape of Data: Ceiling explains the consequence: a view can't answer a question when its underlying representation discarded the required distinction.
The metagraph therefore works as the address system for many useful maps, not as one giant visualization.
Temporal memory and source structure are different instruments
Two graphs can contain some of the same names and still answer different questions.
Graphiti is a temporal memory system. It receives episodes, extracts entities and relations, keeps source links, and allows facts to gain or lose validity as the world changes. A useful query asks what the system currently remembers about an entity, which episode supplied a relation, or which later event superseded an earlier fact. RAG Systems goes deeper on retrieving a bounded contextual world instead of treating memory as a keyword pile.
Graphify maps the structure of a codebase. Its nodes can represent files, components, types, functions, routes, and symbols. Its edges can show imports, calls, ownership, or another structural relation extracted from source. A useful query asks where a dispatch receipt is defined, which components consume an evidence handle, or how an operator shell connects to a workroom.
Graphiti follows meaning through time, and Graphify follows software through a snapshot of a repository.
The difference matters because the two fail in different ways. A temporal memory can remember a stale or badly extracted fact, and a code graph can accurately describe source that never runs. A live database connection can return a healthy status while the human workflow above it stays unusable, and a glowing graph can make every one of those conditions look complete.
Hyperrelevance Cartography keeps the instrument's identity attached to every return. A Graphiti result is a memory return, a Graphify path is a source-structure return, a browser recording is a human-journey return, and a Git commit is a source-history return. None of them quietly gets promoted into another.
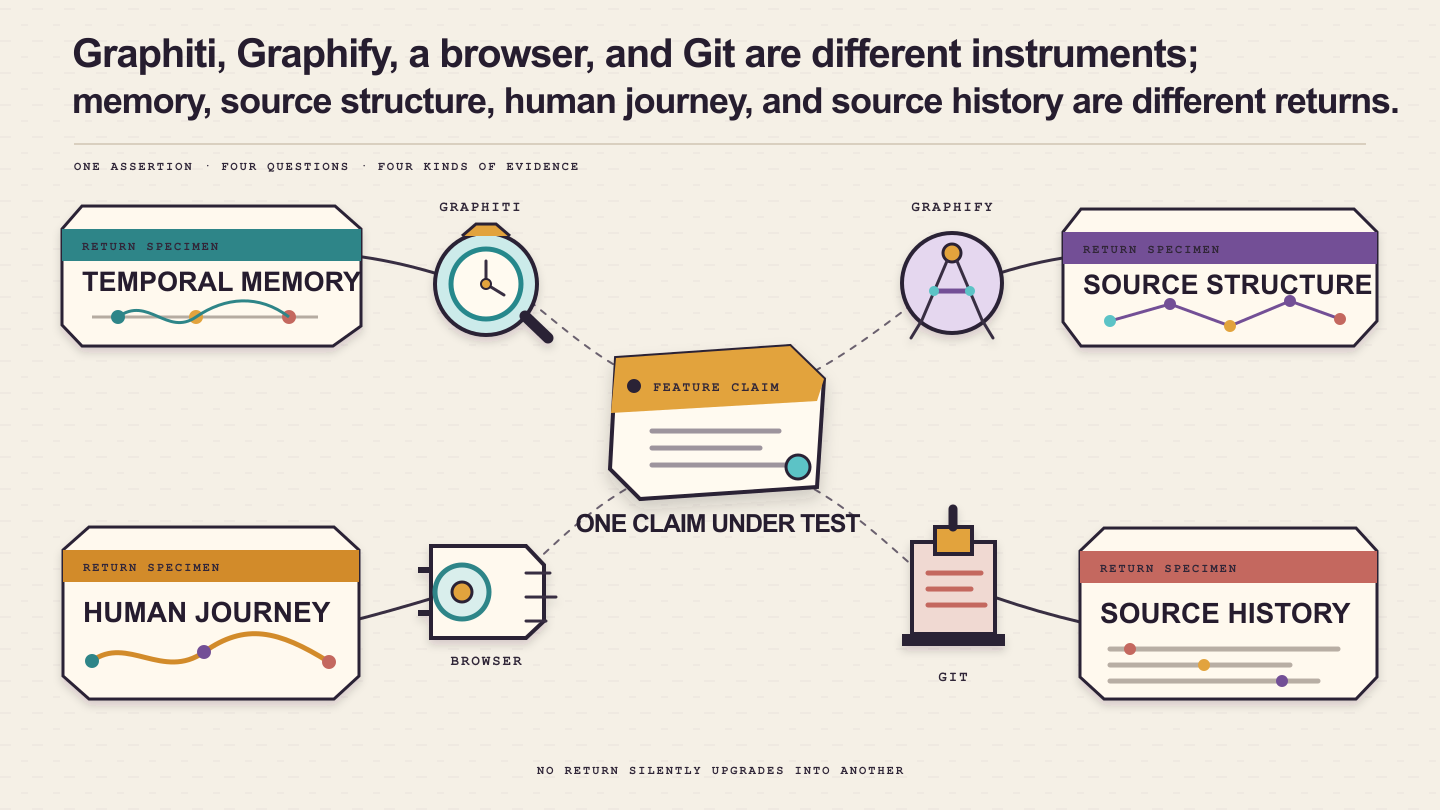
Keeping them separate lets the instruments correct one another.
If memory says a feature is live, a source query can locate the implementation and a browser test can verify the journey. If source contains a component with no route, the graph can reveal the disconnected edge. If a browser shows a result with no receipt, the operator can see that the experience lacks a durable return path.
The metagraph can link all three without flattening them. A feature node can point to an intended requirement, an implemented source path, a runtime observation, and a human acceptance result. The operator can see which evidence supports each status.
Five labels keep the map truthful
Complex systems need plain status words.
A result is observed when a current instrument returned it: a page rendered, a service answered, or a file contained an exact value.
A mechanism is implemented when current source contains a coherent version of it, even if it still lacks a reachable route, a valid configuration, real data, or browser proof.
A mechanism is specified when a canonical design defines it and its intended behavior. A specification gives a team a shared target without creating the target.
Evidence is historical when it describes an earlier state, an expired fact, an old name, or code on a lineage the current product doesn't contain.
A conclusion is inferred when several pieces of evidence support it and no direct observation has proved it yet.
The labels prevent a common collapse. A diagram begins as a specification, a component makes the idea implemented in source, and a health response makes one boundary observed. A screenshot then gets used as proof that the whole system works.
Each step may be real, yet the conclusion can still outrun the evidence.
The labels apply separately to a product's parts. AgentOS, the human-facing application over the agent execution system, needs both an implemented mechanism and an observed dispatch-and-reopen journey. Meme Shaman, the proposed humor-production product discussed later, needs a tested path from ingestion through approval to an audience return. Neither product's status follows from the existence of a diagram, asset or component.
The label belongs to the claim, not the product name. One feature can move from specified to implemented to observed while another feature beside it remains a concept. A product-level badge hides that grain.
The observed, implemented, specified, historical and inferred labels also apply to public writing. Readers can see what exists, what the evidence showed, what follows from the evidence, and what remains a proposal. That boundary makes the vision more credible, because a future state no longer has to dress like a present fact.
6. Voice measurements give an editor evidence
A family-portrait studio rejected AI-written campaign copy. The case record describes comparing the client's real writing with the generated work, rebuilding the campaigns against a measured fingerprint, and delivering a drag-to-compare view of the before and after.
The rebuilt campaigns were accepted, according to the studio case record. Acceptance belongs to that work for that client. It doesn't prove that a distance score can decide whether any future piece carries the right judgment.
Written voice includes vocabulary, sentence length, grammar, rhythm, favorite examples, repeated transitions, directness, humor, subjects and the way those change with context. A voice fingerprint measures parts of that pattern so a production system can compare new work with authorized samples. The comparison gives the editor something specific to inspect; the writer and client still decide whether the piece says what it should.
The fingerprint should describe the voice without flattening it.
Vocabulary is one layer
Word counts reveal recurring nouns, verbs, phrases, and avoided terms. Named-entity recognition reveals the people, companies, products, places, and projects that populate a person's world. Parts-of-speech analysis can show whether the writer favors concrete nouns, active verbs, qualifiers, questions, or abstract nominalizations.
Those measures help, but a bag of words can't carry voice.
Two people can use the same vocabulary with different sentence pressure. One builds a long setup and lands a short verdict while another stacks short clauses. One uses examples to teach and another uses them to challenge. One names pain from lived experience and another describes it from outside.
The system needs patterns across levels.
Syntax, rhythm, and register carry intent
Sentence structure shows how the writer moves attention, and paragraph length shows where the writer breathes. Transitions show how one thought earns the next, and formatting shows what the writer expects scanners to notice.
Writing style changes with the job.
An Upwork cover letter is flat text read beside dozens of competitors. A Field Note can use headings, links, figures, and longer argument. A technical handoff needs precise identifiers. A voice memo can wander while discovering the point. Treating all four as one style produces a polished average that belongs to nobody.
The fingerprint therefore includes the situation: who is speaking, to whom, for what purpose, on which surface, and under which constraints.
Drift is part of the identity
A person changes after doing more work.
New projects introduce vocabulary. Repeated failures sharpen explanations. Overused phrases become irritating. A public style guide may ban a construction that appears throughout older samples. The current voice is a path, not a centroid over everything the person ever wrote.
Analysis over time keeps the system from reviving old habits and calling them authentic.
A drift audit compares recent work with earlier periods. Which phrases increased? Which sentence structures disappeared? Which subjects became more concrete? Which metaphors survived because they still teach? Which patterns now read like the generic AI dialect the writer learned to reject?
The operator updates the voice model and keeps its history.
Voice fingerprinting needs consent and proof
Using a voice model requires permission for the material and the intended use.
Generated work in a person's voice can imply that the person authored it. The system should know whose material it's analyzing, which uses are allowed, who approves publication, and how generated work is labeled inside the production process.
Evaluation should compare output against current, authorized samples. It should also ask whether the piece carries the person's judgment. A perfect imitation of surface rhythm can still put words in somebody's mouth.
The goal is supported authorship: help a person express more of what they mean with consistent craft and inspectable review.
Execution comes next, once the world model and the voice model exist. Research has to become a working artifact, survive review, leave evidence, and stay reopenable after the chat window closes.
7. The data model is the first map
A crowded workshop can hide a bad design for a long time.
At first every bench has a tool, every tool has a label, and the operator can point to any object and say what it does. Then the work grows. One tool needs a second handle, another needs a private drawer, and a third needs a special power cable. Soon every bench carries its own rules, storage, and behavior. The workshop still looks organized from the doorway, while inside, every new job needs somebody who remembers which object is allowed to touch which other object.
Software can grow the same way.
A game engine built around a tree of rich behavior objects feels friendly when a scene is small. A character node can hold movement, animation, collision, health, inventory, and events, and the object is easy to find. The design gets expensive when thousands of objects need the same narrow operation. The engine may have to visit thousands of separate objects, cross boundaries, repeat checks, and move data between systems before it can answer a simple question such as, “Which moving units are poisoned?”
The shape of the data controls which operations stay simple as the work grows. Unified Architecture carries that question into the boundaries between shared data, components, and the surfaces that consume them.
The god object feels helpful until the world gets large
A god object is one thing that knows too much and does too much.
Imagine a customer record containing contact details, purchase history, ad behavior, consent, writing style, risk score, project state, billing rules, campaign membership, and every method that acts on those fields. The record feels complete, but it's hard to reuse safely. A reporting system needs two fields and receives the whole object. A personalization system wants current language preferences and accidentally inherits billing assumptions. A deletion request can affect one record and the other services connected to it. Over time the record becomes the unofficial operating system.
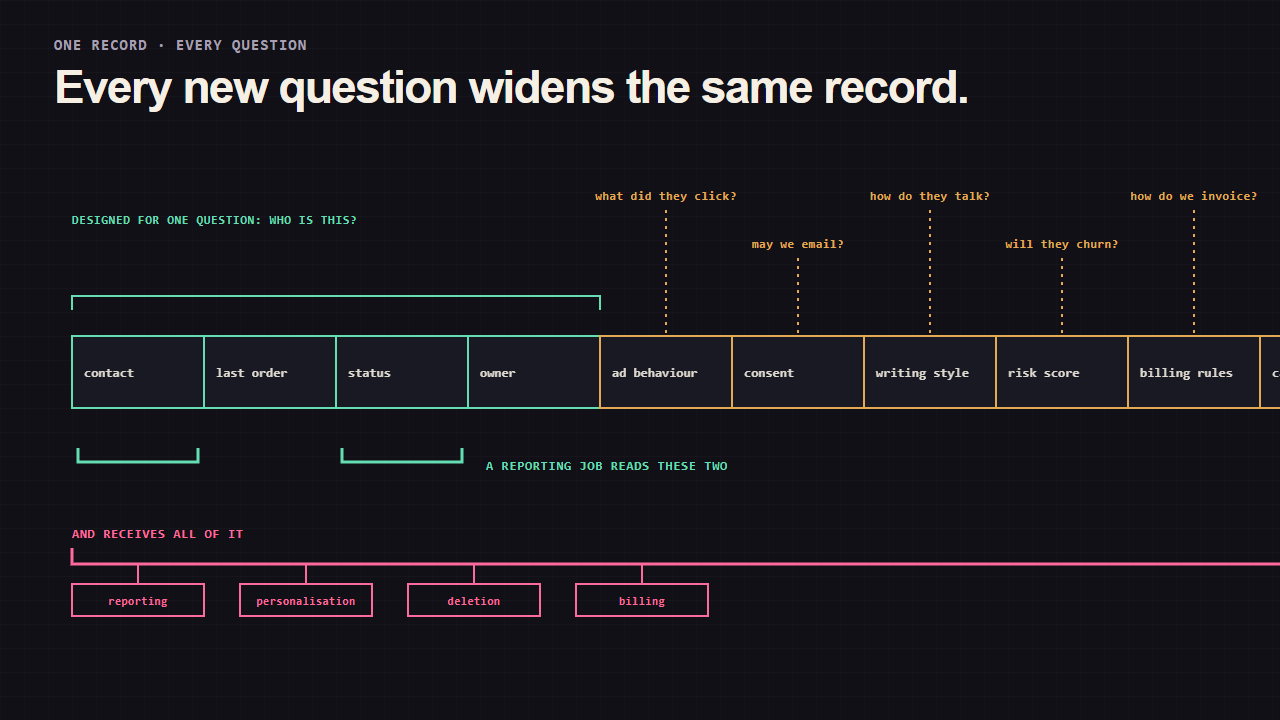
The failure is common because the local convenience shows up before the global cost. The first developer saves time by attaching one more responsibility to a thing that already exists. The twentieth responsibility arrives months later, after other systems depend on the first nineteen. Nobody planned a god object; the organization kept choosing the nearest shelf.
The same problem shows up outside code. “Small-business owner” becomes a persona containing industry, budget, urgency, tool preference, approval behavior, vocabulary, technical skill, and risk tolerance. “Good opportunity” becomes one score that quietly mixes fit, value, freshness, client reliability, competition, and proof requirements. “High-performing content” becomes a label that blends attention, traffic, conversion, revenue, and strategic usefulness.
Each label compresses several different questions into one object, and the object looks clear because its internal disagreements have dropped out of view.
Hyperrelevance Cartography pulls those dimensions apart, preserves their relations, then creates a smaller view for the decision at hand.
Components make composition visible
The entity-component-system, a pattern from game engines, offers a useful alternative.
In ordinary language, an entity identifies one thing. Components hold pieces of data about it. Systems select the entities carrying the components needed for one operation, then read or change that data. The separation keeps identity, data, and behavior from becoming one inseparable bundle. Unity's ECS documentation describes that mechanism directly.
A game unit may have position, velocity, health, and faction components. A movement system needs position and velocity, a damage system needs health, and a targeting system may need position and faction. The unit doesn't need a private copy of every behavior, because each system asks for the smallest useful combination.
Applied to a business, this stays an analogy unless the software actually stores and queries data this way, but it's still a precise analogy.
An opportunity can have source, freshness, budget, fit evidence, client history, stage, last event, expected next event, proposal assets, and uncertainty components. A deal-rot view needs stage, last meaningful event, promised timing, and current date. An asset-selection system needs opportunity type, proof threshold, time budget, and available evidence. A market-regime view needs many opportunity scores over time, not the full private record for each client.
The opportunity stays one address, and different systems work through different slices of it.
Splitting the record this way reduces accidental coupling, and it makes absence visible. If an opportunity lacks a hiring-history component, the scoring system can mark that evidence unknown instead of quietly inventing a neutral value. If consent is missing, the voice system can refuse to use private transcripts. If the last meaningful event is absent, deal rot becomes uncomputable rather than falsely green. Unknown becomes a piece of data like any other.
Data-oriented design starts from the repeated question
Data-oriented design asks what work happens repeatedly, then arranges the needed data so that work stays simple and efficient. Unity's data-oriented design guide makes an important point: choosing an entity-component-system doesn't automatically create good performance. The design has to match the real access pattern.
The warning applies to hyperrelevance work too. A beautiful graph can still store the wrong objects, and a flexible schema can still make common questions slow and ambiguous. A hundred specialist agents can spend most of their time translating incompatible payloads, and a typed system can encode a bad assumption perfectly.
Start with the repeated decision.
Which opportunity deserves action now? Which proof belongs in this proposal? Which fact is still valid? Which audience segment changed? Which asset contributed to an interview? Which client needs a human reply? Which workflow can proceed without approval?
Then ask what data those decisions require, where the data comes from, how long it remains useful, and which system is allowed to change it.
That's cartography before software: the terrain is the work, and the data model is the first map of that terrain.
A typed intermediate representation gives the fleet one language
A compiler doesn't ask every later stage to understand the original source in its raw form.
The compiler parses the source into an intermediate representation, often shortened to IR. The IR gives later stages a shared structure, so an optimizer, validator, code generator, debugger, and visualizer can work from the same defined objects without each one rebuilding the meaning from loose text.
Agent systems need the same middle language.
Take a saved job post. The raw post is evidence and should stay preserved, and the system also needs a typed opportunity model. That model might name the source, buyer, stated objective, inferred problem, budget evidence, fit evidence, risk, stage, next expected event, allowable assets, and unresolved questions. The exact fields are private implementation, and the public principle is simple: each field has a meaning, a type, an authority, and a rule for absence.
The typed model becomes a contract between surfaces.
The scraper can produce it, the database can store it, and the CRM can display it. A scoring system can read bounded fields, a proposal workflow can request an asset plan, and an evaluator can inspect evidence. An event stream can record changes, a client report can summarize approved outcomes, and a deletion process can find related private material.
Without the shared representation, every boundary becomes a translation project.
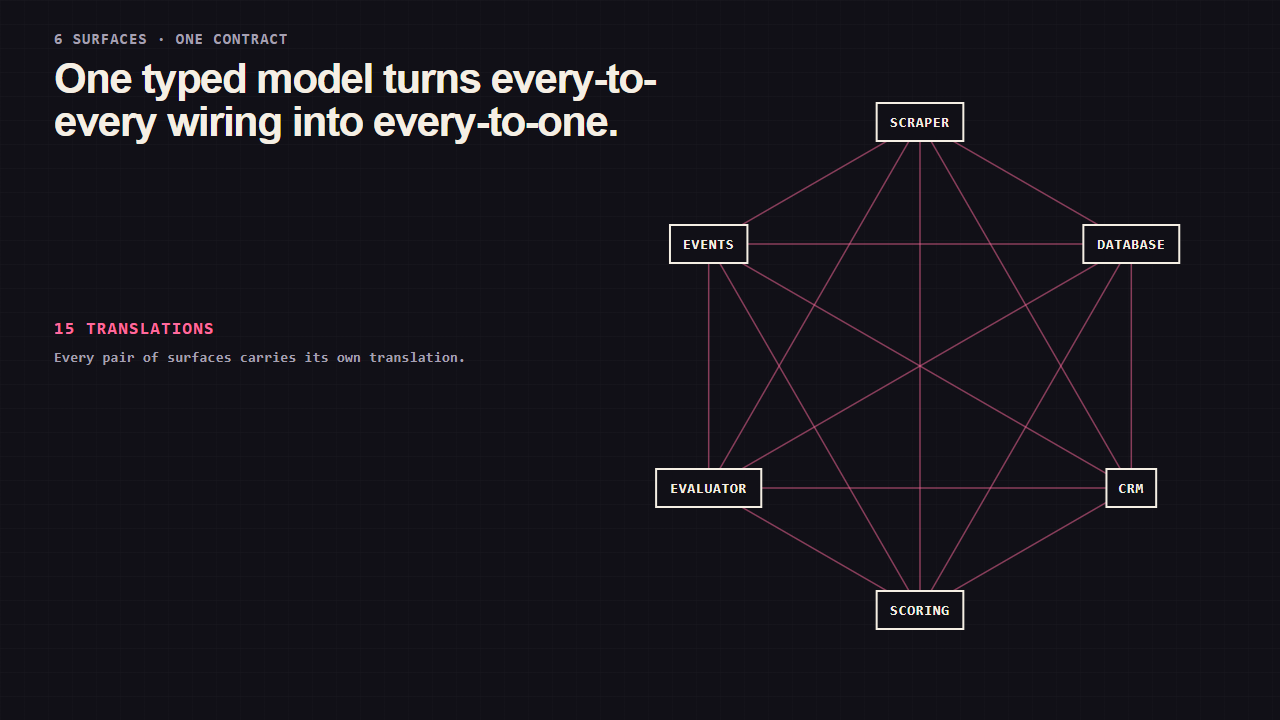
One agent calls the buyer's desired result an outcome. Another calls it a goal, and a third hides it inside analysis text. The interface expects objective, and the evaluator searches for success_condition. Nothing is necessarily wrong in isolation, yet the system still loses meaning through small mismatches.
A typed IR makes those mismatches harder to introduce and easier to detect. It doesn't make errors structurally impossible: a field can be wrong, a type can be too broad, and a validator can pass a false claim. What the contract creates is an inspectable place where meaning can be corrected once for every consumer.
Repeated translation can consume the production advantage
Performance arguments about game engines often focus on the cost of crossing boundaries.
One runtime owns gameplay objects and another owns rendering or physics, so data crosses a foreign-function interface. Each crossing may require marshaling, copying, conversion, synchronization, or a lookup that breaks the processor's easy path through nearby data. A single crossing can be cheap, but millions of poorly shaped crossings become the work.
Agent systems pay a semantic version of the same tax.
An opportunity starts as a job-post document. A research agent rewrites it into a memo. A proposal agent extracts a new summary. A visual agent receives a prompt describing the summary. An evaluator sees the output with no direct source link. The operator then explains the missing context in another transcript.
Each stage may use a capable model, yet the pipeline still spends its advantage on translation and reconstruction.
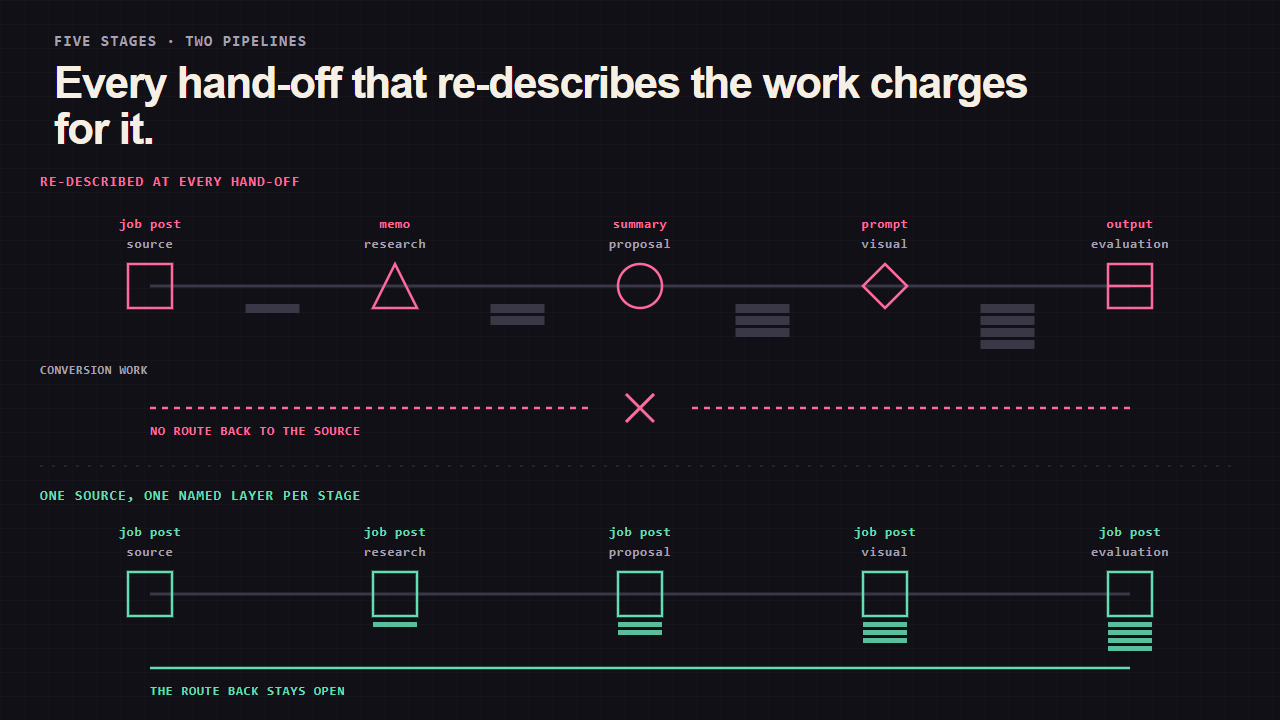
The remedy is controlled derivation. Preserve the raw source, produce one typed representation, and let each activity add a named layer with provenance. Give the next stage the smallest sufficient view plus a route back to the evidence, and record every consequential change as an event.
Now the boundaries carry contracts instead of folklore.
Model Context Protocol, or MCP, can help tools expose defined operations and resources to models, but it doesn't supply the domain model by itself. Connecting a database, browser, or file service solves access. The harness, the layer that runs the agents, still has to decide which specialist receives which tool, which typed input is valid, what authority the operation carries, what evidence returns, and what event ends the work.
Connecting a tool is plumbing, the IR carries the shared meaning, and the harness carries the authority.
Pools often reveal a lifecycle problem
Object pooling is another useful game-engine clue.
A system creates a group of objects ahead of time, turns them on when needed, and turns them off instead of repeatedly creating and destroying them. Pooling can be a sensible optimization. It can also reveal that object birth and death are expensive because each object carries more lifecycle machinery than the operation needs.
Knowledge work develops human versions of pools.
Teams copy last month's campaign, rename last quarter's dashboard, duplicate a proposal document, or keep a collection of half-configured automation templates. The pool saves setup time. It also carries hidden state. A forgotten recipient list, stale claim, old price, wrong client name, or expired permission survives because the copied object contains more history than the new operation requested.
Component-level reuse is safer.
Reuse the verified case-study entity, the current pricing rule, the approved voice sample, the animation component, the citation, or the evaluation contract. Assemble a new opportunity package from authorized parts. Keep lineage so the system can learn which parts travel well and which should be retired.
The aim is to make reuse observable, not to reach purity.
Architecture and tooling mature at different speeds
A system can have a strong internal architecture and a weak operator experience.
SuperHarness and AgentOS name the two layers in this design: execution and coordination underneath, a human application above. The execution layer needs dispatches, profiles, receipts, evidence and re-entry. The application has to let a person launch, inspect, decide and reopen. Source can contain the right objects while the joined human workflow remains unproven.
A game engine can face the same split. A data-oriented core may support large simulations while its editor, visual debugging, asset workflow, or learning curve remains less mature than a friendlier alternative. The architectural bet and the tooling gap can both be real.
The right response is to sequence the work truthfully.
Build one vertical slice that crosses the real boundary. Show one opportunity entering as evidence, becoming a typed model, receiving specialist work, returning a native receipt, appearing in an operator surface, accepting a human decision, and reopening later. Fix the parts of the toolchain that block that slice, and expand only after the shared path works, since architecture earns its value through use.
Defaults determine what the ordinary workflow permits
Most system behavior comes from the easiest path.
If the easiest path is a free-form prompt, important fields become optional. If the easiest path is copying an old document, stale context propagates. If every agent can use every tool, authority becomes vague. If evidence is an optional attachment, successful-looking outputs arrive without proof. If the interface rewards launching work and hides reopening, the organization produces activity without durable learning.
Good architecture changes the default.
An opportunity can't reach proposal generation without an evidence-bearing source. A consequential claim can't become verified because it has a citation-shaped string. A specialist receives a bounded profile. A workflow can't mark itself complete without its named event. A human decision changes durable state. A later operator can reopen the artifact and receipt.
The guardrails still need escape hatches, because real work has exceptions. An authorized person should be able to override a rule, record why, and make the exception visible to evaluation.
Enforcing an architecture changes what the ordinary path permits. Architecture theater describes a preferred future while every active workflow keeps running through the old shortcut.
The data model is therefore a statement about which distinctions the organization refuses to lose, as much as a storage decision.
Marketing has flattened one of those distinctions for decades: the difference between a population and an average person.
8. A population model preserves differences a persona hides
Meet Average Alex.
This deliberately fictional Alex has an average age, household size and income, plus a preference for educational content, quality and convenience. Alex appears in a slide deck beside a stock photograph and a paragraph about pain points.
Alex may describe no person who has ever lived.
Every individual average can be correct while their combination lands in a thin part of the real population. A group can contain younger people with larger families and older people living alone. Combining the average age and average household size creates a neat character who resembles few members of either group. Add average income, average urgency, average technical skill, and average proof threshold, and the persona becomes a statistical costume.
The problem is conditional, not universal. Some averages describe a useful center. Others collapse several clusters into a point where little real behavior occurs. The map has to inspect the shape before trusting the center.
A person's behavior changes with the conditions
A human being isn't a bundle of fixed marketing traits.
The same person can be price-sensitive on Monday and speed-sensitive on Friday. A failed purchase changes the proof they need next time. A referral changes trust before the landing page loads. A deadline changes which feature matters. A child, manager, spouse, regulator, or teammate can enter the decision. Language changes across a technical forum, a family chat, a procurement call, and a search box.
The changed-condition example showed why history changes an available route. A population model retains those histories across the people it describes.
The system can store observations and conditions instead of a permanent type such as “skeptical buyer.” This buyer abandoned a similar migration after a broken promise. This buyer has internal engineering help. This buyer needs a board-ready explanation. This buyer used a phrase associated with a recent platform change. This buyer viewed the proof page twice and never opened pricing.
Some fields are directly observed, some come from the operator's recollection, some are reasonable inferences, and some are simulations used to explore a decision. Each field's evidence class has to stay visible.
The richer model gives the system a way to stop pretending that one static card contains the person, and it gives no permission to claim the system knows a person better than they know themselves. The Mirror Ocean explores the deeper problem of modeling another person's model without confusing the simulation for the person.
The persona card is a god object
Traditional personas mix identity, context, desire, behavior, language, and prediction into one narrative object.
Mixing them makes the card easy to present and the model hard to test.
If the campaign fails, which part was wrong? Was urgency overestimated? Was the vocabulary stale? Did the source audience differ from the interview group? Did a price objection actually hide an authority problem? Did the landing page attract one subgroup while the survey described another? The persona offers a story, not a set of separable claims.
An entity-component view creates inspectable parts.
The entity can represent a person, organization, account, session, or simulated specimen. Components can represent observed constraints, current objective, channel context, vocabulary, proof threshold, prior events, timing, authority, confidence, and consent, and systems can query the slice one decision needs.
A headline test may need problem language, awareness level, channel context, and proof threshold. A pricing experiment may need budget evidence, urgency, decision authority, and prior objections. An email sequence may need consent, relationship stage, recent events, and response history. None needs the complete fictional biography of Average Alex.
Breaking the persona apart also protects people from careless essentialism. Demography can matter when the evidence and the decision justify it, but it shouldn't quietly become destiny. The model can favor behavior and context while keeping protected or sensitive traits behind stricter authority.
Local conditions produce different responses within a city
City-building games make this idea visible.
A city doesn't behave like one average resident. Neighborhoods contain mixtures of household types, travel patterns, jobs, land values, services, preferences, and constraints. A road change affects commuters differently from nearby shop owners, and a new school changes a district differently from a warehouse zone. What the city visibly does emerges from many local states interacting with shared systems.
Hyperrelevance Cartography can use the city as a laboratory.
In that laboratory, streets are channels, buildings are organizations or households, and residents are evidence-bound specimens. Utilities are platform dependencies, zoning is a policy constraint, congestion is competition for attention, and weather and construction are regime changes. A campaign changes one part of the environment, and the system watches how different groups respond.
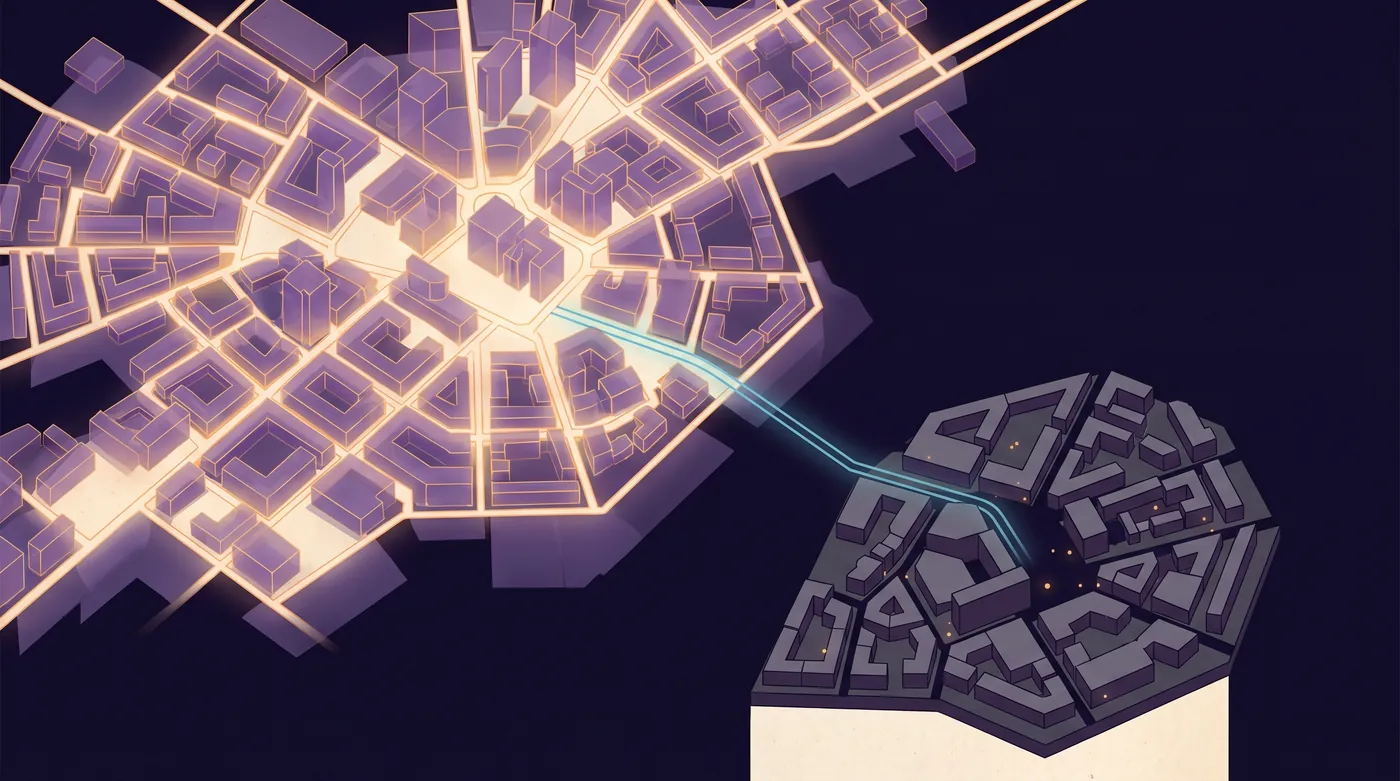
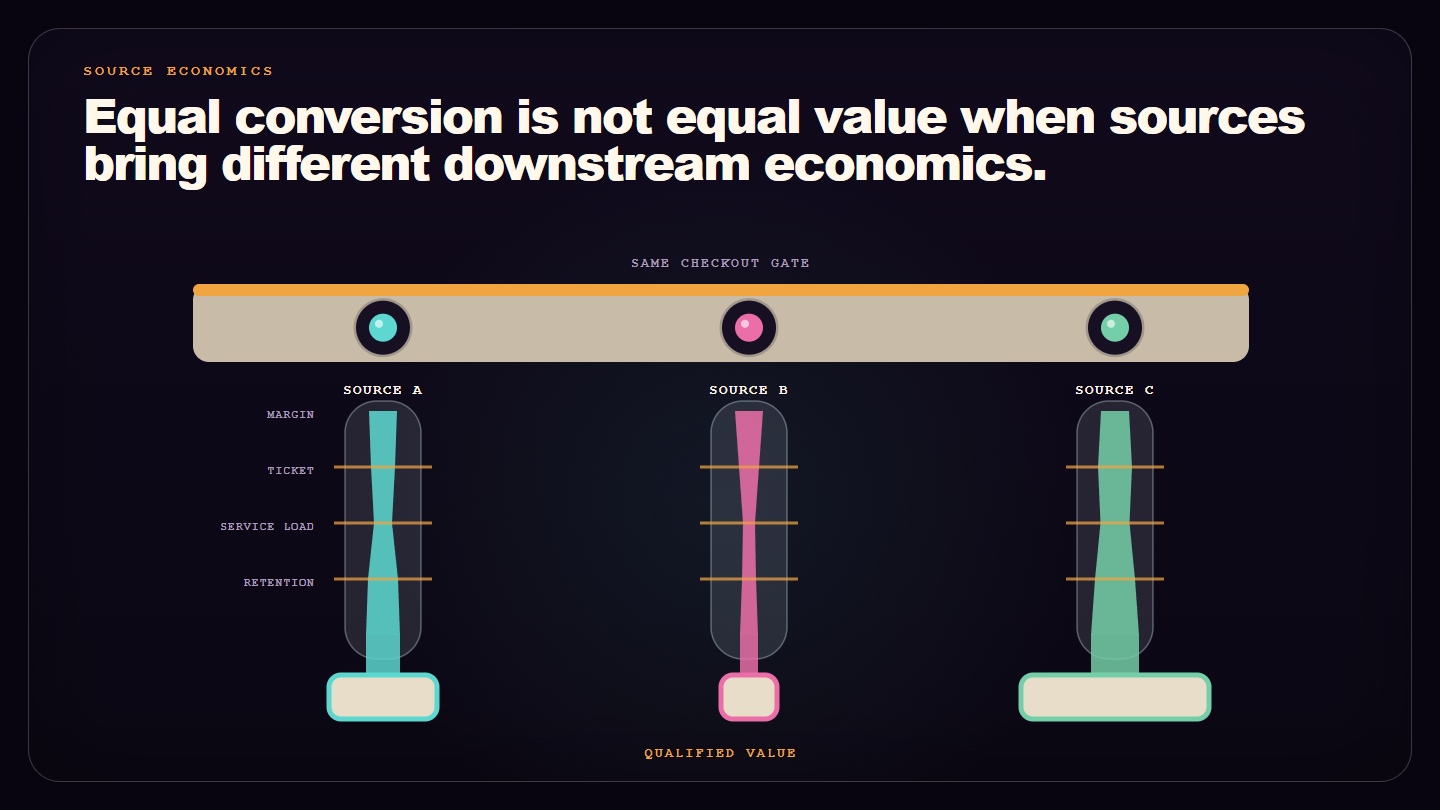
The city picture blocks one dangerous shortcut. A citywide average can improve while one neighborhood collapses. A funnel-wide conversion rate can improve while a high-value segment leaves. A campaign can create more leads while lowering the supply of customers who fit the service.
The map needs local views and aggregate views together.
A simulation assembles declared conditions for a test
A Population Foundry sounds like a place that manufactures synthetic humans, and that framing invites the wrong behavior.
The useful product is a world forge, which assembles declared conditions for a bounded experiment.
An operator chooses a market question, and the system retrieves current evidence. It identifies measured distributions, missing dimensions, dependencies, and source limits, then produces experiment specimens whose fields are labeled observed, operator-supplied, inferred, or simulated. The system must label each specimen as simulated rather than imply it's a real customer. It claims that this combination of conditions is one test position inside a stated model.
That distinction protects the research.
A simulated specimen can expose the model's assumption that a message works only when buying intent is high and approval is local. A real audience must test that assumption. Another can reveal that a landing page assumes technical vocabulary absent from a low-awareness group. A cluster can show that a single “enterprise buyer” label hides procurement, technical, executive, and operator roles with different evidence needs.
The experiment creates questions for the market to answer instead of replacing the market.
Controlled bias makes the test legible
Every model has bias.
Data collection overrepresents people who were reachable. Interviews overrepresent people willing to speak. Customer records overrepresent people who bought. Social content overrepresents people who posted. Operator judgment reflects earlier work and its consequences. Generated specimens inherit the source corpus, model, prompt, and sampling method.
Pretending to remove all bias hides it.
Controlled bias declares the lens. The operator can say, “Weight recent lost deals more heavily,” “Hold budget constant while varying proof threshold,” or “Construct a stress population with low trust and high urgency.” The model then shows what was changed and what remained fixed.
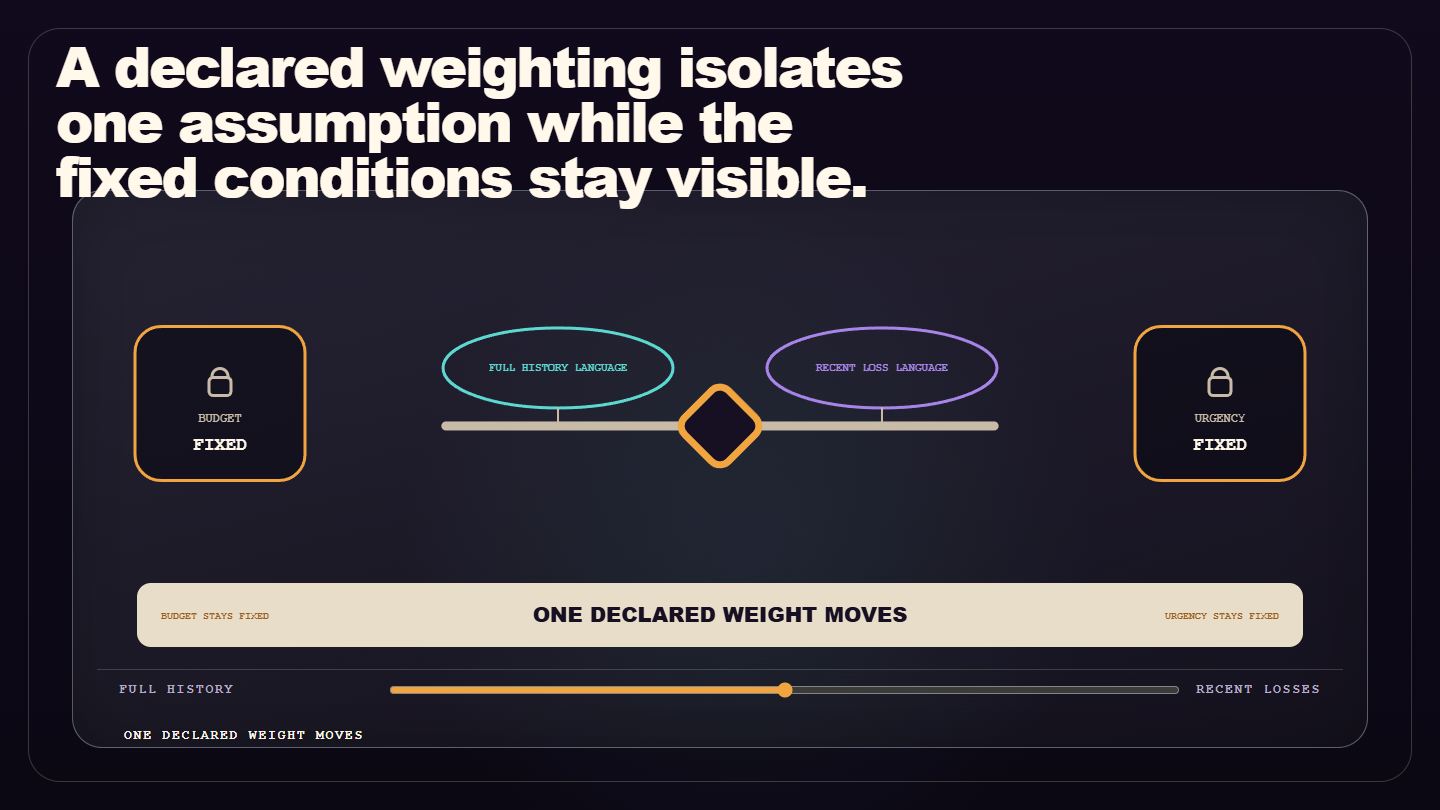
Declaring the weighting makes that choice inspectable as an experimental setting. It doesn't remove sampling or model bias.
The record should also distinguish agent opinions from independent human evidence. Five agents using the same foundation model, source pack, and prompt family may produce five fluent opinions. Their agreement can reveal stability inside that setup, but it doesn't count as five independent market observations, so the system should show their common ancestry.
Bounded specialists can expose different assumptions
A Wardley Swarm can examine one decision from several operational positions.
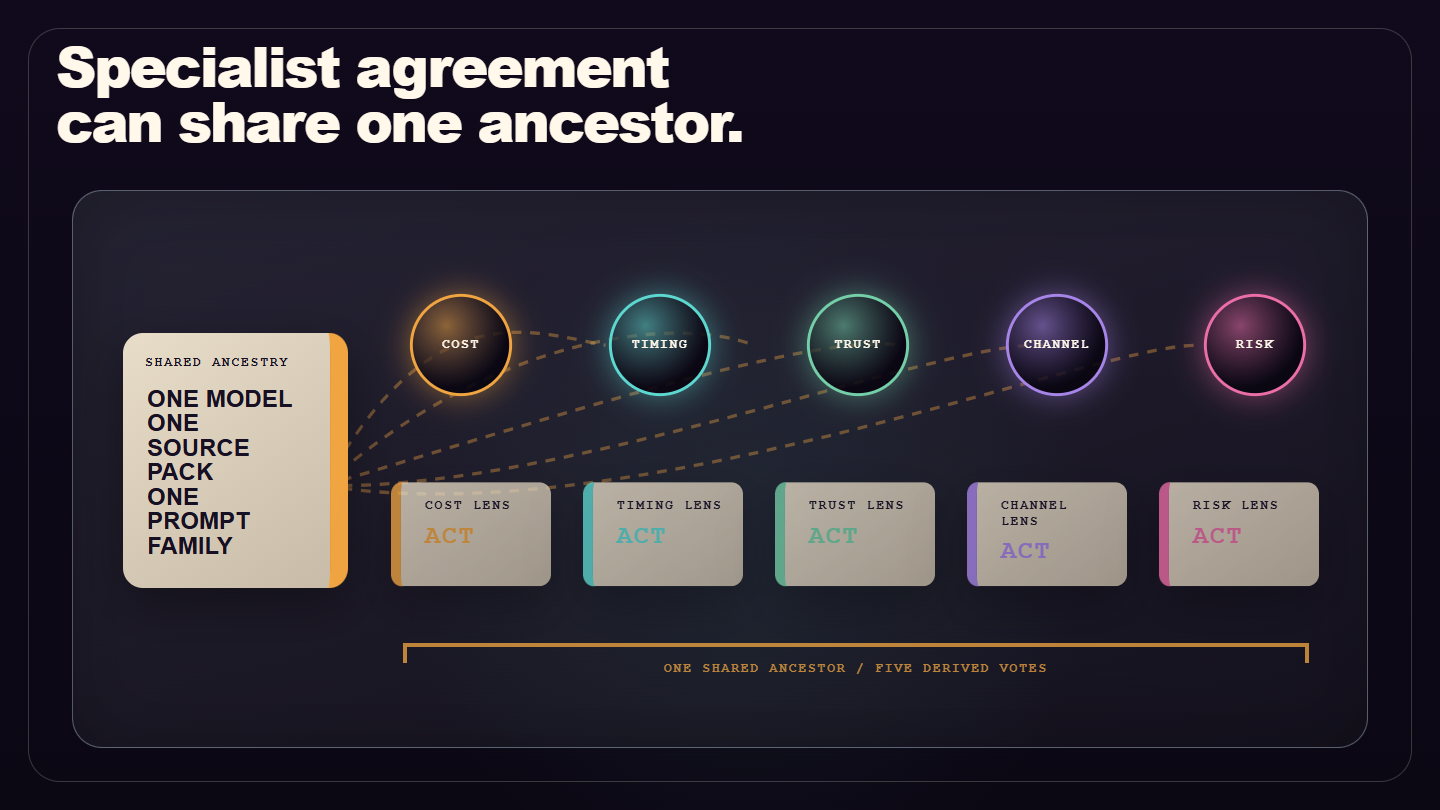
One specialist asks what a buyer is trying to accomplish. Another asks what evidence would reduce perceived risk. Another tests language against current community vocabulary. Another examines delivery constraints. Another challenges whether the proposed intervention can create the measured outcome. An evaluator looks for shared blind spots and unsupported certainty.
Each specialist receives the same typed population model through a different query.
The value comes from structured disagreement. A specialist can say which components drove its conclusion. The operator can see that a message performs well for one cluster and poorly for another. The system can compare the baseline population with one controlled intervention.
The fully populated, drift-monitored, agent-audited version is a design target. It isn't evidence that a population model has predicted real buyer behavior.
A bounded experiment can start with one decision, one source corpus, a few explicit components, distinguishable specimens, one intervention and a real market return. Specialist review earns its place when it challenges a consequential assumption; a committee isn't required to make the first record.
A real return can test that bounded loop before a larger simulation earns its cost.
Conversion optimization begins with the objective
Conversion-rate optimization is often introduced through interface changes: button colors, form length, headlines, and page layout. Those are interventions, not the objective.
The objective may be a completed purchase, qualified reply, product activation, retained account, larger agreement, or lower support burden. Changing the objective changes which population matters and which behavior counts as progress.
An email capture campaign and a purchase campaign can use the same traffic and need different models. A campaign seeking immediate sales may favor high intent and strong proof. A campaign seeking future education may accept lower current urgency and value permission to continue the relationship. A churn-reduction program starts after purchase and needs service events, expectation gaps, and product use rather than acquisition language alone.
The objective works as a reward function only in a bounded sense. It tells the system what outcome to optimize without making every path to that outcome acceptable, and consent, brand promises, margin, service capacity, and long-term trust remain constraints.
A shared population model gives each workflow an authorized view
Ad targeting, landing-page adaptation, email sequencing, sales preparation, and service reporting often build separate customer models.
One system calls a person a custom audience member, and others call the same person a visitor, a lead, an opportunity contact, or a customer. The person crosses those boundaries and loses their history at each one.
A shared typed population object can preserve continuity while exposing only the allowed view.
The advertising surface can use channel eligibility and consent. The landing page can use declared context and current source. The email workflow can use relationship stage and recent events. The sales surface can use organization, objective, proof needs, and authority. The service surface can use promises, deliverables, outcomes, and risks.
That takes one address system, scoped components, namespaces, and purpose-bound access, rather than one giant public customer profile.
The result is a funnel that behaves like one learning system.
A message changes attention. A visit changes observed context. A reply changes the opportunity. A close changes the service relationship. A service outcome changes the proof available for the next market. Each return updates the model that produced the earlier action.
A counterfactual comparison declares what changed
A counterfactual asks what might happen under another condition.
Marketing answers that question badly when it compares this month's campaign with last month's campaign and ignores everything else that changed. Season, price, inventory, channel mix, platform policy, competitive activity, and audience composition may all differ.
The Counterfactual Observatory begins with a comparison contract.
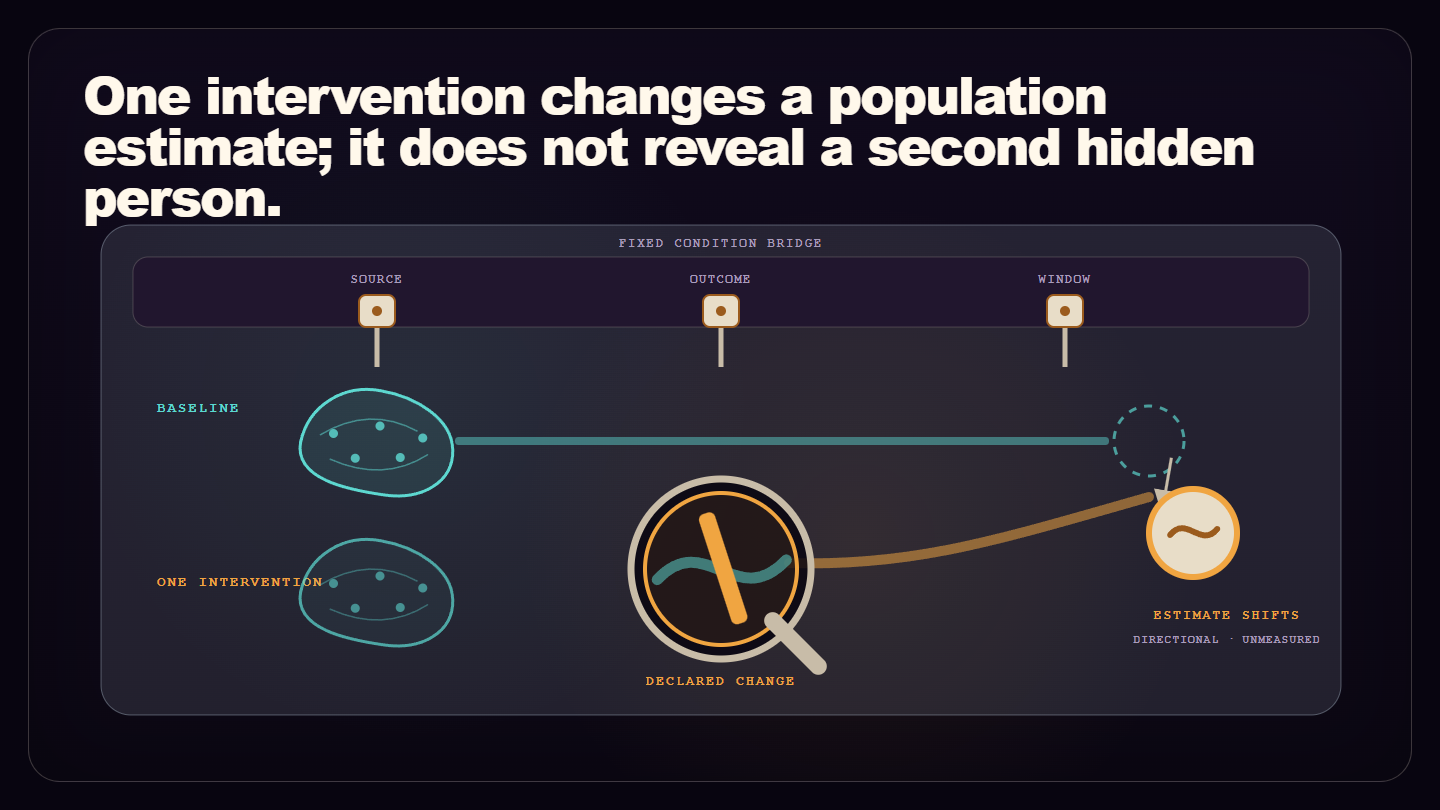
The contract names the baseline population, the intervention, the fields held constant, the fields allowed to vary, the outcome and observation window, the evidence class, and the rule that ends the test.
Simulation can then explore the decision before any capital is committed, and a controlled real experiment can follow. When the observed return disagrees with the simulation, the disagreement is valuable because it shows where the world model failed.
The comparison should resist decorative precision. A synthetic population assigning a precise percentage to Version B doesn't create a real-world forecast with that accuracy. The safe result may be directional: Version B depends less on technical vocabulary, creates less risk for low-authority buyers, or performs poorly when urgency is low.
The operator chooses how much real exposure that evidence earns.
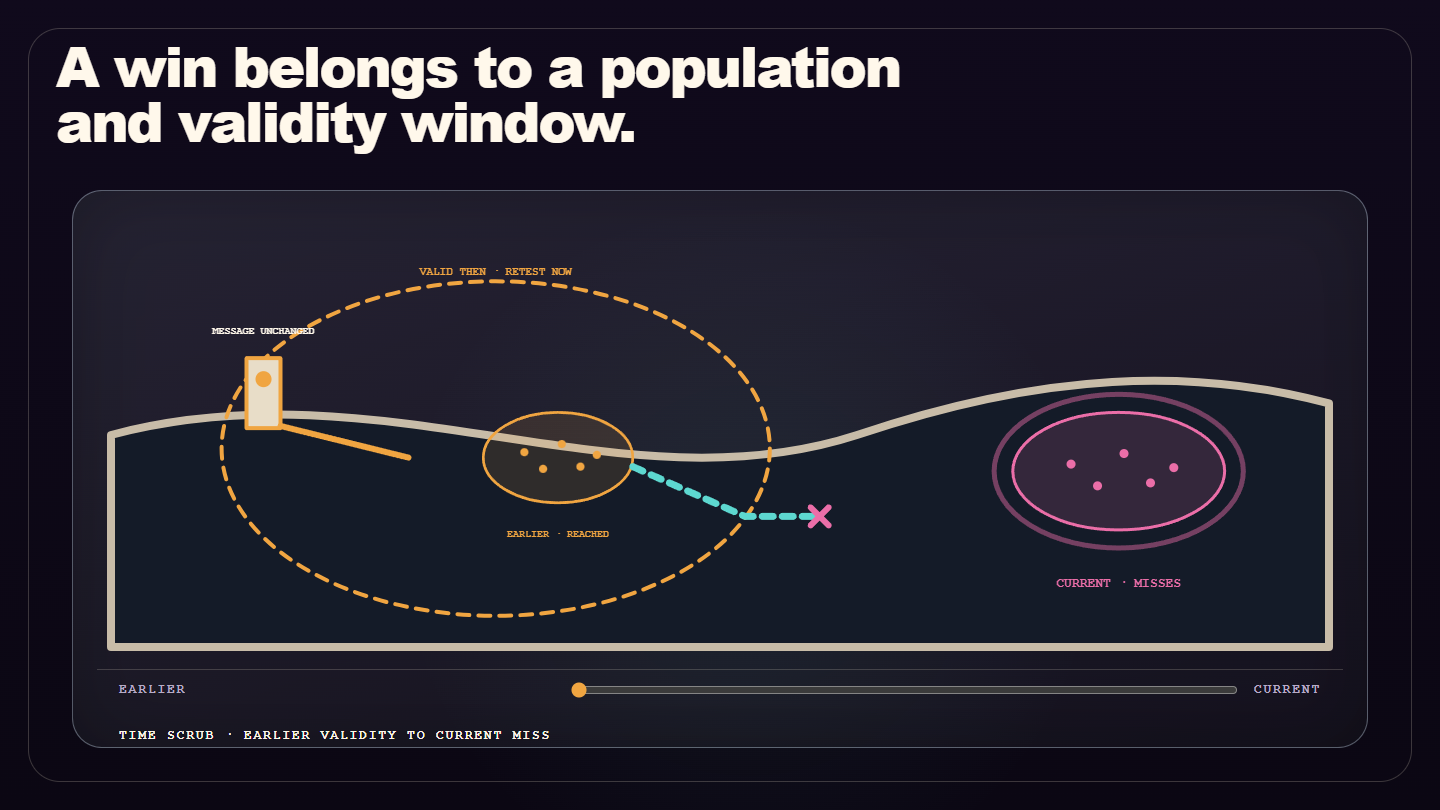
Population drift changes the meaning of a win
A winning message can become stale while its words remain unchanged.
The audience may move to another channel. A tool update may retire the pain the message names. A scandal may change the proof threshold. Competitors may copy the language until it sounds generic. The people arriving through a paid campaign may differ from the people arriving through referral. The model that explains last quarter's conversion may no longer describe this month's traffic.
Drift detection watches distributions, not only totals.
Did the share of high-urgency opportunities change? Did budget evidence shift? Did a vocabulary cluster appear? Did the time from first view to reply lengthen? Did one source produce more volume and less fit? Did objections move from price to trust?
The system should update a component when the evidence changes and preserve the old validity window. The map then shows that the earlier campaign worked for an earlier population under earlier conditions.
The practice room is deliberately small
Choose one live market question.
Build a source corpus recent enough for that question and define a small set of components. Keep observation, recollection, inference, and simulation separate. Construct a baseline population and one declared intervention, ask several bounded specialists to examine the same typed model, make their common ancestry visible, and let an independent evaluator challenge the result.
Then place a small real bet.
The return may be a click, reply, interview, objection, sale, cancellation, or silence. Record the event and the observation window, compare them with the model, update the components that failed, and keep the full run so the next test starts from accumulated evidence.
This practice turns population modeling into active sensing.
The city can stay incomplete as long as it has one street where a change produces a measurable return and a trustworthy record of what the system believed before it acted.
That return then has to travel through the engine that turns a model into work.
9. One source record connects research to action
Consider an illustrative Upwork post. The buyer wants help with a marketing system, but the post mixes symptoms, tools and outcomes. The operator must decide whether the work fits, what evidence supports an application and what package is worth preparing.
A person could open a chatbot, paste the post, ask for a proposal, and get fluent text back that may even sound competent. That path hides most of the work.
Does the job fit the operator's real experience? Which parts of the post reveal the buyer's deeper problem? Which past assets prove the right capability? Which current facts need research? Which claims can the operator make? What would a strong sample show? Who checks the result? Where does the decision live tomorrow?
Treat the following flow as an operating design, not a report of a completed run. One decision travels through the whole chain: capture the post, retrieve evidence, analyze fit, prepare a bounded package, review it, obtain human approval and record what the buyer does next. A missing link remains missing even when the surrounding tools work.
Capture the signal with its conditions
The job post enters the system as a source, not as a blob of prompt text. The original record preserves the possibility field before the team commits to an interpretation.
The record keeps the platform, URL, client, timestamp, budget, stated requirements, questions, attachments, and raw language. Extraction identifies entities, tools, industries, outcomes, and constraints. The original text stays available because extraction can miss or distort.
The system can now connect the opportunity to related objects. Past proposals, portfolio assets, client work, market research, voice samples, and current product knowledge become candidates for retrieval.
Nothing has been generated yet, and the first piece of value already exists: the opportunity is now inspectable.
Retrieval selects evidence for a particular decision
Keyword search may find every file containing “Shopify.” The operator needs a smaller and smarter view.
Which Shopify work involved revenue ownership? Which assets show catalog, retention, advertising, or analytics judgment? Which source reflects the operator's current voice? Which facts are recent enough for the market? Which client material is allowed to enter this opportunity's namespace?
The metagraph supports retrieval through relations and time. A project connects to its artifacts, decisions, outcomes, and people. A fact connects to its source and validity. A voice sample connects to a register and date.
Retrieval then produces a bounded context package, small enough for the next worker to use and rich enough to keep the mechanism intact.
I built a local retrieval system over my Markdown and PDF sources, exposed through an MCP and based on Archon with a changed chunking pipeline. That documented work supplies a narrower starting point than a claim that one system answers every question.
The RAG Knowledge Engine case describes document-type-specific processing and retrieval from a private corpus. The practical distinction is what a query must return: an exact passage, nearby material, a cross-document pattern or a change over time. Those are different retrieval jobs.
A similarity index ranks items under a representation and distance rule. It can retrieve useful passages. Answering a corpus-wide question may also require a broader index, aggregation, linked evidence or summaries whose inputs remain inspectable.
The stored distinctions decide which questions remain answerable. A timestamped record can support a time filter; a record without time can't recover a history the system never kept.
A passage search alone leaves several kinds of work unfinished:
- A recurring theme may need comparison across many passages rather than one nearest chunk.
- A change between periods needs dates, comparable samples and preserved earlier states.
- A coverage gap needs a declared topic set or question set; no result alone proves the corpus never discusses something.
One design adds summaries above related groups of chunks, then summaries of those summaries. Retrieval can inspect an exact passage and the wider region it belongs to. The summaries still need links to their inputs, dates and visible uncertainty. A hierarchy can improve the available view while also spreading an extraction error into several later answers.
A rotating graph or animated control panel doesn't demonstrate that retrieval works. Ask a load-bearing question, inspect the returned evidence and compare that answer with the source. The display earns its place when it helps that inspection.
The different shapes of data explain why a richer representation can answer questions a simpler one left open. Choose that extra structure because a recurring question needs it, not because a deeper-looking diagram promises intelligence.
Buyer analysis precedes the choice of output
The engine decomposes the buyer's post.
One layer names the stated request, and another identifies the business problem beneath it. A third maps the future state the buyer wants to observe, and a fourth names the constraints and the evidence required to cross the gap.
The research starts with a diagnosis: separate the problem from the operator's favorite solution, describe the future through visible artifacts and events, and design the transformation between them.
The analysis may conclude that a proposal is warranted, or it may reject the opportunity, because a strong engine improves selection as well as production.
Rejecting an unsuitable opportunity preserves production capacity for a better fit. Every weak application consumes time that could deepen a better one. The system should explain the reason: poor fit, weak budget, unclear authority, impossible promise, missing proof, expired post, or a market where the operator lacks current context.
A bounded brief assigns work and authority
In this design, SuperHarness routes bounded work to specialist agents. The Agent Systems entry explains why role, authority, tools and a stop event have to travel with the work.
A harness gives an agent a role, tools, permissions, context, a quality bar, a stop condition, and an evidence contract. That structure keeps one generic model from improvising every part of the company from the same chat window.
The source design names an execution runtime. Its role profiles separate research, software engineering, creative production and evaluation. A profile needs a bounded job and suitable tools; a role name alone doesn't establish that a run met its contract.
The worker needs to know how its assigned action serves the intended outcome and which observable event ends the job. The receiving worker needs the connection between the intended outcome and the event that ends its work, so it can act without inventing the missing business context.
A research job should know which sources own which claims, which queries must run in sequence, which assertion to re-execute, and where to save the result. A visual job should know the adjacent prose, the idea the reader needs to grasp, the visual class, the reduced-motion behavior, the delivered size, and the acceptance proof. An evaluator should know the kill criteria and the correction loop.
The execution system makes those contracts repeatable.
One source can support several purpose-built outputs
The engine now turns analysis into a product.
For an Upwork opportunity, the product may include a cover letter, work sample, video scaffold, research note, and follow-up plan. For a Field Note, the product includes a thesis, long-form article, citations, motion program, still images, interactions, accessibility, and rendered proof.
Compilation is a useful word because one source can produce several surfaces.
A transcript can become a world model. The world model can support an article, proposal, infographic, sales conversation, onboarding flow, or agent skill. Each output selects a register, audience, format, and level of detail. The underlying evidence and provenance stay shared.
Call it the one-source-many-surfaces rule. Refining the shared source or component improves every consumer, and creating a second disconnected copy creates drift. The Content Compiler follows that path from a shared source model to several purpose-shaped artifacts.
The engine should compile from canonical data and components wherever possible. A Field Note's index card and detail page should share one entry. Every media slot showing the same concept should use the same registry and source. Every agent profile should inherit one creative standard rather than keeping a private rewrite.
Independent review tests the candidate against its contract
Generation creates a candidate, and evaluation decides whether that candidate deserves the next state.
The evaluator checks claim fidelity, voice, value density, accessibility, visual comprehension, delivered-size readability, motion behavior, interaction value, source support, and the exact acceptance contract for the product.
The evaluator also re-executes one load-bearing claim or boundary. Re-execution catches a dangerous failure: a report can cite many sources while its central conclusion rests on one false sentence.
When the evaluator finds a defect, the finding returns to the producer with a correction order. The old verdict stays visible while the producer corrects the artifact and records the change, and then the evaluator checks again. Evals and Observability develops the distinction between generating a plausible candidate and earning the state change that accepts it.
The closed loop matters more than a numerical score, because it teaches the system which defects recur and which gates catch them.
A receipt keeps the result and reopen path inspectable
A finished artifact leaves a durable trail.
The receipt names the source inputs, profile, model, tools, working directory, branch, session, proof, result, produced files, and residual risk. Git records source changes. The task ledger records purpose, state, decisions, evidence, and handoff. Graphiti preserves reusable learning with temporal validity. The artifact itself contains provenance and correction notes where readers need them.
The reopen path answers a simple question: can another operator return tomorrow and see what happened without relying on the original chat?
Source code alone can't answer that, and neither can a screenshot or a task marked complete. The next operator needs the current state, supporting evidence, decisions, recorded failures and next action.
SuperHarness and AgentOS are different layers
SuperHarness holds execution and coordination contracts: the profile, bounded job, authority, receipt, evidence, and durable return. AgentOS gives a person a usable surface over those contracts.
The human standard is higher than the existence of source objects or healthy endpoints. A usable AgentOS surface must let a person inspect the profile, understand what will run, launch a bounded job, watch real state, inspect native evidence, approve or reject, and reopen the same work later. Empty routes, attractive dashboards, and backend endpoints don't complete that journey. State Machine Everything explains why an approval or reopen action matters only when it changes durable state.
The mechanism described here is the operating design, and capability still to come is labeled as still to come. A product counts as ready only when the complete human journey works.
Labeling states that carefully is part of hyperrelevance. The map should distinguish the source state, the intended state, and the human-verified state instead of blending them into one optimistic sentence.
One signal should keep its lineage across every surface
Follow one sentence from capture to publication.
An operator says something during a call. The transcript preserves the words, speaker, time, and recording source. An extraction activity identifies an entity, a claim, and a possible relation. A temporal graph stores that relation with its source and validity. A voice analysis records rhythm and vocabulary without replacing the transcript. A retrieval step selects the sentence for a specific question. A specialist uses it inside an article. A visual turns the adjacent idea into a scene. A reviewer changes the scene after finding that its first version looked good and explained the wrong thing.
The published paragraph and the final scene end up far from the original recording, and their lineage should stay close to it.
W3C PROV offers a useful public vocabulary: entities are things, activities transform things, and agents are responsible for activities. Derivation, generation, attribution, revision, and collection relations describe how one artifact became another.
Those relations record the route without certifying the destination.
A source can be wrong. An extraction can miss context. A faithful transformation can preserve a false premise, and a reviewer can approve a beautiful error. Provenance makes those failures inspectable, but it can't make them impossible.
One-source-many-surfaces is therefore a discipline of controlled derivation. A verified transcript can support a voice fingerprint, a Field Note, a short video, a case study, and a sales asset. Each surface adapts the source for its job and keeps a route back through the activities that changed it.
That route protects the golden goose too. A public surface can show the mechanism, the evidence class, and a bounded receipt without exposing private customer records, profile instructions, scoring weights, extraction recipes, or the complete graph. A reader can understand why the system works while the implementation advantage remains inside the engine.
10. The human stays in the loop by holding authority
“Human in the loop” can mean almost anything.
Sometimes a person clicks Approve after the system has already committed the action. Sometimes the person edits text but can't change the workflow that created the defect. Sometimes the interface shows a summary while hiding the source, policy, model, and evidence. The person is present and powerless.
Real authority has observable actions.
The operator can inspect what will run, change consequential inputs, approve, reject, correct, stop, reopen, and change the policy that shaped later runs. The system records who made the decision and which evidence was available.
A handoff needs more than a transcript
Imagine an air-traffic controller ending a shift.
The next controller needs current positions, destinations, weather, clearances, conflicts, decisions, and expected events. A recording of the previous controller's conversations may contain all of that somewhere, but it's still a terrible thing to operate from.
Agent work needs the same compression.
The next operator should see the purpose, current state, evidence, decision, blockers, and next action. The transcript stays available for forensic detail, and the operating state shouldn't depend on rereading it.
That's why the system uses several authorities instead of one giant memory.
Git answers, “What changed in the machine, and which history contains it?”
The task ledger answers, “Why are we doing this, what state is it in, which decisions were made, and who owns the next action?”
Graphiti answers, “Which reusable learning should later agents retrieve, and when was it valid?”
Native receipts answer, “What actually ran, with which profile, tools, context, and result?”
No one store should pretend to own all four questions.
Approval should change the state
An approval control is real when it gates a consequential transition. State Machine Everything develops the same rule as an operating system: the actor, object, allowed transition, and resulting state all remain visible.
Before approval, the action hasn't happened. After rejection, the system records the reason and doesn't quietly retry. After correction, the next candidate reflects the change. On reopen, the operator can see the decision and its effect.
The same applies to policy.
If every proposal overstates certainty in the same way, editing each proposal is expensive theater. The operator needs a way to change the instruction, rubric, source rule, or workflow that generates that class of defect, so one correction improves later work wherever the shared mechanism applies. That's how human judgment compounds.
A plain-language summary should preserve deeper inspection
The operator shouldn't have to read every token, tool call, and database row for every job, because that would make automation slower than doing the work by hand.
The interface should lead with ordinary meaning:
- what the system understood,
- what it plans to do,
- which evidence supports the plan,
- which uncertainty remains,
- what decision the person owns,
- what will happen after the decision.
Exact paths, identifiers, commands, prompts, and raw receipts remain available below that layer. The person can move down when risk or confusion requires it.
That's progressive disclosure applied to authority: simplicity at the top should make deeper inspection easier, not remove it.
Reopening is part of completion
Work is incomplete when it can be understood only inside the session that created it.
A browser journey should survive refresh. A task should survive a new manager. A receipt should point back to the native run. An artifact should identify its sources and correction history. A decision should remain visible after the interface closes.
Reopening protects the operator from losing context, and it protects the system from false completion. A demo that works once under the builder's hands may collapse when another person tries to resume it.
Authority and evidence let the engine allocate its scarcest resource with more care, and that resource is attention.
11. Resources constrain what the operation can deliver
Look at the top edge of a real-time strategy game.
Two or three numbers change while the player works: income flows in, construction spends it, and storage fills and drains. One resource can overflow while another hits zero. The army on the map may look like the game, but the resource bar quietly decides which actions are possible.
A digital profit factory needs a resource bar too.
Capital pays for access, labor, software, inventory, time, and risk. Attention supplies qualified human moments in which a message can be noticed, understood, remembered, and acted upon. Build power turns both resources into deployed work: research, creative, campaigns, conversations, delivery, measurement, and correction.
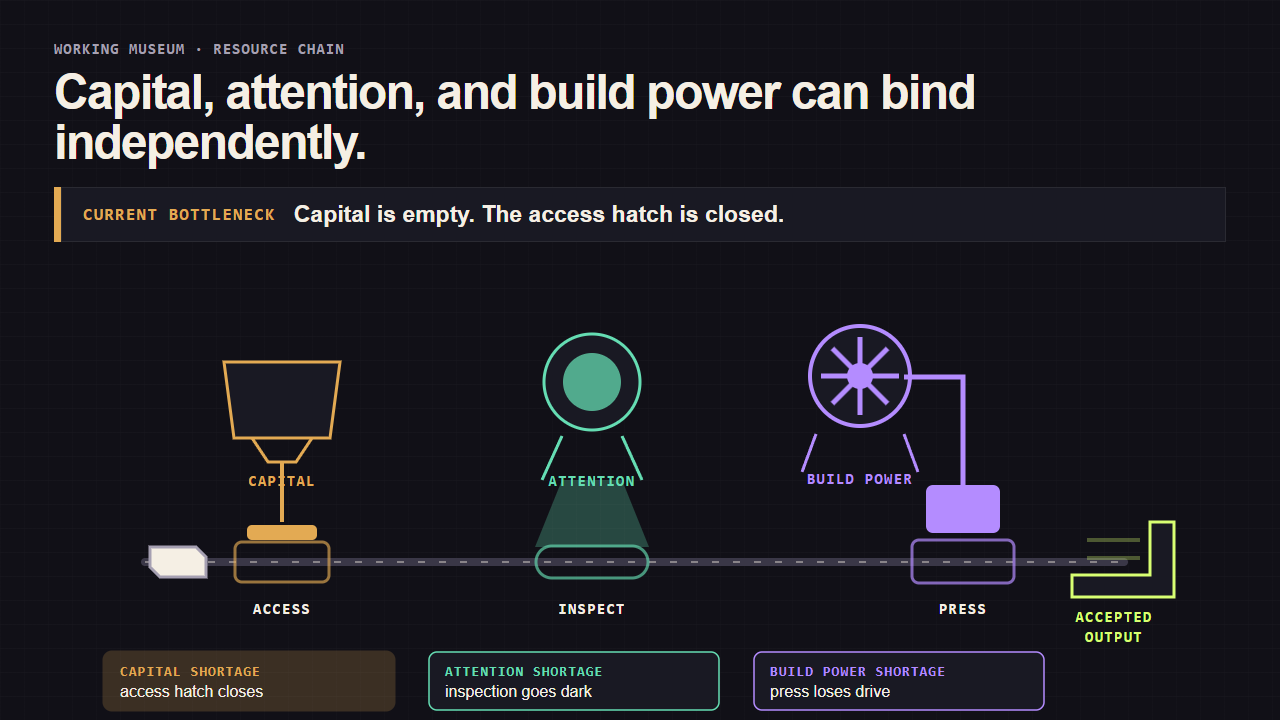
The third resource is easy to miss. A business can have money and audience demand while lacking the capacity to ship useful work. Another can have a talented team and no reliable attention source. Another can have attention and production capacity while cash timing forces every system into survival mode.
The binding constraint moves around, so the operating system needs to show which one binds now. The Standard Model of Effective Media provides the public depth for separating attention inventory, movement, and value.
Rates reveal the deficit a stored total can hide
Beyond All Reason describes an economy built from metal, energy, and build power. These resources have different roles, and too little of one can slow production. Its official economy guide teaches the player to watch income and use together rather than admiring the stored total.
That rate-based view transfers well.
A business doesn't own “traffic.” People arrive through channels at a rate, and the rate changes by hour, season, platform, offer, reputation, and competition. Capital arrives and leaves through invoices, payroll, advertising, subscriptions, taxes, and reinvestment. Production capacity changes as people, agents, approvals, and dependencies become available.
Storage helps with shocks. Cash reserves cover a delayed invoice, a content library feeds a quiet week, a waiting list preserves demand, and templates cut setup time. None of them fixes a structural mismatch in rates.
If work enters faster than the system can evaluate and produce it, the backlog grows. If production spends cash faster than outcomes replenish it, reserves shrink. If advertising rents attention faster than the offer can absorb qualified leads, acquisition becomes waste. If a team produces assets faster than distribution can place them, inventory decays unseen.
The useful question is, “What is our current inflow, outflow, stored buffer, and conversion capacity for each resource?”
Human attention stays scarce
The internet holds an enormous amount of media inventory, and a person's next useful moment is still scarce.
A platform can generate billions of impressions while one buyer has only a small number of moments in which your problem is relevant, your message appears, and enough attention remains to understand it. Frequency can increase exposure while reducing tolerance. A channel can scale impressions while degrading the share of qualified people. A broad audience can be abundant and economically useless.
Attention also decays.
A job post is fresh when the buyer is actively forming a shortlist. A reply has high value when a conversation is moving. A recorded proposal view can change the follow-up policy. A trend offers cultural attention before every competitor copies it. A support issue becomes expensive when silence changes trust.
The system should track qualified attention as perishable inventory, not as an infinite river.
Existing intent concentrates in particular channels
Metal in Beyond All Reason comes largely from particular places on the map, and controlling those places matters. The marketing equivalent is a location where relevant intent already concentrates.
A high-intent search query can be a deposit. A trusted referral relationship can be a deposit. A job feed filtered to a narrow capability can be a deposit. A customer segment facing a new regulation can be a temporary deposit. An email list with earned trust can be a deposit.
An extractor is the mechanism that repeatedly harvests that intent.
A ranking article can extract search demand. A referral loop can extract trust. A strong Upwork profile and proposal system can extract opportunity flow. A useful public Field Note can extract recognition from people who already need the thinking it demonstrates.
Every extractor has upkeep.
Search content requires current facts and working pages. Referrals require delivery and relationships. A job-market filter requires fresh ingestion and calibration, and an email list requires permission, relevance, and restraint. “Organic” means the channel doesn't charge for each click, not that the channel is free.
Neglected extractors go dark before their owners notice. Rankings decay, trust weakens, sources change, and the stored playbook keeps reporting an earlier world.
Paid media rents distribution
Paid advertising rents access to moments a platform can place, but it doesn't create human attention from nothing.
Capital buys a chance to enter the competition for attention. Creative earns or loses the moment. Targeting changes which people encounter the bid. The offer and experience determine whether that moment becomes a useful next event.
It's tempting to map the game's energy onto advertising, and the mapping is false. A paid campaign consumes capital and production capacity to acquire distribution. It may capture high-intent demand or introduce a new problem, and its efficiency depends on audience, auction, message, landing experience, measurement, and time.
Owned and earned channels have different cost shapes. They often require larger setup work and smaller marginal spend. Paid channels can produce faster learning and controllable volume while exposing the operation to auction costs and platform rules.
A mature factory uses both deliberately.
Marginal return can fall while total return grows
Scaling a successful channel rarely produces a straight line.
The first budget reaches the strongest audience pockets. More budget expands frequency, bids into weaker inventory, enters adjacent groups, and strains creative freshness. Results can continue improving while each additional dollar creates less incremental value.
Measure the real curve.
For each spend band, observe incremental reach, qualified attention, conversion, margin, service load, and downstream value. Separate average return from marginal return. A channel can look profitable overall while the newest spending block destroys value.
The answer may be more spend, or it may be new creative, a new segment, a better offer, stronger proof, or a new deposit. The resource bar should reveal the constraint instead of treating budget as the only lever.
A shared resource deficit can slow several functions
A strategy-game economy that spends faster than it earns can slow production across the whole base. Beyond All Reason players recognize the stall because many build queues weaken together.
A business nanostalls when a shared resource deficit slows every function.
Cash timing can delay contractors, media, software, and experiments. Approval debt can pause writing, design, campaigns, and reporting. Missing data can force every agent to reconstruct context. A founder's attention can become the hidden power grid, leaving dozens of workflows waiting for one person to review routine choices.
The failure is frightening because nothing has to stop completely. Everything takes longer: response quality drops, reports arrive late, follow-ups slip, and creative gets reused past its useful life. The organization experiences many local problems and misses the shared deficit.
A resource view links the symptoms.
If the common shortage is capital, cut or sequence spending and restore cash inflow. If it is attention, strengthen distribution or find a richer deposit. If it is build power, reduce work in progress, improve the production path, add capacity, or automate a proven step. If it is authority, move defined decisions away from the founder while preserving escalation.
The fix follows the binding constraint.
Production capacity counts only when work reaches acceptance
Build power controls production throughput in Beyond All Reason. More income can't become more units when the construction system can't spend it.
The marketing equivalent includes research capacity, writing, design, media generation, engineering, evaluation, approvals, deployment, and client communication.
An agent harness can raise build power by routing narrow work to several specialists, running research while implementation proceeds, preserving context, and performing routine checks. It can also create queue theater, where dozens of agents produce documents no operator can inspect, integrate, or deploy.
Useful build power ends in an accepted unit.
A proposal submitted with correct evidence is a unit. A campaign launched with measurement is a unit. A client report that changes a decision is a unit. A reusable component registered on the real site is a unit. A research memo waiting in a forgotten directory is stored work, not fielded capacity.
Throughput has to include evaluation and acceptance, or the factory ends up counting parts instead of finished units.
Failed work can contain reusable evidence and parts
Builders in Beyond All Reason can reclaim resources from wrecks and parts of the environment. The official reclaim guide makes the mechanic explicit.
Digital operations leave wreckage everywhere.
A failed campaign contains audience data, comments, losing messages, production assets, and timing evidence. A proposal that received no reply contains a target, loadout, claims, and response window. A dead product contains user language, support questions, technical components, and a record of false assumptions. A long meeting contains decisions, explanations, objections, and vocabulary beyond the summary.
Reclaim is a deliberate activity.
The system inspects the wreck, identifies reusable entities, separates evidence from interpretation, preserves lineage, and assigns each recovered part a current status. An old case study may retain its mechanism and lose its market numbers. A failed headline may reveal negative space. A rejected proposal may become a low-fit training specimen. A motion graphic may serve another explanation after its labels and evidence change.
Reclaiming differs from copying, because copying carries hidden state. Reclaim extracts named value with provenance and a fresh validity decision.
Later machinery needs a working earlier loop
Strategy games lock advanced machinery behind an earlier economy. The exact costs and multipliers belong to each game's balance rules, and the structural idea transfers: a later system needs foundations that an early system doesn't have yet.
A solo operator can begin with manual capture, a clear rubric, a few proposal assets, and disciplined outcome logging, and that's a valid first tier. Building a multi-agent production fleet before the opportunity model and review loop work creates idle machinery.
The next tier may add typed ingestion, reusable asset pipelines, lineage, evaluation, and a client event stream. A later tier may add population simulation, adaptive policies, multi-tenant operations, and supervised autonomy.
Each tier should open only after an observable constraint appears and the earlier loop produces reliable evidence.
Maturity is a change in which machinery the operation can use safely, not a badge on the roadmap.
Six layers organize the profit factory
The long list of modern marketing work becomes easier to reason about when sorted into six layers.
The resource layer holds attention, capital, time, data rights, and production capacity, and analytics, attribution, and observability show how those resources move and how uncertain the picture is.
The extraction layer covers search, referral, community, job feeds, partnerships, retention, and other channels where demand or trust already concentrates.
The generation layer covers paid distribution and the other mechanisms that spend resources to create new exposure, learning, or demand.
The production layer is the research, copywriting, design, media, engineering, asset rotation, and testing that turn resources into deployable artifacts.
The command and control layer holds the CRM, workflows, routing, permissions, automation, state, and operator surfaces that coordinate the fielded system.
The doctrine layer holds the documentation, training, knowledge, evaluation standards, and decision policies that let people and agents act consistently under pressure.
The layers depend on one another. Strong doctrine with no production stays a manual, and production without command creates chaos. Extraction without upkeep decays, generation without attribution hides waste, and resources without build power sit unused.
The map should let an operator move between layers while preserving one event chain.
Repeated testing and correction can outlast an individual model
A quantitative firm doesn't compound because one clever model lives forever.
The advantage comes from an apparatus that finds data, develops models, tests them, sizes risk, executes, monitors drift, records outcomes, and retires failed ideas. Models are inventory inside a production and governance system.
Hyperrelevance works the same way.
One audience insight can help, and the compounding advantage comes from the apparatus that keeps the insight current, turns it into several artifacts, measures returns, detects drift, and preserves corrections. In the same way, one powerful agent can draft, and the edge comes from the harness, typed model, evidence path, evaluation, operator authority, and memory that make many runs improve one another.
AndyDataGuy gives the model a bounded public test.
The public site can prove one base economy: authenticated thinking becomes useful Field Notes, the notes attract qualified attention, conversations create returns, client work produces evidence, and the evidence deepens later thinking. The site is a public instrument connected to the engine, not a separate thing.
Build that extractor before pretending to operate thousands of agencies.
A review cadence exposes resource changes
The exact cadence belongs in the operator's settings, and the activities stay the same.
Review resource flow often enough to see a stall before the whole system slows. Inspect extractors for upkeep and drift, and compare marginal return as a channel scales. Run reclaim across dead campaigns, unused research, and rejected opportunities. Check whether build power matches current inflow, and ask whether the next maturity tier solves an observed constraint or only looks impressive.
Before a large bet, run a skirmish.
Use the population model to rehearse the decision and check the evidence class. Then make one small real deployment, observe the return, keep the result, and increase exposure only when the feedback earns it.
This economy isn't a financial market. Attention isn't money, people aren't deposits, and content isn't a military unit. The game gives the operator a visible language for rates, constraints, salvage, and throughput, but the real measurements still have to come from the real operation.
12. Attention has inventory, flow, and waste
The resource view describes how much qualified attention, capital and production capacity can move through the operation. Measurement asks what each event means, what caused it and which value claim the evidence supports.
My garden-art case supplies a concrete limit. The campaigns attracted clicks, but the work never found a profitable, repeatable acquisition path. We tested different audiences, creative angles and account structures while watching the steps between an impression and a purchase. The site and testing budget constrained what we could learn. The result supported stopping the unsuccessful approach; it didn't isolate one universal cause of failure.
Picture a market square at noon. The square has room for a hundred stalls, but only twenty sit along the path most people walk. A baker can rent one of those twenty, place bread at eye level, and count everybody who passes. The count matters because it tells the baker how many chances the stall had to be noticed.
The count doesn't tell the baker who smelled the bread, stopped, asked a question, bought a loaf, came back tomorrow, or told a friend.
Marketing systems often compress that entire sequence into one word: attention. That shortcut makes dashboards tidy and decisions sloppy. An impression, a view, a visit, a conversion, and profitable demand are different events. Each event answers a different question. Hyperrelevance Cartography keeps them separate long enough to learn from them.
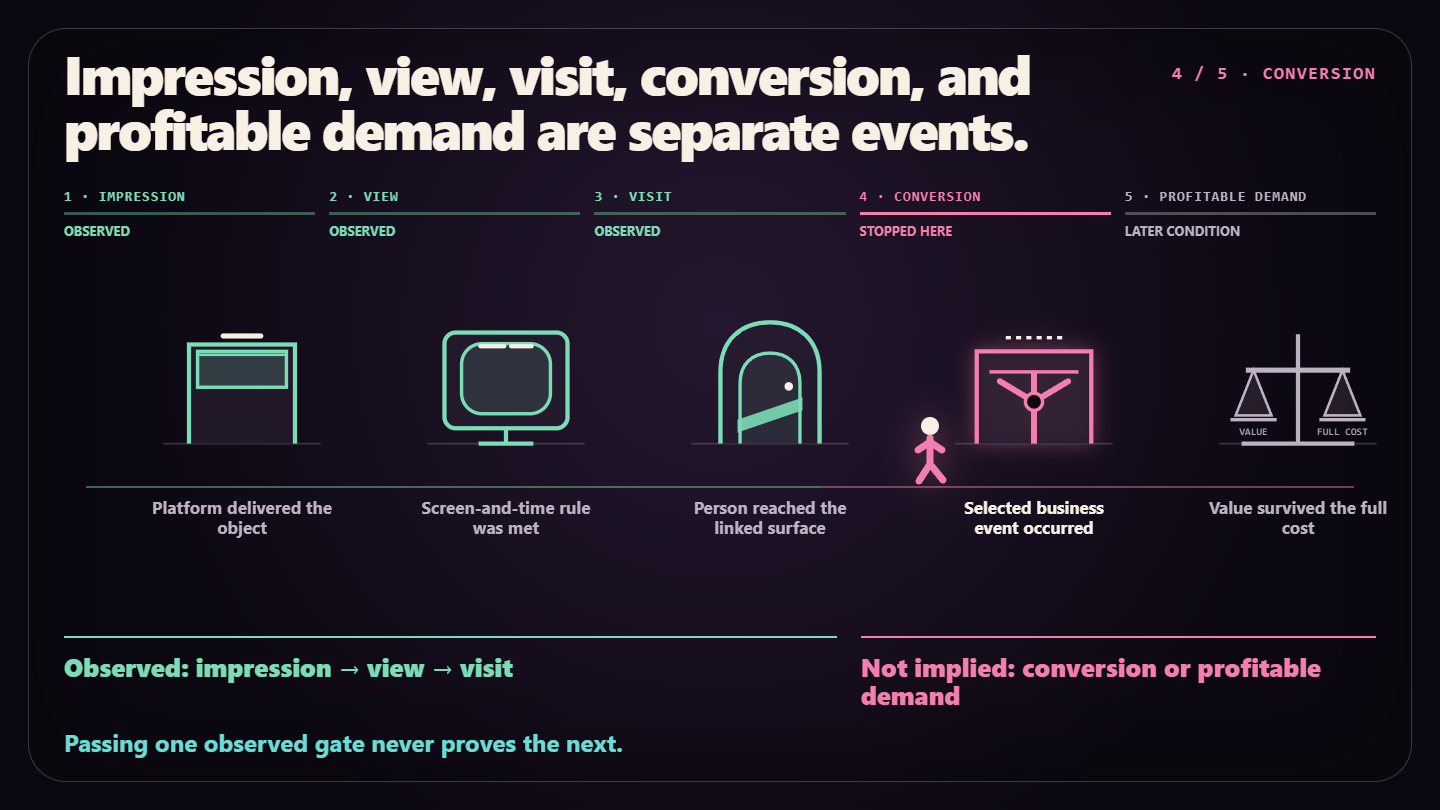
An impression is the widest observation. A platform began delivering or downloading an object according to that platform's rule. A viewability measure asks whether enough of the object occupied the screen for enough time to qualify under a stated standard. A click records an interaction. A session records an arrival on another surface. A conversion records an event selected in advance, such as a booked call, a completed purchase, or a submitted application.
Events closer to a business outcome answer different questions. A purchase is more direct evidence of buying than an impression, while a client outcome still needs its own record.
An impression can have direct commercial value under a cost-per-thousand-impressions contract. The advertiser pays for a measured unit of delivery and the publisher books revenue from the same unit, which makes the impression economically real before anybody proves that the campaign changed a buyer's behavior.
The causal question remains open. Did the impression produce the sale? Would the buyer have purchased anyway? Did a different channel do the persuasive work? Attribution systems connect events into a story. Controlled lift tests compare exposed and unexposed groups to estimate what the media caused. Unit economics decide whether the resulting activity created enough margin to justify the work.
The distinctions matter because every layer can look healthy while the layer below it rots.
A campaign can generate millions of cheap impressions in places where the right buyer never looks. A page can collect visits from people who leave before they understand the offer. A form can produce leads that no salesperson can close. A sales team can close accounts whose service cost destroys the margin. Each surface reports a success because each surface measures a local event.
The cartographer follows the whole route. Attribution goes deeper on preserving the event chain without granting one local metric ownership of the outcome.
A measured moment is still a scarce moment
Herbert Simon described the basic problem in 1971: abundant information consumes the attention of its recipients. Information has become easier to produce and distribute since then, and a person's day hasn't gained extra hours.
Scarcity makes attention a constrained input, and the measurement system sees only traces of it. A served ad may never enter view, and a viewable object may never enter memory. A click can be accidental. A long read can matter without producing an immediate conversion. An event record describes the instrument's observation. The person's experience can extend beyond what that instrument captures.
The engine therefore asks measurement questions beside allocation questions.
Which uncertainty is expensive enough to research? Which audience has a live problem? Which vocabulary signals that the problem is understood? Which format makes the proof easiest to inspect? Which channel can return a useful signal? Which response would change the next decision?
The answers shape the asset and the measurement plan. A field note built to demonstrate technical judgment shouldn't be graded like a discount ad. A joke built to spread inside a niche shouldn't be graded only by direct clicks. A proposal shouldn't be celebrated for being opened if the prospect didn't reply. Each object has a job, a market, and an observable event that shows whether it moved.
Flow is the chain between events
The market square becomes useful when the baker can trace movement. How many people passed? How many turned their heads? How many approached? Which question did they ask? What did buyers choose? What came back unsold? Which customers returned after tasting the first loaf?
Digital systems record pieces of that flow. The hard work is preserving definitions while joining the pieces.
Served impressions, downloaded impressions, measurable impressions, and viewable impressions are different populations. Clicks and sessions differ when pages fail to load, browsers block tracking, or people click twice. Platform conversions depend on an attribution window and a model. A booked call becomes revenue only after the call occurs, the buyer qualifies, the offer fits, and the account survives delivery.
Every join adds uncertainty, which is fine as long as the uncertainty stays visible.
The engine keeps the raw event, the platform definition, the timestamp, the source, and the confidence attached. It can then build a view for the decision at hand. A distribution operator may care about viewable reach and frequency. A salesperson may care about qualified conversations. A finance operator may care about contribution margin after delivery cost. The same underlying trail supports all three without pretending they are the same number.
The metagraph earns its keep here. The impression can stay one event while the creative, audience, channel, visit, conversion, account, and outcome become related objects instead of columns flattened into one report. Time and provenance stay attached, and later evidence can correct the interpretation without erasing the original observation.
One impression can hold three different kinds of value
An impression looks simple because it is often shown as one integer.
The integer can support several claims, and each claim needs its own name.
Commercial value describes what somebody will pay for the event under a contract or market rule. A publisher can bill for delivered or viewable impressions. A sponsor can buy access to a defined audience. The impression has commercial value before anybody clicks because a buyer agreed to purchase that exposure.
Causal value describes what the event changed. Did seeing the message increase recall, search, visits, purchase, trust, or another later behavior? Establishing that value requires an experiment, a credible comparison, or a model with visible assumptions. Billing records alone can't supply it.
Attention value describes the scarce human focus the event actually received. A served ad may never enter view. A viewable ad may pass through the screen without entering memory. A six-minute explanation may command deep attention from fifty qualified people and create more value than a million silent passes.
The three values can travel together, and they can also split.
A large campaign can have strong commercial value for the publisher, weak attention value for the audience, and uncertain causal value for the advertiser. A private technical memo can have no media billing value, high attention value among ten decision makers, and large causal value if it changes a procurement decision.
A cartographer keeps those claims apart by recording what was purchased, what was delivered, what was available to see, what people did next, and which evidence supports a causal connection.
That separation changes allocation.
A media team can compare the price of access to an audience. A creative team can compare whether different objects hold attention. A sales team can compare which interactions produce qualified movement. A finance team can compare value created with the full cost of production and delivery.
The same impression count can enter all four views, and its meaning changes with the question.
The same separation is why attention shouldn't be called a currency. A currency needs a unit stable enough to exchange and account for. Ten seconds from a bored commuter, ten seconds from a surgeon choosing equipment, and ten seconds from a child watching a joke share a duration. They don't share context, consequence, memory, or replacement cost.
Attention is closer to perishable capacity. It arrives inside a person, in a situation, with a current goal. A hyperrelevance engine creates value by matching that capacity with a useful object and a credible next step. It measures the return without pretending every second has one exchange rate.
Traffic, conversion, and revenue are connected events
Marketing reports often place four words in a funnel: impression, traffic, conversion, revenue.
The funnel suggests a clean descent. Real paths branch, stop, repeat, cross devices, and reappear weeks later.
A person can see a post, search the company name later, read an article, ask a colleague, join a call from a forwarded link, and purchase under a different email. Another person can click immediately, trigger a platform conversion event, and never become a customer. A third can read ten times, purchase once, and influence five colleagues.
A metagraph can preserve that mess without claiming to resolve every identity.
Events can link when evidence supports the link. Probable relations can remain probable. Unknown routes can stay unknown. Aggregates can describe population movement while individual records retain consent and access boundaries.
Linking events that way gives the operator a stronger question than “Which channel got credit?” The operator can ask which surfaces introduced language, which surfaces supplied proof, which interactions reduced risk, which events predicted qualified movement, and where the next step disappeared.
The answer can support a budget decision without inventing a perfect customer journey.
Waste teaches when the system records it
A monthly total can hide which miss should change the next test. Spend, production and an aggregate dashboard may all be recorded while the original prediction and the buyer response remain disconnected.
Cartography turns a miss into a map update.
A joke that earns views outside the target niche may reveal a distribution mismatch. A technical article that holds expert readers but loses beginners may reveal a vocabulary threshold. A proposal that gets opened and ignored may reveal an offer problem, a proof problem, or a timing problem. A strong click rate followed by weak sales may point toward message-to-offer mismatch rather than creative weakness.
The system records the candidate explanations and tests them against later evidence, instead of appointing the first plausible story as the truth.
That discipline changes the economics of failure. The asset can miss its immediate target and still improve the engine, provided the signal is clean enough to change a future choice. Repeated failure without a model update is pure waste. A documented miss that narrows uncertainty becomes research capital.
The market comparison starts to earn its place at this point. Markets exist because buyers and sellers arrive with different information, different timing, and different willingness to trade, and a good intermediary reduces some of that friction. A content engine faces a similar problem, and the similarities need sharp borders.
13. A content operator commits capacity before demand is certain
A farmer drives into town with twenty crates of tomatoes. A restaurant needs tomatoes on Thursday. Families want a few on Saturday. The farmer wants a buyer now because ripe produce carries inventory risk. The buyers want confidence that supply will exist when they need it.
An intermediary can stand between them, buying from the farmer, holding inventory, selling smaller quantities later, and accepting the risk that prices move or tomatoes spoil. The gap between the buying price and the selling price pays the intermediary for capital, service, and risk.
Financial market making formalizes that function. A market maker regularly stands ready to buy and sell for its own account, and in many venues it maintains two-sided trading interest under specific quoting rules. The firm commits capital, holds inventory, manages adverse selection, and accepts the chance that the market moves against its position. Algorithmic Trading Pipelines gives the nearest public implementation depth before any of that language gets transferred to attention.
That mechanism produces useful ideas for a content business, and terrible ones when the vocabulary gets copied without the mechanism.
Financial market-making rules don't transfer wholesale to content. Attention lacks the same units, transfer rules, inventory ownership and settlement systems. A content calendar, subscriber list or click count doesn't create a financial exchange.
The analogy earns its place through a smaller transfer.
A specialist content engine reads demand signals from a market and commits scarce research and production capacity. It creates an offer in a form the audience can inspect and distributes that offer where the response can be measured. It accepts the risk that the work lands badly, attracts the wrong audience, or reveals that the assumed demand was weak. Then it updates the map.
The shared mechanism is uncertainty reduction.
Buyer and specialist begin with different information
The bid and ask in a financial market expose a gap between buying and selling terms. A service market has a different gap.
The buyer knows the lived problem, internal constraints, budget pressure, and political risk. The specialist knows methods, patterns, tools, failure modes, and the cost of different paths. Each side begins with an incomplete model of the other.
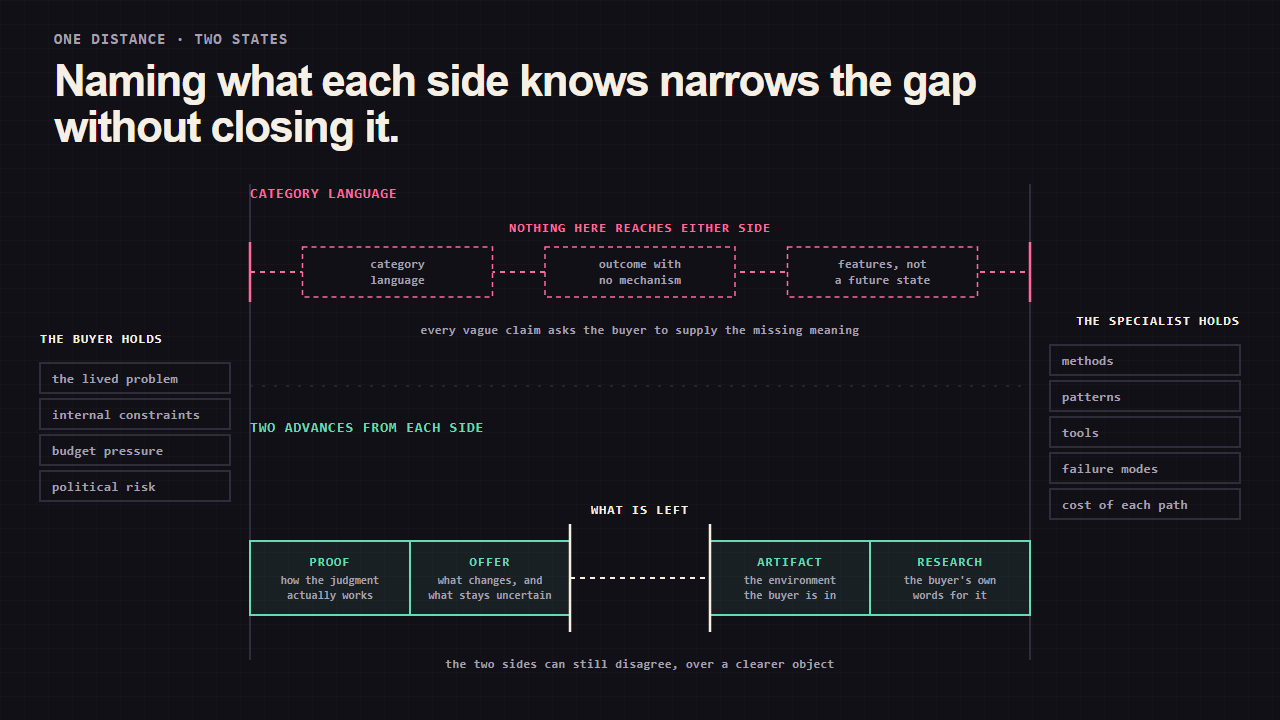
Generic marketing widens that gap. It uses category language where the buyer uses situation language. It promises outcomes without showing the mechanism. It describes features while the buyer worries about a future state. Every vague claim asks the buyer to supply missing meaning.
Hyperrelevant work narrows the gap by making the models legible.
The research names the buyer's actual vocabulary. The artifact shows an understanding of the current environment. The proof demonstrates how judgment works. The offer states what changes, what evidence will exist, what remains uncertain, and what the buyer must provide. The two sides may still disagree on price or fit, but they disagree over a clearer object.
That's the attention-side version of better price discovery. Nobody finds a universal price for attention; the system finds a more credible match between a live problem, a qualified audience, an artifact, and an offer.
Shared context can make a qualified next step possible
Liquidity in a financial market describes the ability to trade without excessive cost or price disruption. A small-business service market has a looser but useful parallel: capable buyers and capable providers often fail to meet at the right time with enough shared context to act.
The provider may be invisible outside a referral network. The buyer may post a vague request because the buyer can't name the technical solution. Platforms may flood the request with generic proposals, which raises the buyer's screening cost. Good providers then avoid the platform because the signal is noisy. The market thins from both sides.
Hyperrelevance Cartography improves the meeting surface. It identifies the language of the problem, the surrounding constraints, the evidence a serious buyer looks for, and the channels where that buyer already searches. It produces assets that let the buyer inspect judgment before scheduling a call.
A better meeting surface can increase qualified flow, but it can't guarantee demand. The system still faces timing, budget, trust, competition, and delivery capacity, and the analogy should make those constraints easier to see instead of hiding them under financial language.
Inventory risk becomes production risk
The financial market maker risks capital and inventory. The content operator risks research time, production capacity, reputation, and audience trust.
An overbuilt asset can arrive after the market moved. A rushed asset can make the operator look careless. A technically correct piece can fail because it uses vocabulary the audience doesn't share. A viral joke can attract people who will never buy. A high-volume campaign can exhaust a channel before the offer is ready.
The engine manages that risk through position sizing in the ordinary sense: match the production bet to the confidence and value of the opportunity.
A weak signal may deserve a short probe. A recurring pain with strong evidence may deserve a field note, interactive tool, or case study. A client-critical decision may deserve primary-source research, independent evaluation, and a reopenable evidence trail. The system spends depth where error costs more.
The map also has to stay private enough to compound. Customers hire the operator for researched outputs and better decisions. The engine keeps reusable workflows, public sources, evaluation methods, and permitted non-identifying learning, while customer data, confidential strategy, and tenant-specific memory stay inside their boundaries.
The agreement should distinguish the customer's deliverables and data rights from the operator's reusable machinery. Paid work can improve a general process only within the rights the parties actually granted. Removing a client name doesn't by itself authorize reuse of confidential material.
14. FreelanceBuddy gives the loop a bounded test case
A job feed makes the method testable one opportunity at a time.
An illustrative freelancer opens a feed of recent posts. Some requests are vague, some exceed the available budget, and others describe valuable problems outside the freelancer's current proof. Selection determines which ones receive production effort.
The ordinary workflow asks the freelancer to remember everything at once: fit, freshness, client history, past examples, offer, price, voice, questions, proof, follow-up, and the energy available today. The freelancer opens tabs, saves a few posts, drafts a few letters, and promises to return to the rest.
The FreelanceBuddy design gives those choices durable objects, events and evidence.
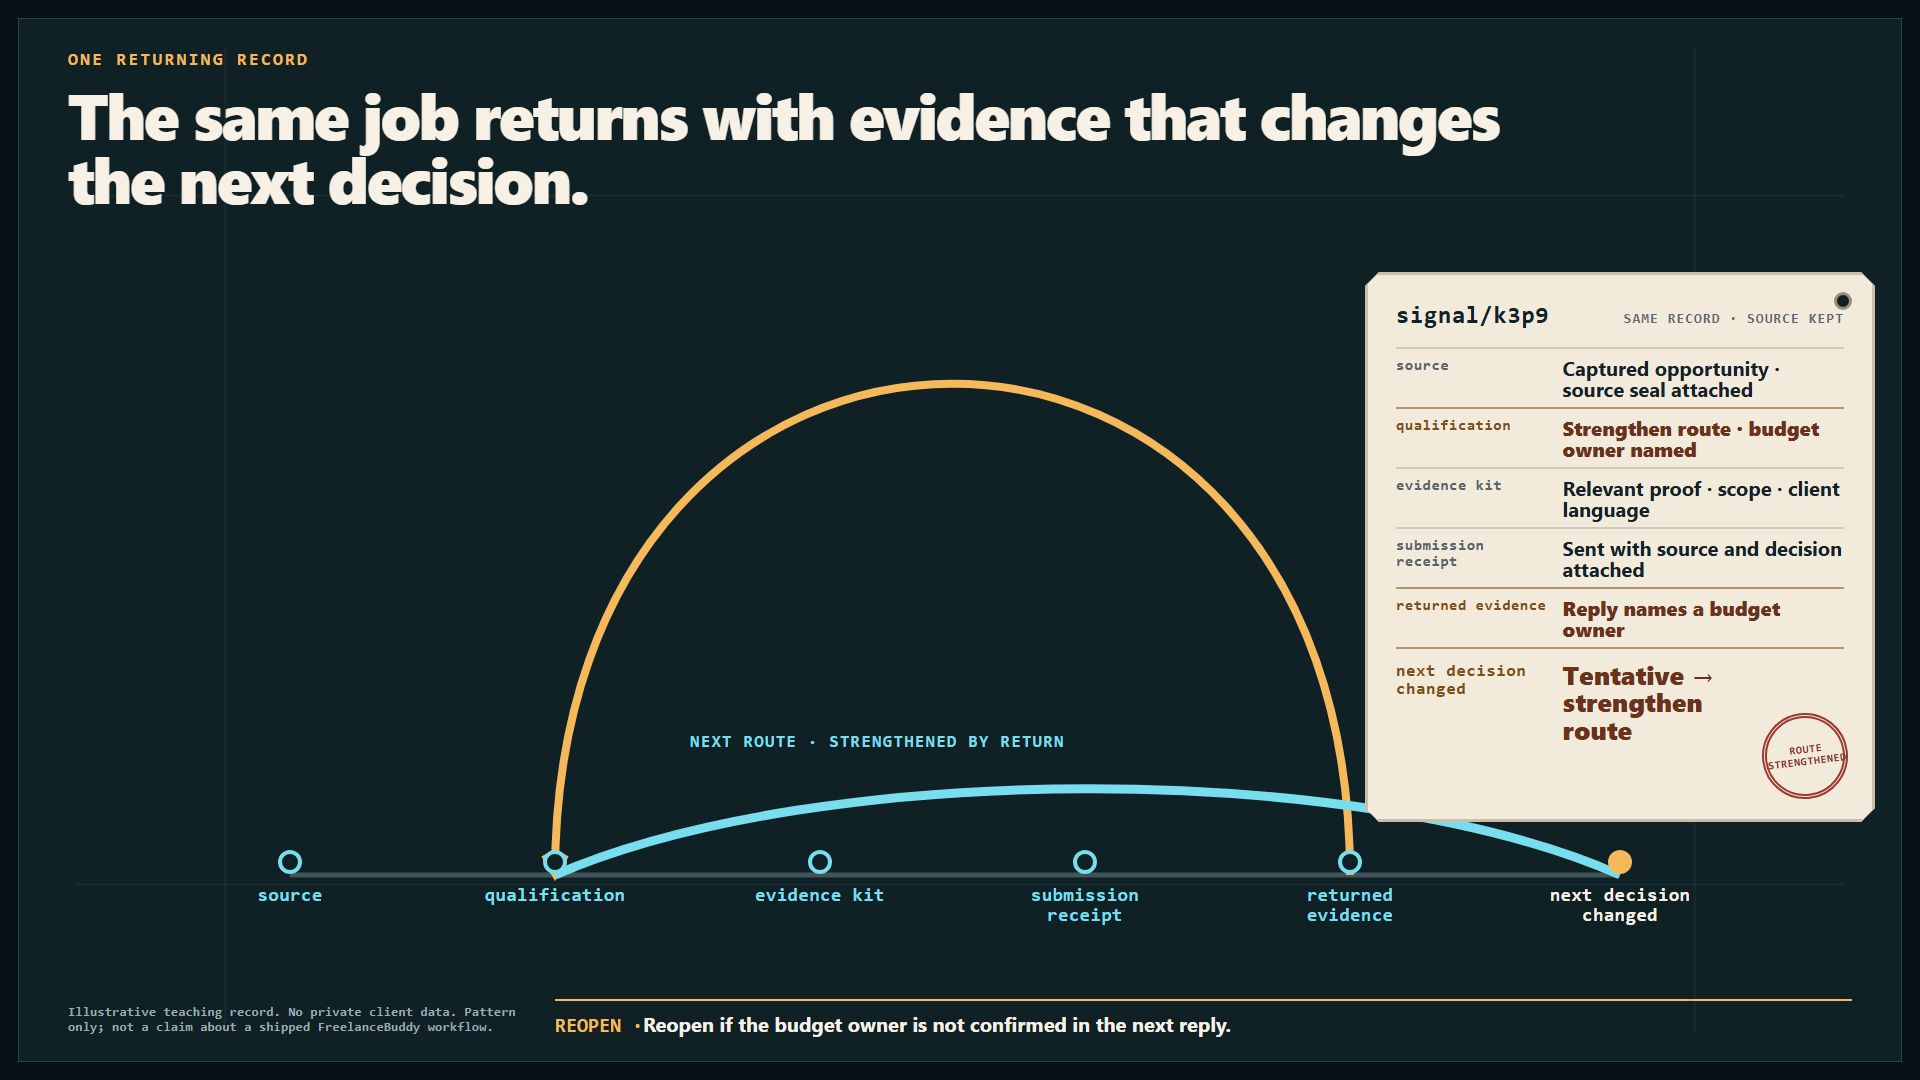
FreelanceBuddy is the bounded product case developed here. A job post enters, the operator classifies it and a proposal package leaves only after approval. Views, replies, interviews, offers, hires and closures are possible returns. Each can change selection, production, timing or the market model. The complete loop is the acceptance target, not a capability established by this walkthrough.
The design centers on structured opportunities, evidence, scores, stages, events, proposal work and assets. The immediate acceptance target is one operator journey from intake to reopening. Close-time modeling, automatic client reports, complete lineage learning, supervised autonomy and the company-wide Swarm Layer remain later obligations until a person can use and reopen them.
That boundary gives each later feature a concrete dependency: the earlier human loop has to work first.
One opportunity should keep its evidence through the whole loop
Take one recent post for a technical content system.
The possibility field starts wider than the job title. The post may be an immediate application, a negative specimen, an aspirational build target, a vocabulary source, or a signal about a changing market. The first question is concrete: should Andy spend proposal capacity on this opportunity before its useful window closes?
The instruments inspect the source and the buyer-side transformation. Freshness, budget evidence, hiring history, fit, proof, competition, authority, stated outcome, and unresolved questions stay separate. The system also asks what problem exists beneath the requested deliverable, what future the buyer wants to observe, and what change would bridge the two. The Product Growth Loop Audit is a public example of tracing a business problem through states and evidence instead of jumping from symptom to output.
The narrowing stage removes routes that can't survive reality. A stale post leaves the active queue. A claim with no proof leaves the proposal. A long strategic brief dies when the deadline and opportunity value can't pay for it. A visual stays only when it makes a difficult part of the buyer's problem easier to inspect. Several viable packages may remain.
The commitment is the package Andy approves and sends. The decision record keeps the other survivors, the score inputs, the selected loadout, the expected next event, and any buyer-stated timing. Submission changes the opportunity state and starts the stage clock. State Machine Everything provides the deeper model for that kind of durable transition.
The return is an event rather than a mood. Unseen, viewed, replied, interviewing, verbal yes, offer, hired, closed, withdrawn, and cold all carry different information. Silence stays ambiguous until a named window makes it actionable. A buyer's stated date overrides a generic clock because it is better evidence for this relationship.
The update changes the next action and the market model. A recorded view establishes a platform event, with the platform's definition and limits attached. A reply adds the buyer's language and timing. A loss can weaken the target, offer, proof, or asset choice, but the system records unknown when the event can't distinguish among them. Reopening is normal when a new event invalidates the earlier decision.
That loop is Hyperrelevance Cartography in a form that can run before any grander system exists: one source becomes one bounded decision, one committed act, one preserved return, and a better starting position for the next post.
Current, next, and later belong on the same map
A product view should distinguish available actions, implemented but unproven mechanisms and specified future behavior.
The proposed foundation turns job posts into structured opportunities and applications into deals. A corpus can grow independently of submitted proposals, with scores, stages, events and assets attached to each record. These are the records the joined operator journey must expose.
An operator could collect a bounded set of recent posts, separate candidates from research specimens, inspect their rankings and compare the selected distribution before spending on applications. A saved post would retain an address. A rejection would retain its research value. An application would stay linked to the assets and decisions that produced it.
The next usable slice is narrower than the full vision and more valuable than another broad dashboard. One opportunity needs to travel through the complete loop from intake to reopen. The operator should see the source, score, evidence, stage clock, strategy transcript, selected loadout, generated candidates, independent review, human decision, submission event, buyer return, and next action on one coherent surface. Workflow Design gives the broader pattern for keeping that chain inspectable.
Some pieces can exist separately in source or adjacent workflows while the joined human journey remains incomplete. An operator who has to reconstruct the score and output from terminal sessions hasn't received the promised loop.
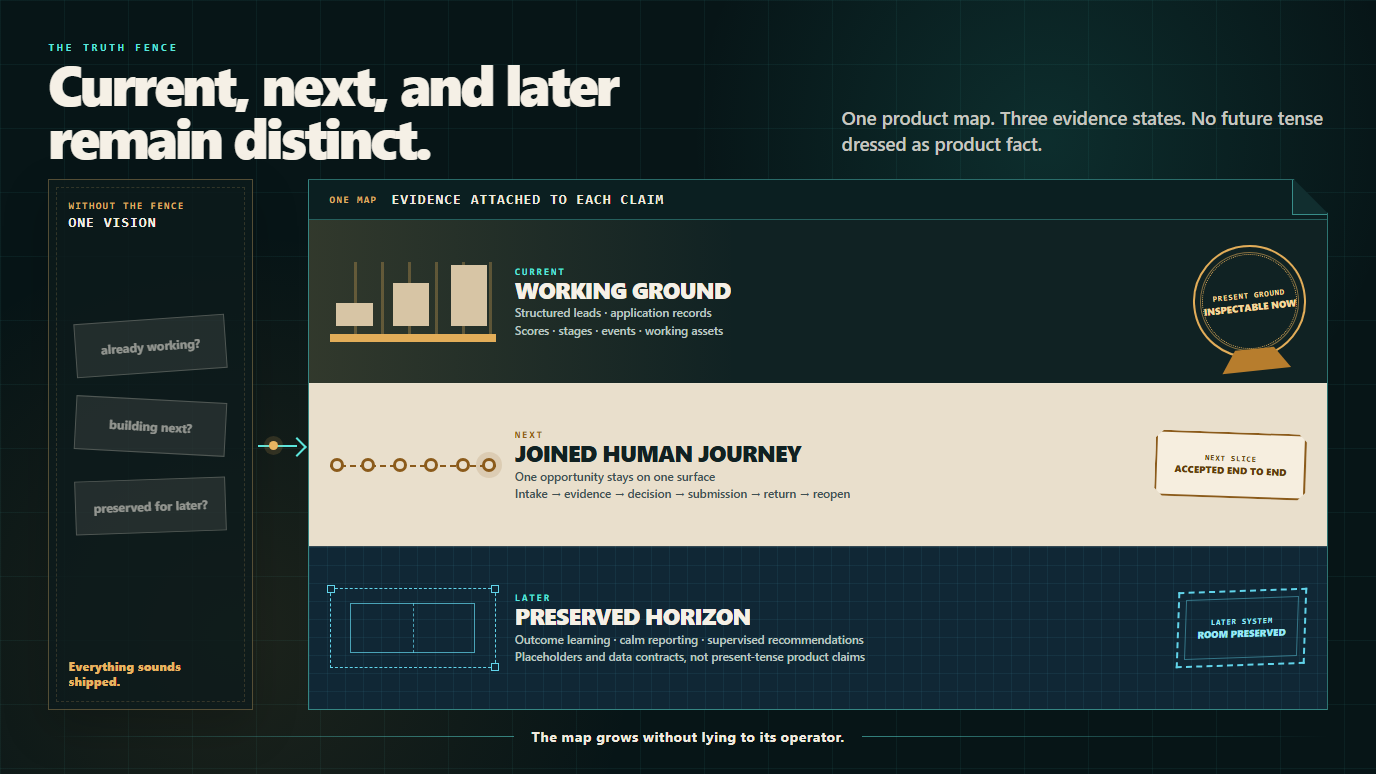
The later system is larger. It estimates close and loss distributions over time once enough real outcomes exist, and it learns which assets go with which outcomes without confusing correlation for cause. It compiles calm client reports from event streams, recommends policies after repeated supervised correction, supports service after a win, and eventually supplies proven components to the Swarm Layer.
Those later capabilities deserve visible placeholders and data contracts now, not present-tense product claims.
The interface can show the boundary directly. A working control appears as available. A source-backed mechanism without browser acceptance appears as implemented and unproven. A designed future appears as specified. A recommendation derived from partial evidence appears as inferred. The status label should sit beside the object or action, not in a distant roadmap.
The operator can then distinguish what's usable, what still needs acceptance and what has only been designed. The product can grow without presenting those states as one capability.
The job feed supports selection before production
An inbox invites reaction, and a landscape invites scouting.
The job feed contains separate encounters with different requirements, rewards, uncertainty, and timing. Elden Ring offers a useful picture because it gives the player a large authored world, many routes, character attributes, different weapons, sorcery, spirits, and choice about how to develop a build. The official early-game guide says plainly that players can build their character as they choose.
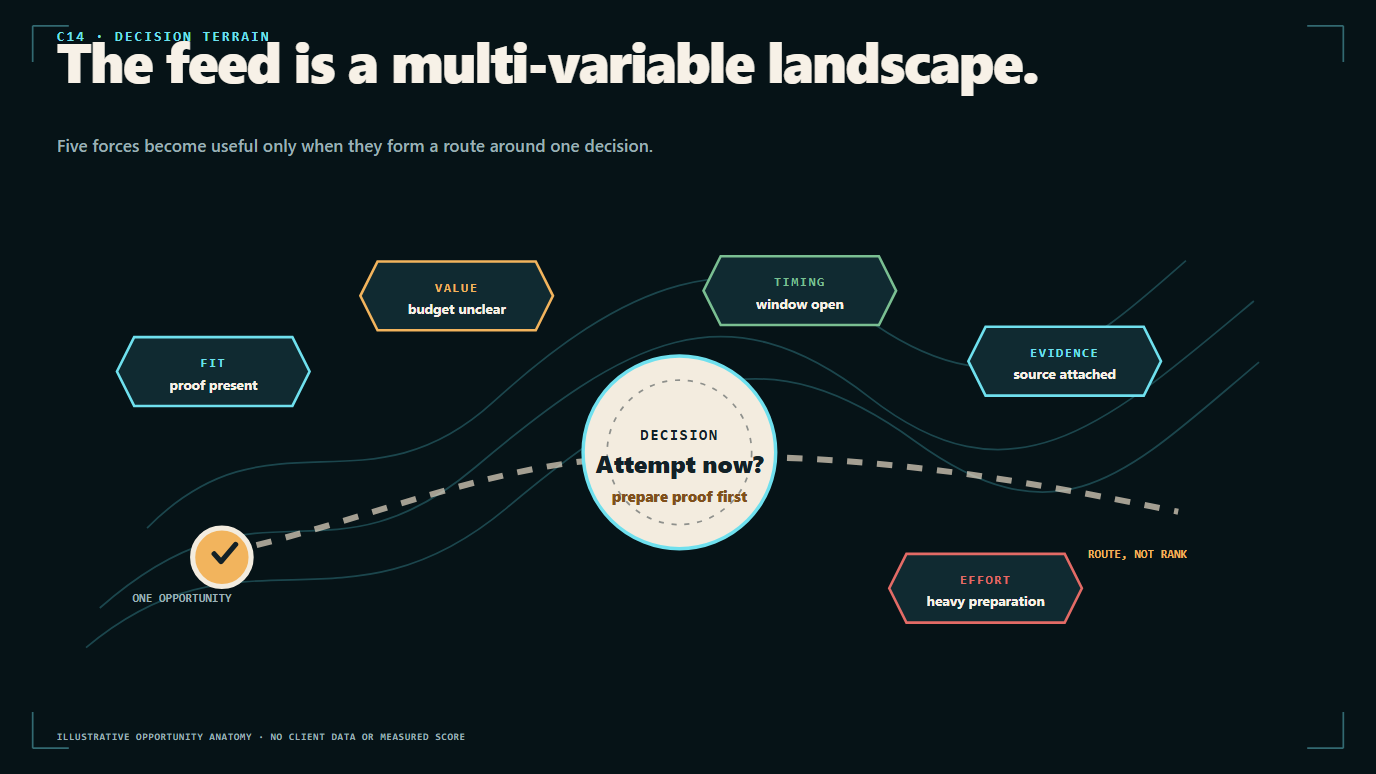
The analogy stops at the opportunity.
Clients are people, and the analogy never casts them as bosses or enemies. The job post is the encounter: a fixed request at a moment in time with a set of visible and hidden requirements. Preparation changes the freelancer's readiness, and enthusiasm doesn't change the buyer's budget, deadline, proof threshold, or authority.
That frame helps the operator make three decisions.
Is this an encounter worth attempting now? What preparation and proof does it require? What can the system learn even if no proposal is sent?
The third question builds the bestiary, a catalog of the kinds of posts the operator has met.
Every saved post earns an archive purpose
A saved opportunity has value before an application exists.
One post can be an immediate candidate. Another can be a warning specimen showing impossible scope, poor budget, copied language, or missing authority. Another can be aspirational: a job the operator can't prove yet but wants to understand and build toward. Another can scout an adjacent market, and another can supply vocabulary or reveal a tool change.
FreelanceBuddy can give each saved post an archive purpose.
A candidate is a post where the system expects a real apply-or-reject decision.
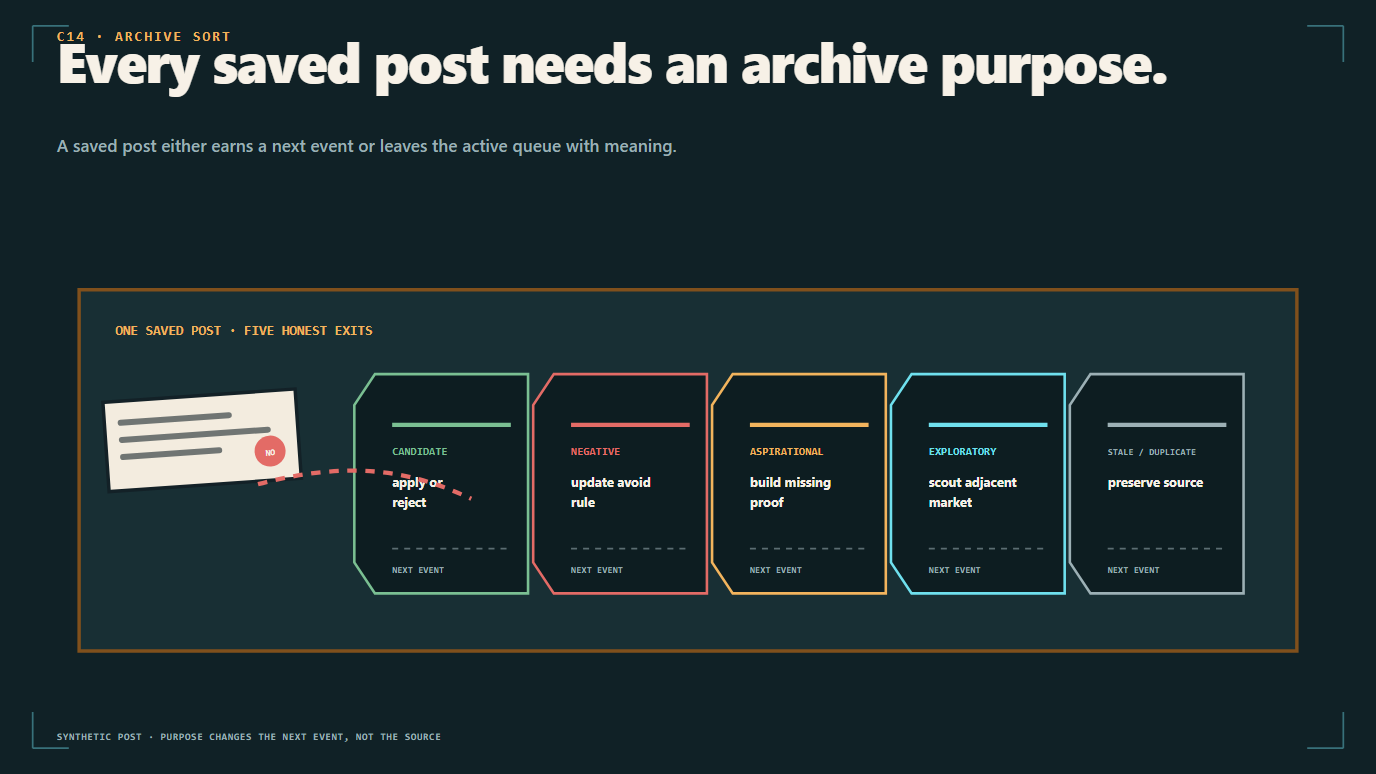
A negative specimen teaches what poor fit or poor quality looks like.
An aspirational specimen defines a capability, proof, or price tier worth developing.
An exploratory specimen broadens the market model without receiving production resources now.
A duplicate or stale specimen stays on record as evidence after it leaves the active queue.
The labels protect the operator from a familiar guilt loop. Saving a post creates no obligation to apply, and the record can pay for itself by improving the map.
The corpus becomes hand-selected market research. Selection itself is biased, so the system should preserve how each post entered: manually saved, scraped from a filter, imported from an alert, or attached to an actual proposal. The rolling market view can then separate what the platform offers from what the operator chose to collect.
Opportunity fields should answer distinct decisions
A wide opportunity schema can capture useful distinctions or become a form nobody trusts. Group its fields by the decisions they serve, and make absence explicit.
Fields should be grouped around decisions.
The source and time group answers where the post came from, when it appeared, and whether it's still actionable.
The buyer evidence group covers verified payment, hiring history, spend, reviews, location, prior job patterns, and signs of real authority where the platform exposes them.
The opportunity economics group holds budget, rate, expected duration, workload, payment type, and uncertainty.
The fit group covers domain, problem, deliverable, tools, role, constraints, and the evidence the operator can stand behind.
The competition and friction group tracks proposal count, interview activity where visible, required questions, attachments, timing, and platform cost.
The strategy group holds the buyer's stated request, deeper problem, desired future, transformation, risks, angle, and proposed next step.
The state group records saved, reviewed, rejected, preparing, submitted, viewed, replied, interviewing, verbal yes, won, lost, withdrawn, closed, or cold, plus the events that justify the state.
The learning group keeps selected assets, lineage, operator feedback, client response, outcome, and later calibration.
The exact field count matters less than coverage and meaning. Each field needs a type, source, freshness rule, and unknown state. A missing hiring history can't silently become zero. An inferred budget can't look observed. A score can't hide which evidence moved it.
The profile page should reveal the groups progressively: the operator first sees enough to decide, and deeper evidence stays one step away.
One score and one market regime answer different questions
An opportunity score estimates the fitness of one post under one rubric.
A rolling market signal estimates the recent character of the corpus.
Those instruments should never collapse into one number.
A strong opportunity can appear during a weak week. A weak opportunity can appear during a rich market. If the operator loses a proposal, the per-opportunity record asks whether the target, package, timing, or conversation failed. The market view asks whether quality, budgets, competition, or hiring behavior changed across many posts.
Recent observations can carry more weight because the feed changes, and the weighting rule has to stay visible and adjustable. A thirty-day view may suit broad market temperature, while a seven-day view may catch a sudden platform shift and get noisy. A human can compare both.
The interface should show distribution before verdict.
How many recent posts entered each quality band? Which dimensions moved? Did budgets fall while fit improved? Did competition rise only in one niche? Are posts older because ingestion slowed? Are the changes large enough to distinguish from ordinary variation?
The system can call the current condition rich, thin, noisy, or uncertain after showing the evidence. It shouldn't paint one dramatic color and ask the operator to obey.
Deal rot depends on stage and expected next event
Time means different things at different stages.
A saved job post can decay quickly because other freelancers are applying and the buyer may begin interviews. A submitted proposal can sit unseen for days without proving failure. A viewed proposal creates a different clock. A buyer reply creates a conversation clock. An interview, verbal yes, or offer creates another. A client who states, “We decide next month,” has changed the expected event.
FreelanceBuddy should calculate rot from stage, last meaningful event, and any explicit promised timing.
The color carries meaning too.
Red means an actionable relationship is slipping and the operator may be missing a sensible step. Blue means the opportunity is frozen: the process is cold or waiting, and warming it may be possible without implying operator failure. Neutral means no action is due under the current expectation. Amber means the next step is approaching or evidence is insufficient.
One rule, such as dark red after five days, makes little sense across every stage. A fresh job post may deserve urgency, while a submitted proposal that hasn't been viewed may reasonably wait longer. A direct reply or interview request may deserve action within hours, and a verbal yes with no paperwork may turn risky after a few business days. Any client-stated timeline should override the general clock until evidence changes.
The operator needs controls for these thresholds.
Global defaults can establish sensible ranges. Stage-level settings can change them. Opportunity-level expected dates can override both. The interface should explain which rule produced the current state and let the human change it without editing code.
A prolonged period without a meaningful event can justify a cold classification under the operator's chosen policy. A buyer-stated future date can justify waiting instead. The record should show both the elapsed time and the rule used; neither a universal age threshold nor a color can replace that history.
Configuration lets an operator inspect and change policy
A threshold hidden in code can apply a judgment the operator has no way to inspect or change.
Deal-rot timing, recent-market windows, score weights, application ceilings, asset budgets, follow-up rules, and autonomy gates all contain judgment. The product can ship strong defaults while exposing the judgments that materially change work.
The settings experience should use the same ordinary language as the opportunity view.
“A fresh saved post becomes urgent after this many days.” “A submitted proposal becomes cold after this window if the buyer hasn't viewed it.” “A reply expects a human response within this time.” “A client-stated next date pauses the general clock until that date.” “Recent market quality weights the latest posts this strongly.”
Each setting needs a scope. A system default applies everywhere. A stage rule applies to one class of opportunity. A niche or channel rule applies to a bounded market. An opportunity override records a specific promise or exception. The closest valid rule wins, and the interface shows which rule it used.
Changes should be versioned. If Andy tightens the viewed-proposal clock from fourteen days to seven, later analysis needs to know which opportunities were managed under which policy. Otherwise the system may attribute an outcome change to a new proposal asset when the real intervention was faster follow-up.
Safe controls also need previews. Before saving a threshold, show how many current opportunities would change state. Before changing a score weight, show how the recent ranking would reorder. Before raising an application ceiling, show current production and client-delivery load. The operator can see the blast radius while the choice remains reversible.
That's the difference between a useful interface and a configurable database. The operator doesn't edit fields; they change a policy, see its consequence, and keep the history needed to learn whether it helped.
Application volume needs fit and delivery limits
A concentrated application run can test a selection and production policy under greater load.
A sprint like that can be a valid practice build, but it needs boundaries.
Application volume is an experimental setting, not a promised number of clients. Track the real denominators: posts reviewed, candidates selected, proposals submitted and viewed, replies, interviews, offers, hires, revenue, retained value, effort and application cost. A higher submission count can only be interpreted alongside fit and downstream outcomes.
The system can compare three builds.
A volume build sends more qualified packages with a strict time budget. It creates many market returns and protects learning velocity.
A precision build invests deeply in fewer high-value opportunities. It spends more research and production capacity per attempt.
A hybrid build uses cheap, consistent packages for clear matches and reserves strategic briefs or videos for opportunities whose value and evidence justify them.
None of them earns a permanent “best” label, because the market and the operator's capacity decide the mix.
A volume policy needs a real fit decision, buyer-specific evidence, current claims, appropriate assets and a human-controlled send action. It should cap work in progress, flag duplicate language and stop when review quality or delivery capacity falls below the agreed limit. The requirement has to be enforced in the workflow before it counts as a protection.
Intensity becomes an experiment with a safety floor.
An application run should leave usable learning without exhausting delivery
Elden Ring's New Game Plus provides a modest image: another journey can begin while at least some progress carries forward. The official patch notes confirm the mode without supporting every dramatic percentage attached to it online.
The useful transfer is banked progress.
A concentrated application sprint should leave durable assets: calibrated scoring, stronger negative specimens, better proposal modules, clearer client archetypes, response evidence, improved thresholds, and a record of operator energy. If the sprint ends and those gains disappear inside chat logs, the system has produced exhaustion without compounding.
The sprint contract can name a start date, application ceiling, daily quality floor, rest window, stop signals, and banking routine.
Stop signals might include repeated low-fit submissions, missed client work, falling review quality, sleep loss, rising correction time, or a backlog the operator can no longer inspect. The system should make those conditions visible before motivation turns them into a dare.
Recovery is part of the build.
The operator can choose an intense cadence because they know their own patterns. The product should help them retain the upside and reduce the predictable damage. It should never convert a personal reset strategy into a universal productivity doctrine.
Proposal assets form a conditional loadout
Not every opportunity deserves every asset.
The available loadout may include a cover letter, answers to qualifying questions, a one-page visual, a strategic technical or creative brief, selected case studies, a guarantee limited to controllable outcomes, a landing page, and a Tella video walkthrough.
The system chooses a package against evidence.
A clear, urgent, smaller request may need a sharp cover letter, direct answers, one proof asset, and a simple next step. A complicated opportunity with several stakeholders may justify deeper research, a strategic brief, and a video. A design-sensitive buyer may benefit from a one-pager whose visual language reflects observable brand cues. A skeptical technical buyer may need architecture, risks, and verification instead of polished marketing language.
The asset planner should explain each choice.
Required assets satisfy the platform or buyer request. Recommended assets address a known decision barrier. Optional assets may add value if production capacity permits. Omitted assets carry a reason: redundant, weak evidence, excessive effort, wrong register, or likely to burden the buyer.
The operator can change the loadout.
Planning assets this way turns a proposal from a template into a compiled package. The world model supplies current evidence, the voice model supplies the right register, and the opportunity model supplies the constraints. The production system assembles only the parts that earn their place.
Qualifying answers need direct, supported claims
Many Upwork posts include questions designed to filter generic applicants.
Some ask for a specific example. Some hide a required instruction. Some test whether the freelancer understands the domain. Some ask for pricing before the scope is clear. Some contain a phrase that must appear in the response.
The system should treat each question as an independent claim contract.
What is the buyer actually testing? Which evidence supports the answer? What can't be promised? Does the requested format conflict with the stronger strategy? Is the question a simple compliance check or a sign of a deeper concern?
The answer should be direct and shouldn't reuse the cover letter as filler. If a question asks for experience with a tool, the response should name the work and the result or say plainly where the experience stops. If the question asks for an estimate, the response should name the assumptions that control it.
Qualifying questions are a good place for an evaluator to be hostile, because a fluent wrong answer can disqualify the package faster than an imperfect opening line.
A one-pager should make its proof inspectable
A proposal often competes in a crowded, low-attention surface.
A one-page visual can give the buyer a fast proof of preparation. It may show the buyer's current situation, desired future, proposed route, risks, relevant proof, and next step. The visual should use cues from the opportunity or public brand without pretending private knowledge.
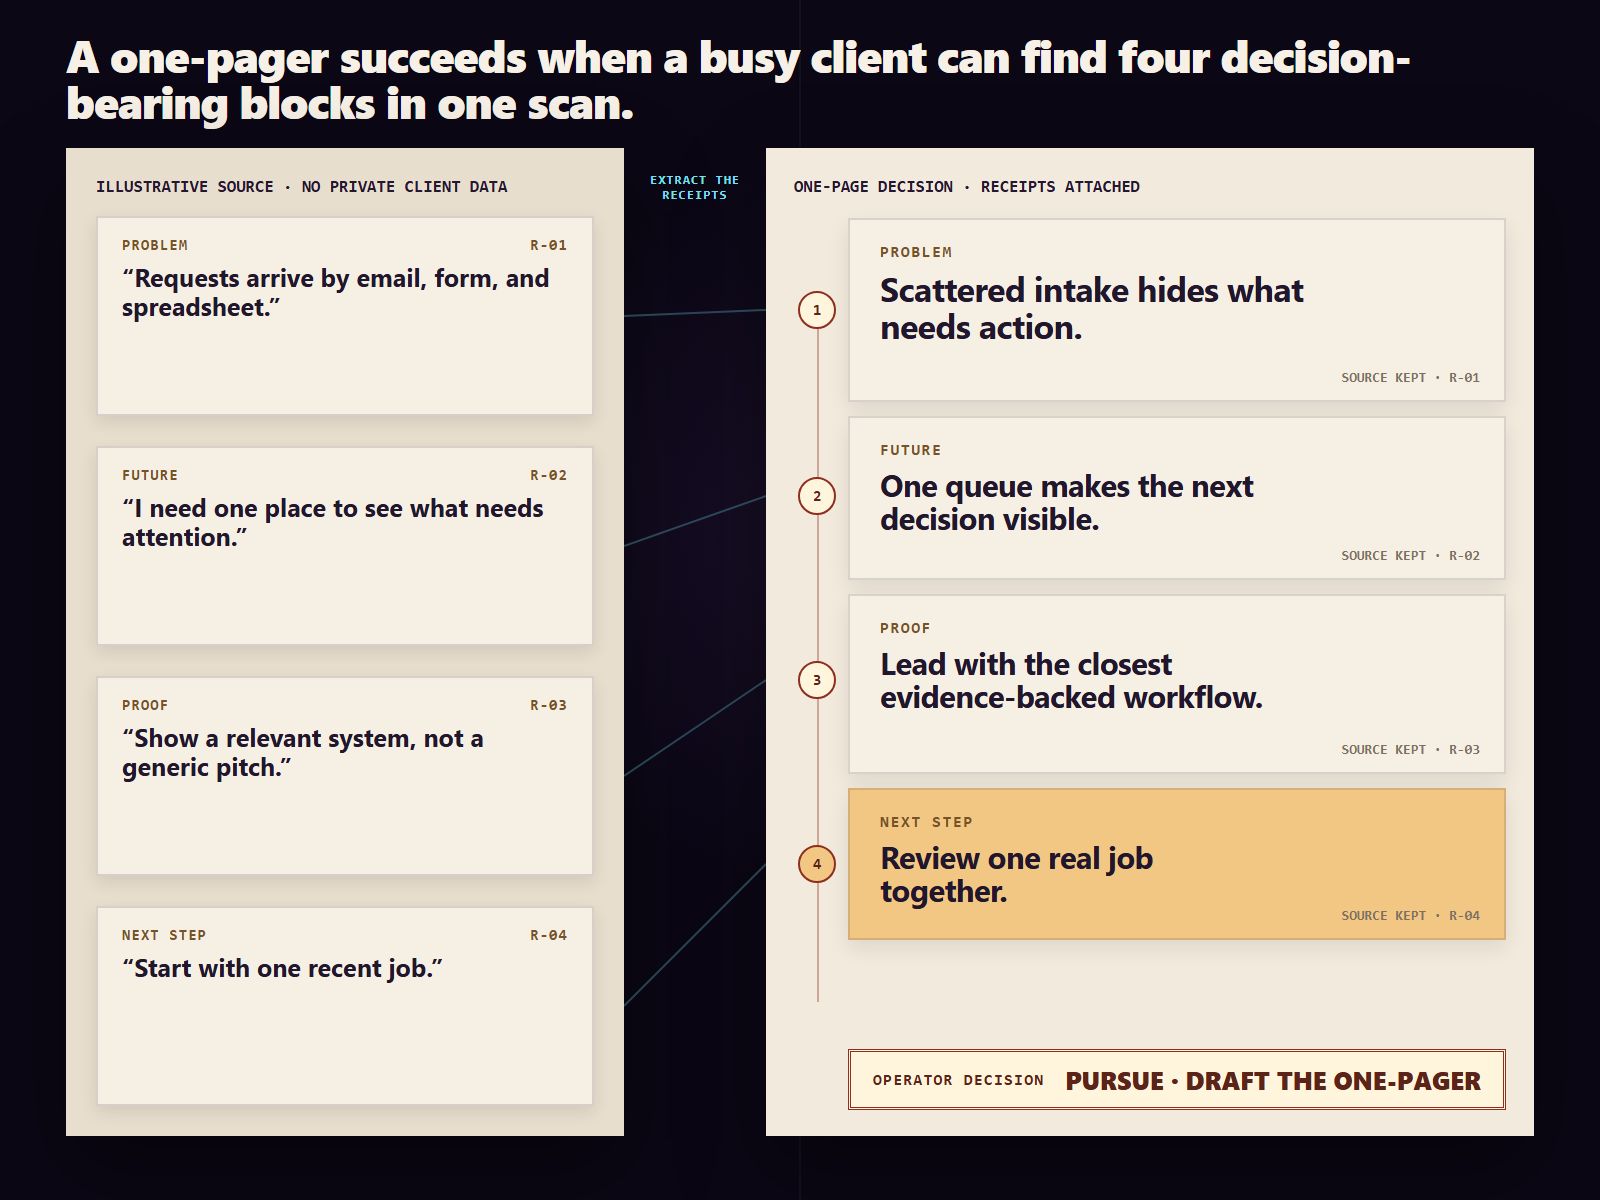
Can the buyer identify that the page concerns their problem? Can they see what changes? Can they find the next step? Does the visual survive thumbnail size and mobile? Does it look like a useful artifact rather than a decorative pitch?
Nano Banana can generate the bitmap foundation through the existing image pipeline. The system still needs a human or evaluator to check text accuracy, visual hierarchy, rights, brand coherence, and whether the image explains anything. Generated polish isn't proof of thought.
The one-pager belongs in the loadout when it reduces buyer effort. It stays out when the opportunity requires a plain technical answer or when the visual would delay a time-sensitive application.
The strategic brief shows the route
The strategic brief is the heavy asset.
It diagnoses the buyer's problem separately from the freelancer's preferred solution, describes the observable future, and maps the transformation between them. It names assumptions, risks, early tests, likely systems, and a safe next step, and relevant figures or motion make difficult relationships concrete.
The brief shouldn't do unpaid implementation dressed up as generosity.
It can show judgment, architecture, sequencing, and evidence without giving away a complete proprietary method or doing the whole contract before agreement. The buyer needs enough to trust the route. The freelancer needs a protected boundary around the engine that makes the route unusually good.
The guarantee follows the same rule. Guarantee response time, process, named deliverables, inspection, correction, and other controllable events. Never guarantee revenue, rankings, viral reach, or another outcome controlled by a market and the client.
The best brief casts the freelancer as a guide. The client stands at point A and wants point B, and the route feels safe, understandable, and valuable enough to repeat at a larger scale.
The video turns prepared assets into human contact
A recorded walkthrough can show how the operator reasons about the buyer's problem.
The operator doesn't begin from a blank recording. The opportunity profile, cover letter, one-pager, and strategic brief have already organized the thinking. The system supplies a short walkthrough scaffold: what the buyer asked, what the operator noticed, what the proposed route changes, which evidence matters, and what should happen next.
The operator records the human layer.
That recording adds voice, judgment, emphasis, humor, and live correction, and the buyer can see that a person understands the work. The system should never clone that presence and pretend the operator recorded something they didn't.
The video may become the largest remaining manual step for many opportunities as FreelanceBuddy matures. That's a reasonable target, because the human moment carries high trust while the preparation around it can be compiled.
A recording earns its place when the buyer needs that demonstration of judgment. Its length follows the material and the buyer's question; it isn't a fixed production-time promise.
Asset lineage turns proposals into experiments
Suppose one animation appears in three briefs, one article appears in ten proposals, and one one-pager is revised four times. Two proposal packages get interviews and eight get silence.
Without lineage, the operator remembers a vibe.
With lineage, every asset has an identity, source, version, parent, use event, comment, correction, and outcome link. The system can ask whether opportunities receiving a particular article had a higher interview rate after accounting for their fit and tier. It can see that one animation gets reused because it explains well or because the template defaults to it.
Correlation remains correlation.
An article may appear in stronger opportunities because the operator selects it for stronger opportunities. A one-pager may correlate with interviews because high-value applications receive more work. The system can record the pattern and design a controlled comparison rather than awarding the asset a magic score.
Lineage also supports reclaim. A lost proposal can contain a strong diagram. The diagram can enter the asset library with the client-specific labels removed, its provenance preserved, and a new review before reuse.
Every application becomes a production run with traceable parts.
Recorded strategy can support reviewed decision rules
At the early supervision stage, the design asks the operator to open an opportunity profile and record the strategy behind the application.
They explain fit, angle, risks, offer, price, proof, asset choices, concerns, and what they think the buyer actually needs. The system asks questions and suggests answers. The operator accepts, corrects, or replaces them. The transcript carries judgment that the structured fields didn't yet capture.
Over time, repeated corrections can become typed policy.
Repeated corrections can support candidate rules about which assets suit an opportunity class, which claims require a case record, which guarantees the operator rejects and which missing evidence should stop production. Those rules need review before they change later work; repetition alone doesn't establish correctness.
The transcript then becomes shorter.
The maturity curve should be defined by observable operator work, not a fictional number of repetitions.
At the dictate stage, the operator supplies most of the strategy.
At co-edit, the system proposes a structured plan and the operator makes substantial changes.
At revise, the system prepares a strong package and the operator corrects bounded details.
At approve, the system prepares the package and the operator mainly inspects evidence, policy, and fit.
At recommend, the system identifies opportunities and loadouts the operator may have missed, while the human keeps authority over sending, pricing, exceptions, and the relationship.
Moving up a stage takes evidence, and less editing time isn't enough on its own. Quality, claim accuracy, outcome calibration, and reopenability all have to hold.
Assistance leaves consequential authority with the operator
Elden Ring lets a player use spirits as assistance. The image is useful when kept small: an assistant can carry capabilities developed through the player's build.
FreelanceBuddy can carry retrieval, scoring, question analysis, asset assembly, checks, reminders, and report preparation. The operator retains authority over consequential actions.
The human chooses business boundaries, sends proposals, changes prices, handles sensitive claims, speaks to clients, approves publication, and decides when the system should stop. Some decisions may later be delegated under policy, and the authority has to stay visible and reversible.
That arrangement is supervised autonomy.
The product becomes better than the operator at a bounded task when it produces more reliable results under an accepted evaluation, not when it sounds confident or saves a few minutes. It can outperform first-draft writing while remaining unable to own the relationship.
The system should show what it knows, what it inferred, what rule it used, and where the human can correct the rule.
A close-time estimate needs a defined event and uncertainty
A buyer doesn't close on the day a dashboard predicts.
The opportunity moves through uncertain time. Some proposals stay unseen, and some are viewed and revisited. Some receive a reply after a long internal delay. Some buyers hire somebody else, some close the post, and some go cold without a clear ending.
Time-to-event analysis gives the right statistical frame.
Define one starting event, such as proposal submission. Record the time of a win, loss, withdrawal, or last observation. An opportunity still open at the last observation is right-censored: its final time remains unknown rather than being counted as a loss. The scikit-survival research paper describes censored time-to-event modeling and evaluation.
A survival curve estimates the probability that its defined event hasn't occurred by a given time. With one event type, its complement describes that event's cumulative probability under the model. A sales pipeline has competing outcomes, so one minus an all-closure survival curve isn't a win probability. A hazard is a conditional event rate, not a promised close date. The display should show which event is modeled and what the observation history supports.
Sales adds competing outcomes. A win and a loss can prevent one another as the first closure event, so they should be modeled separately rather than treating every loss as an opportunity that might still win later.
The interface should translate this into ordinary language.
“Most similar opportunities that eventually received a reply did so inside this range.” “This opportunity remains open but the expected response window has widened.” “A client-stated delay moves the next expected event.” “Silence after a view is different evidence from silence before a view.”
Never show one false-precision close date.
New events change the estimate
Every meaningful return can update the distribution.
A recorded proposal view supports the narrower statement that the platform registered a view. It doesn't prove who read the package or how much they understood. A buyer's reply supplies stronger direct evidence, and an interview changes the stage and expected next event. A stated delay, verbal agreement, competing hire or closed post changes the available interpretation again.
The update should explain itself.
The operator can see the previous range, the new event, the updated range, and the rule or model involved. If the model lacks enough history, it should use broad bands and say so. Opportunity-specific stated timing should outweigh a generic platform average until contradictory evidence arrives.
The time model also helps allocate production effort.
A fresh low-confidence opportunity receives a cheap initial package. A promising conversation may earn a deeper follow-up asset. A high-value opportunity with clear authority and strong engagement may justify direct lookahead across several proposal strategies. Most opportunities should use simpler policies so the operator's scarce attention remains available for consequential exceptions.
The cost of a decision should determine how deeply to analyze it
Warren Powell's sequential-decision framework offers four broad method classes that transfer cleanly.
Policy function approximation uses a direct rule. If a submitted proposal hasn't been viewed after a stage-specific window, schedule a bounded follow-up check.
Cost function approximation scores an action using selected costs and benefits. The system may decide whether a one-pager earns its production time for this opportunity tier.
Value function approximation considers expected future value. A relationship with expansion potential may justify greater effort now.
Direct lookahead approximation compares possible future action paths through an approximate planning model. It belongs to rare, expensive, consequential decisions rather than every routine application.
The taxonomy protects the system from using its most expensive intelligence everywhere. In the interface, routine choices can show a simple policy and reason; only rare, high-consequence opportunities open the deeper planning workspace.
Five daily applications shouldn't trigger five miniature consulting engagements. Cheap recurring decisions use tested policies. High-stakes exceptions receive deeper reasoning and human attention.
The CRM continues after the proposal
Winning the job is one event in a longer relationship.
The opportunity becomes a client. The client enters onboarding. The system records promises, access, deliverables, meetings, decisions, assets, risks, and next events. The first “wow” moment becomes an observable milestone: the client receives something that changes confidence or capability. A first review checks whether delivery matches the agreement. A longer contract begins only after the work earns it.
Client maturity should never mean time served.
It can mean clear authority, stable communication, validated value, repeatable delivery, trusted data, and an agreed path to a longer relationship. Each transition needs evidence.
Opportunity and application management come before the larger post-win relationship model in this design. That later work remains on the map because acquisition shouldn't create a set of clients the delivery system can't support.
The resource bar applies here too: closing deals faster than onboarding capacity allows creates a nanostall.
Daily reports emerge from events
A daily client update feels expensive when a person must reconstruct the day from memory.
An event-sourced system has already recorded work: task changes, agent runs, decisions, comments, files, tests, meetings, blockers, approvals, and results. A reporting activity can group those events into shorter intervals, then compile a day-level view.
The client report should separate five things.
The activity part says what happened.
The evidence part shows what supports the statement.
The outcome part says what changed for the client.
The risk or decision part says what needs attention.
The next event part says what the client should expect and when.
A complete event log proves the events were recorded without proving the work created value, so the report needs both the trace and the interpretation.
The specified future can compile hourly or four-hour summaries into a daily surface. The cadence should match volume and client preference. A quiet project doesn't need manufactured updates, and a fast multi-agent sprint may benefit from frequent internal chapters and one calm external report.
Every summary keeps a route to its source events, so the client sees the useful surface and the operator can inspect the trace underneath.
FreelanceBuddy should prove one operator loop before wider coordination
The product needs a boundary.
FreelanceBuddy serves one operator managing freelance opportunities and client work. That scope is a legacy dungeon: authored, bounded, difficult enough to prove the systems, and small enough to finish.
The Swarm Layer is the later open world. It may combine customer relationship management, sales, project operations, workflows, knowledge, agents, reporting, and multi-person coordination across a company.
Building the Swarm Layer first would hide whether the core loop works.
FreelanceBuddy can prove opportunity ingestion, scoring, asset planning, supervised generation, human decision, submission events, outcome learning, client handoff, and reopenability. The proven components can generalize later, and the failed assumptions can be corrected before many teams inherit them.
That order is product sequencing and research design at once.
One operator supplies dense feedback. The product can observe where cognitive load remains, which suggestions get changed, what evidence is missing, and whether the interface supports a high-volume real workflow. The operator's personal system becomes a laboratory for the enterprise one.
The public claim stays bounded. FreelanceBuddy isn't yet a better version of every CRM; it's the place where the operating model earns that ambition.
A practice block preserves each decision and return
The application run becomes deliberate practice when every attempt creates an inspectable return.
A declared sampling rule makes the practice block interpretable
A practice block needs a declared sampling rule before collection.
Choose a bounded set of recent posts and record why each was included. Interest is an intake filter, not a fit decision. Sort the selected records before proposal production begins, and preserve the ones that teach even when they don't merit an application.
Every post receives an archive purpose and a score before send. The score exposes its evidence groups rather than hiding behind one rank. The operator can see why a post looks strong, which fields are unknown, how old it is, whether the buyer has a credible hiring history, which proof exists, and what the package would cost to produce. A fascinating post can remain exploratory. A weak post can remain a negative specimen. A high-value post outside the current proof can enter the aspirational set. A strong, fresh match becomes a candidate.
The selected block supplies a first market snapshot. Show the distribution of quality, budgets, fit, competition and age with the selection rule beside it. Hand-picked posts describe the collected sample, not all of Upwork. Later blocks can show whether the same selection process encounters different conditions.
Candidates then pass through a score-before-send gate. Andy reviews the opportunity, corrects evidence, chooses a loadout, and records the strategy transcript. The system timestamps the decision. Once submitted, the post leaves the research-only corpus and enters the outcome ledger with a defined starting event.
Deal rot follows the stage policy from that point. Fresh unsent candidates carry an urgency clock because the market is moving. Submitted and unseen proposals carry a wider window. A view starts another expectation. A reply, interview, stated delay, verbal yes, and offer each create their own next event. The interface shows the active rule and allows an opportunity-specific override when the buyer supplies a real date.
Every return updates the world model. A view adds a platform-recorded event; a reply adds direct buyer evidence. A reply adds language, objections, timing, and intent. An interview adds richer fit and authority evidence. Silence remains ambiguous but changes the time distribution. A loss, closure, or withdrawal becomes a labeled outcome. The absence of a clean ending stays unresolved rather than being rewritten as failure.
The sprint needs stop and recovery signals before the first proposal leaves. Falling below the fit floor, repeating generic language, growing correction time, missing current-client work, shrinking sleep, or accumulating an unreviewed queue can pause new production. The system should show the reason without turning a safety limit into a scolding badge.
At the end of the block, review the score corrections, stage timing, selected and rejected assets, proposal effort, views, replies, interviews, outcomes and delivery load. The next block starts from those records. Improvement remains a hypothesis until a comparable later run shows what changed.
Before sending, score the opportunity and record the loadout. After sending, capture views, replies, interviews, offers, hires, losses, closures, and time. Review failures for target fit, weak evidence, poor timing, wrong asset choice, vague offer, excessive effort, or unknown cause. Preserve unknown rather than inventing a lesson.
Review asset lineage on a cadence. Which articles, visuals, case studies, and brief patterns appear in interviews? Which never get used? Which create buyer questions? Design comparisons where confounding is obvious.
Calibrate the close model against actual outcomes. Did the predicted bands contain the events? Did the model overestimate viewed proposals? Did one stage clock create false alarms? Adjust the operator controls.
Run reclaim. Extract useful language, components, research, and negative specimens from lost opportunities. Remove private client context. Reverify claims before reuse.
Review the sprint itself. How much operator time did each application require? Where did cognitive load remain? Which automation reduced thought and which merely moved it? Did volume weaken current client delivery? Did the recovery plan work?
Then bank the run.
The archive holds stronger rubrics, reusable assets, clearer policies, calibrated timing, market observations, and recovery notes. The next sprint begins from that state rather than from motivation alone.
That's the Elden Ring image worth keeping: the next journey carries a developed build, but the player still has to read the terrain.
One complete operator journey can test the design
The complete vision contains many systems. The first playable slice can be strict.
Ingest one recent job post into the canonical opportunity record. Show the source and freshness. Score it with visible evidence. Let the operator accept or change the classification. Generate a bounded asset plan. Ask for a short strategy transcript. Compile one cover letter and one conditional proof asset. Run an independent check. Let the human approve or reject. Record the submission event manually if platform automation is unavailable. Reopen the opportunity later and record the buyer return.
Then compare the run with the prior one.
The slice can be accepted through one concrete operator story.
In an illustrative acceptance scenario, the operator opens a newly captured post. The source text and capture time are present. The page distinguishes known hiring history, incomplete budget evidence and relevant case records. The overall score is visible, and each contributing judgment can be inspected. The operator changes a fit judgment and records why.
The system proposes a bounded package: a cover letter, direct answers to the buyer's questions, an existing case study and a one-page route map if that visual earns its production cost. It omits a long brief when the opportunity doesn't justify the effort. The operator records a correction to the angle and removes an unsupported claim.
A specialist compiles the package. A separate evaluator catches a claim in the one-pager that its case study doesn't establish. The finding returns to the producer, and the corrected package retains its change and rejection history. The operator can inspect the source, candidate, correction and final asset together.
The operator approves the application. Manual platform submission can remain a declared step: the interface supplies the package and records the operator's confirmation after sending. A later reopen shows the submission event and any recorded buyer view, with its evidence source. The stage clock and next action change under the active policy.
A subsequent buyer reply reopens the same opportunity with its source, submitted package, event history and question. The operator answers and the system retains any correction. An interview, if it follows, inherits that context instead of starting as an unrelated chat.
That one story crosses the important boundaries: data, scoring, strategy, production, evaluation, authority, event state, time, and re-entry. It doesn't require automatic platform control, a mature probability model, or the Swarm Layer.
The vertical slice should fail acceptance if any one of those boundaries is decorative. A score without evidence fails. A generated asset with no correction path fails. An approval that doesn't change state fails. A submission with no event fails. A buyer return that can't reopen the production context fails. A working terminal command with no human surface fails.
The test is severe because the scope is small. Passing it creates a product Andy can use during the application sprint, and every later capability then has a real path into the product.
That slice is enough to reveal real friction. It tests the typed model, operator controls, proposal loadout, voice, evidence, evaluation, event stream, and reopen path without requiring the whole Swarm Layer.
It also makes SuperHarness useful in a human way. The harness stops being a collection of profiles and dashboards and starts helping one person turn a live opportunity into an inspected action and learn from the result.
The product has become playable when the operator can perform that loop repeatedly from the interface without returning to a terminal to reconstruct state.
FreelanceBuddy is therefore the nearest place where the map can answer back every day, which makes it more than a CRM example inside Hyperrelevance Cartography.
A saved post changes the market model. A scored opportunity changes allocation. A proposal changes the buyer's field. A response changes the stage and timing. A win changes the service system. A loss changes the bestiary. A client outcome changes the proof available to the next opportunity.
The map stays alive because the work keeps touching the world.
15. Specialist businesses need different views of one engine
A shared engine becomes easier to understand when you stop staring at the engine.
Look at the workbenches instead. One bench holds market data, risk limits, positions, and execution records. Another holds jokes, formats, cultural references, and distribution feedback. A third holds client worlds, editorial systems, production queues, and attribution. The fourth holds public field notes that expose the reasoning without exposing every private mechanism.
The benches look different because the jobs differ, and the shared shape sits underneath them. The Alpha Is a Compiler develops why the reusable transformation system can matter more than any single output it produces:
- Build a current model of the environment.
- Find a costly uncertainty.
- Produce an artifact or action that tests the model.
- Observe the result.
- Preserve the evidence and update the model.
The same loop can support many businesses because the loop is abstract and the world models are specific. The danger begins when the abstraction eats the specificity. A joke engine that speaks like a trading desk will fail, and a trading system that treats risk like engagement will fail more expensively. Shared infrastructure has to carry a common discipline while each business keeps its own objects, vocabulary, constraints, and proof.
Trading requires its own data, risk and execution evidence
In this portfolio design, Tesseract Markets occupies the financial-market role and Grid Trade Pro stays within the private research boundary. Andy's documented algorithmic-trading work provides a real reference for the data-engineering problem. It doesn't establish a fund's current regulatory or operating status.
The boundary matters. A strong public explanation can cover the ordinary mechanics of market making, risk, execution, and research without publishing the parameters, signal stack, portfolio logic, or proprietary edge that give the system its commercial value.
The hyperrelevance loop here begins with a market state rather than an audience state. Prices, liquidity, volatility, positions, and events change over time. A model that was useful in one regime can become dangerous in another. The system needs current data, temporal context, explicit uncertainty, and a way to test whether a signal still survives.
Echolocation is a practical metaphor here. The engine sends a probe into the current environment, and the return pattern changes with the regime, so a response that once meant open space may now mean a wall. The operator keeps measuring because a memorized map can't price a moving market.
Trading is also the cleanest example of why a metagraph carries more than facts. The system needs relations, probabilities, time, provenance, and state transitions. “Asset A correlates with Asset B” is incomplete without a period, a regime, a method, and a confidence level. “This order executed” differs from “this strategy should execute.” Observations, decisions, and policies have to stay distinct objects.
The public lesson is broad: a decision engine becomes safer when its evidence, assumptions, actions, and outcomes can be inspected separately. The private edge remains private.
Meme Shaman would test jokes within a particular community
Meme Shaman faces a market where the units are messier. Humor depends on shared context, timing, format, identity, and the audience's willingness to pass the object along. The same image can feel sharp inside one community and painfully generic inside another.
Those conditions make a meme a small hyperrelevance test.
The proposed Meme Shaman loop researches a target community, maps its vocabulary and recurring tensions, identifies familiar formats and produces a candidate joke for human review. Audience reactions would then supply returns. This describes what the product must connect, not a verified release pipeline.
The compiler framing is useful because humor has constraints. A setup introduces a model. A turn changes the model. Timing controls when the audience sees the mismatch. The image, caption, reference, and platform format have to resolve together. Throwing a trending template at a generic brand message satisfies the file format and misses the joke.
Human taste remains the gate. A language model can retrieve patterns, generate candidates, and explain why a structure might work, but it can't guarantee that a community will grant the speaker permission to make the joke. The evaluator has to ask whether the reference is current, whether the speaker belongs, whether the target is fair, whether the joke carries the intended meaning, and whether it's funny before any strategic explanation arrives.
The accumulating map would record which groups share references, how meanings drift, which formats invite participation and what observed releases taught. A prompt alone can't supply that history. Keeping the map useful requires real releases and returns, permission to retain the material, and correction when the interpretation fails.
Constellation Media would share infrastructure across specialist shops
Constellation Media supplies the multiplication model.
Imagine a group of specialist agencies. One understands industrial equipment. Another understands local service businesses. Another produces technical education. Another builds humor for a narrow consumer niche. Each agency needs research, retrieval, production, review, distribution, attribution, and memory. Building those systems from scratch inside every agency wastes time and creates different quality failures in every shop.
The proposed shared engine supplies the repeated infrastructure.
The conductor can route a job through research, world-model retrieval, voice analysis, content production, creative production, evaluation, and delivery. Shared observability shows where work waits or fails. Shared evidence rules make claims traceable. Shared quality gates prevent one agency from quietly lowering the bar under deadline pressure.
What the client sees stays specialist. A construction client shouldn't receive a generic “Constellation output.” The client receives work that reflects the construction world, buyer, region, product, vocabulary, and business objective, and the underlying engine disappears into the competence of the result.
Sharing infrastructure while preserving each agency's local knowledge can reduce repeated work without making the outputs generic. A correction to the shared citation system improves every agency. A better visual-legibility gate protects every publication, and a new privacy control strengthens every tenant. A mistake discovered in one workflow can become a warning before the same class of mistake reaches another customer.
The propagation has limits. Customer material can't leak across tenants. A pattern learned in Alaska construction doesn't automatically transfer to a financial audience. A shared model may improve a prior, but local evidence still decides. The conductor makes reuse possible and provenance makes reuse governable.
Public articles let a reader inspect and challenge the method
AndyDataGuy is where the machinery becomes legible.
The Field Notes describe earlier failures, mechanisms, decisions, and working artifacts. A reader can see how a claim was derived, where a tool failed, what correction changed the system, and what remained uncertain. The property turns internal learning into public proof without publishing private customer data or every implementation detail.
An article can perform that role only when its source trail lets a reader challenge its claims. This revision preserves the original TypeScript snapshot, identifies inherited references and separates proposed product behavior from recorded case evidence. Independent review and publication are later steps; a description of the process isn't proof that those steps happened.
The public object has several jobs.
It teaches the concept to somebody who has never seen the rest of this work. It gives a prospective client a way to inspect judgment before buying, and it gives future agents a source they can retrieve and challenge. It creates a durable timestamp for the model as it existed today. It also invites return signals: disagreement, confusion, resonance, qualified inquiries, and later evidence.
The Field Note therefore functions as both artifact and sensor.
Being a sensor doesn't make every post a sales page. The strongest signal may come from a reader who never buys and still exposes a weak claim, and the engine improves when it values correction alongside conversion.
Each business gives the shared loop a different constraint
The four businesses reveal different scarce resources:
- Tesseract manages capital, risk, and execution opportunity.
- Meme Shaman manages cultural attention, timing, and permission.
- Constellation manages production capacity, tenant boundaries, and reusable process.
- AndyDataGuy manages public trust, legibility, and the conversion of lived work into durable knowledge.
Their outputs differ because their markets differ, and their shared advantage comes from disciplined observation, explicit state, reusable workflows, evaluation, and memory.
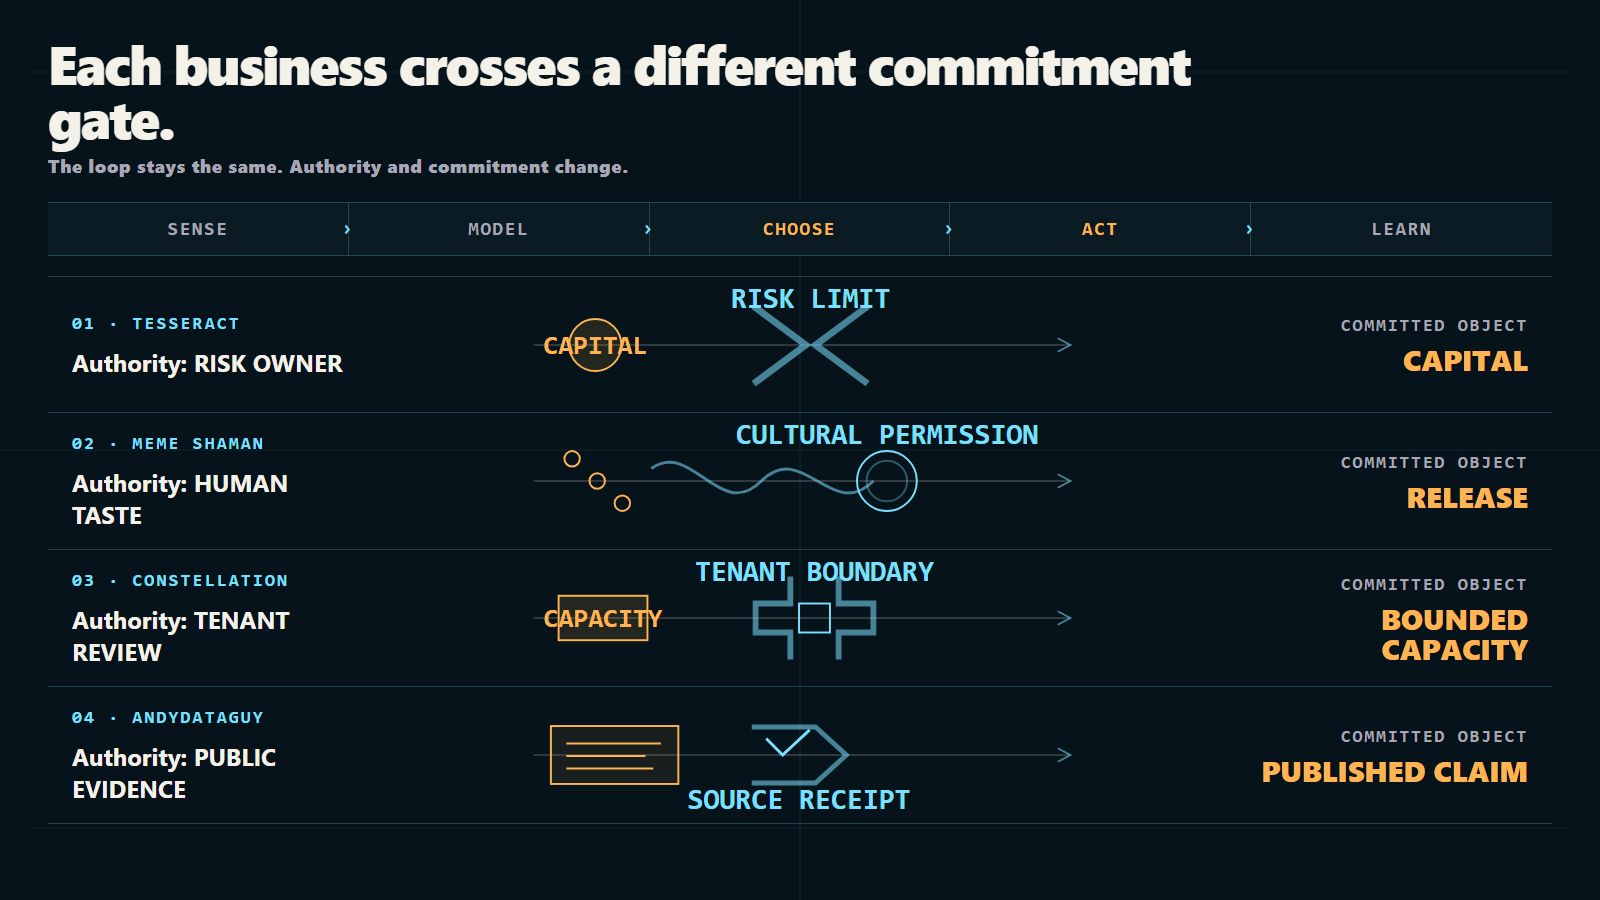
The architecture becomes valuable when a better primitive crosses the portfolio without dragging private data behind it. That's the promise of one engine, and the promise depends on a boundary that keeps it from becoming a leak.
16. One engine can serve many shops
A commercial kitchen can serve several restaurants.
The kitchen shares ovens, refrigeration, cleaning rules, safety checks, receiving docks, and maintenance. Each restaurant keeps its menu, ingredients, pricing, customers, service style, and reputation. A better sanitation process should spread to every restaurant. A secret sauce shouldn't appear on the neighbor's plate.
Multi-tenancy works the same way. A tenant is a customer or operating unit that uses shared parts of a system while expecting its data, configuration, usage, and outputs to remain within defined boundaries. The architecture may pool some components and dedicate others. Sharing is a design choice, not a moral virtue. RAG Systems shows why retrieval boundaries have to preserve the world a result came from instead of relying on a screen-level filter.
The business case is strong. Shared infrastructure reduces repeated build cost. Shared operations make failures easier to observe. Shared quality systems let one correction protect many surfaces. Shared capacity can keep expensive resources busy instead of leaving one copy idle inside every agency.
The risk is equally strong. A weak boundary can expose one client's data to another, let a noisy customer consume common capacity, apply the wrong configuration, or preserve supposedly deleted material in embeddings, logs, caches, generated assets, and backups.
A tenant boundary has to survive retrieval, generation, evaluation, export, and deletion. A user-interface filter isn't isolation.
Namespaces give every world an address
The metagraph needs a way to say which world an object belongs to.
A namespace provides that address. Customer documents, entities, facts, voice models, workflows, policies, and outputs can carry a tenant or project scope. Retrieval begins inside the relevant scope. Cross-tenant sources require an explicit rule, provenance, and a reason the transfer is allowed.
Scoping prevents a common failure, where the engine remembers something useful and forgets who owned it.
Public sources can often be reused broadly. Customer-provided materials may be restricted to one tenant. A workflow template may belong to the operator while its filled instance belongs to the customer. Aggregated learning may be allowed only after de-identification and contractual permission. Some knowledge should never cross the boundary at all.
The architecture records those categories instead of asking an agent to guess.
Shared learning needs a receipt
“The system learns from every customer” sounds attractive until the customer asks what learning means.
The answer has to name the object and the boundary.
The engine can learn that a citation checker misses a certain URL shape. It can learn that a mobile visual becomes unreadable below a delivered type size. It can learn that one workflow creates queues or that one class of source needs a second verification pass. Those are system-level improvements that don't require exposing customer content.
The engine might also observe that a phrase, offer, or channel worked for one tenant. Reusing that pattern elsewhere needs more care. The evidence arose in a particular market, time, audience, and context. Transfer requires a mechanism, not enthusiasm. The receiving tenant still needs local testing.
Every propagated improvement should therefore answer four questions:
- What changed?
- Which evidence caused the change?
- Which tenant material, if any, contributed?
- Where is the change allowed to apply?
That receipt lets the portfolio compound without turning “learning” into a euphemism for memorization.
Multi-tenancy compounds the engine without blending the tenants
Constellation Media's proposed shared layer addresses infrastructure problems that recur across specialist agencies.
Every agency needs intake, source handling, research, profile routing, artifact production, review, distribution, measurement, and a reopen path. Building those mechanisms once creates leverage. Improving a shared citation check, mobile rendering rule, or dispatch receipt can improve every agency that uses the engine.
Each agency still needs its own world.
A construction dealer in Alaska, a quantitative trading product, a humor compiler, and a personal intelligence brand shouldn't share one unmarked memory pool. They use different evidence, vocabulary, risk limits, channels, customers, and definitions of success.
A tenant namespace gives each world an address. Access policy defines who may read and write it. Provenance records where shared improvements came from. Transfer rules decide which learning can cross a boundary. Microsoft's multitenant architecture guidance describes the same basic choice between shared components, isolation, and dedicated deployment.
Three classes of material help sort what can cross.
Shared mechanics include platform code, generic renderers, evidence schemas, accessibility rules, and quality checks. These can usually improve for everyone.
Tenant patterns include observed audience behavior, local vocabulary, channel fit, and offer performance. These may transfer as hypotheses after de-identification and local testing.
Tenant secrets include private customer data, contracts, source recordings, internal decisions, credentials, and protected strategy. These stay inside their authority boundary.
The classes keep scale from becoming extraction.
They also clarify the business model. A customer buys useful output, a controlled experience, and the rights promised in the agreement. The engine owner keeps the general machinery and the improvements it has a right to retain. If a customer funds a dedicated invention, the contract can assign that invention clearly instead of relying on vague language about learning.
This model can serve dozens of agencies without making them identical. Shared infrastructure lowers the cost of disciplined work. Tenant world models preserve the local differences that make the work relevant.
Some tenants need dedicated infrastructure
Pooling isn't always the right answer.
A regulated customer may require dedicated storage and compute. A hostile data boundary may forbid shared retrieval infrastructure, and an unusually heavy workload may harm every other tenant. A contract may require physical or logical segregation beyond the shared default. A dedicated deployment can then reuse the same source, workflows, and quality rules while isolating the runtime resources.
The product can therefore support tiers of isolation. The principle stays stable: share what improves the system and isolate what creates unacceptable risk.
Tiered isolation is how the golden goose survives.
Customers receive the artifacts, outcomes, evidence, and rights named in the contract. The operator keeps its shared engine, orchestration, general methods, public research, and permitted improvements. The system explains enough to earn trust and support inspection without handing every internal map to every buyer.
The contract, access controls and delivered work have to support that division of rights. Useful output can demonstrate competence while the reusable implementation stays private; secrecy doesn't excuse unsupported claims about either one.
17. Practice cartography before claiming mastery
You don't need a metagraph, an agent fleet, or a three-dimensional interface to practice the method.
Start with one market and one decision. The practice is complete only after a real return changes the model. Research, vocabulary, voice, and simulation are instruments inside that cycle, not separate accomplishments.
Pick a question whose answer can change something this week. “What do local excavation contractors care about?” is too wide. “Which proof would make an Albuquerque excavation contractor book a machine-control demo?” gives the work a buyer, place, action, and stop condition.
Then run six small practices that prepare one bounded commitment.
A world model separates observations from interpretations
Write down the people, objects, events, constraints, and relations that matter.
Who buys? Who uses? Who influences? What equipment, software, money, documents, and risks move through the system? Which event begins the buying process? Which event ends it? What can block the path?
Keep observations separate from guesses. “Three contractors mentioned rework” is an observation when the calls exist. “Rework is the main buying trigger” is an interpretation. Give the interpretation a confidence level and a next test.
The first model can fit on one page, and its job is to expose what you don't know.
Vocabulary preserves distinctions inside the work
Collect the words people use while doing the work.
Record exact phrases from job posts, calls, forums, manuals, reviews, proposals, and support conversations. Define each term in ordinary language. Note who uses it, what it distinguishes, and which nearby terms should remain separate.
Then test yourself. Can you explain the buyer's problem without borrowing vague category language? Can you recognize when two people use the same word for different mechanisms? Can you ask a question that sounds like it belongs inside the work?
Vocabulary is evidence of proximity when the distinctions are correct.
Voice comparison requires permission and current samples
Choose a person with enough source material and permission to study it.
Map favorite words, sentence lengths, recurring structures, parts of speech, transitions, examples, subjects, humor, and the situations that change the voice. Compare a polished article with a voice memo and a tense support reply. The differences may be part of the fingerprint.
Generate a short passage, then compare it against real samples. Mark imitation tells, missing habits, false polish, and phrases the person has outgrown. The goal is a living model that supports authorship, not a museum copy of old text.
A drift audit checks consequential assumptions against current evidence
Take one belief the market treated as obvious six months ago.
Search for current evidence. Check product releases, platform rules, buyer language, competitor offers, prices, and recent behavior. Record what stayed stable and what moved. Expire the claim when the conditions no longer hold.
Drift audits work best on consequential assumptions. Audit the advice that drives spend, authority, positioning, or irreversible technical choices before polishing facts that change nothing.
A rehearsal earns a real test of its assumptions
Build one artifact that forces the model to predict.
A simulation can expose an assumption before release. A real probe then tests it: send the proposal, show the price, run the bounded campaign or ask the buyer to inspect the proof, within the authority and consent the action requires. Define the expected return in advance so a disappointing result can't be renamed as success afterward.
Record the miss with the same care as the hit.
A wider market tests which parts of the model transfer
A geographic expansion can start in a familiar local market, move into another region and then test national or international reach. Treat that sequence as an illustrative progression, not evidence that any named city is an available equipment market.
Distance itself doesn't create rigor. The progression tests whether the operator has absorbed the signal well enough to carry it somewhere new.
A message may work in Albuquerque because the operator understands the local economy, references, and relationships. Moving to Dallas-Fort Worth changes competition, scale, buyer mix, and vocabulary. A national test removes more local context. A global test introduces language, culture, regulation, timing, and market structure.
At each ring, ask which parts of the model survived and why.
A mechanism may transfer while the phrase doesn't. A pain may transfer while the buyer's proof standard changes. A format may travel while the humor fails. The system earns wider claims one ring at a time.
One bounded drill should leave a prediction, return and correction
Keep the first practice bounded to one market, one buyer, and one decision that can change this week. Write the plausible answers before research begins. That first page records the possibilities before the choice, not a prediction you reconstruct after seeing the result.
Turn the decision into a usable question. Name who acts, what changes, and when the answer is needed. Build one world-model page and one vocabulary sheet because those are the smallest instruments this decision needs. Add the buyer's problem, desired future, proof threshold, and constraints. Value Optimization offers a deeper practice for deciding which value-producing move deserves scarce attention next.
Narrow the options with current evidence. Cross out routes that lack proof, violate a real constraint, answer the wrong buyer, or can't produce a readable return. Keep the surviving alternatives visible. Choose one artifact and write down the expected event before release.
Commit the act. Send the proposal, publish the field note, show the price, or run the small campaign. Record the version, audience, timing, and conditions. Then wait for the return you named rather than shopping for a flattering metric.
At the end of the week, compare the event with the prediction. Which belief lost confidence? Which relation appeared? Which word carried more meaning than expected? Which source proved unreliable? Which next probe now has higher value?
Write one correction note and one reopen condition. “Reopen if two qualified buyers describe the risk as onboarding rather than price” is usable, and “Revisit later” isn't. The cycle is complete when the evidence changed the map and the next operator can see why.
18. The map never becomes the territory
Return to the dark room.
One clap gave you a wall. The second suggested a doorway. A step changed the angle. The room became more usable without becoming fully known.
Hyperrelevance works the same way.
The system can build a current model, retrieve the right evidence, preserve relations and time, coordinate specialist agents, produce difficult artifacts, measure response, and carry learning into the next decision. It can help a junior worker see more context and help a senior worker challenge old confidence. It can let one engine support many specialist businesses without rebuilding the same machinery every time.
It can't remove uncertainty.
The data can be incomplete. The representation can distort. The lens can hide a relation. The audience can change while being studied. The operator can misread a return. A beautiful visualization can make a weak model feel inevitable.
Visible correction addresses those risks.
Keep the observation. Keep the source. Keep the time. Keep the interpretation separate. Keep the confidence. Keep the decision. Keep what happened next. Let later evidence narrow, expire, or reverse the claim.
That sequence turns error into a map update instead of an embarrassment to hide.
The public work matters because it lets other people inspect the model. The private machinery matters because it lets the operator repeat the work, protect customer boundaries, and compound what was learned. The human stays responsible because consequential choices still need somebody who can understand the evidence, reject the output, change the policy, and reopen the trail later.
The evidence trail distinguishes sources from comparisons
The reading trail below came with the source article. Its papers, technical definitions and linked case records carry different authority. The case records used in this revision were read as documents; the external research links haven't been refreshed here. Read them as starting points for checking the scientific and product-specific claims, not as evidence of a new literature review.
For the surrounding operating system, start with Intelligence Engineering, then follow the Shape of Data: Provenance for clocks and source trails, State Machine Everything for commitment and reopening, and Research-Layer Metagraph Compiler for a concrete research-to-artifact implementation.
The active-sensing spine comes from biology. Chiu, Xian, and Moss observed paired bats changing parts of their sonar calls while navigating a difficult auditory scene. The study supports a narrow mechanism: a sensing system can change a later probe in response to conditions and returns. It doesn't study markets, customer research, or Hyperrelevance Cartography. Moving from adaptive sonar to adaptive research is an analogy grounded in a shared loop.
The shape-of-data section uses two instruments from topological data analysis. Cohen-Steiner, Edelsbrunner, and Harer establish a stability result for persistence diagrams under stated mathematical conditions. Singh, Mémoli, and Carlsson describe Mapper as a construction built from a filter function, overlapping cover, clustering inside preimages, and shared points. Those sources support the mechanics. They don't grant a business meaning to a cluster, hole, or persistent feature. Representation, lens, metric, sample, and interpretation remain choices.
The quantum comparison has a stricter fence. The Stanford Encyclopedia of Philosophy entry on quantum measurement explains why definite outcomes and state reduction belong to a specific physical and philosophical problem. This article borrows one picture, a question selecting one useful result from several possibilities, and it makes no claim that customer research obeys quantum mechanics.
The system section keeps its product boundary narrow. A complete operator journey has to connect profile inspection, launch, real execution state, native evidence, a human decision, and reopening. Source, an endpoint, or a screenshot can support one part of that chain. None substitutes for the whole journey. The public Observability Manifesto explains why those evidence classes stay separate.
Neo4j's property-graph documentation supports the storage vocabulary of nodes, relations, labels, types, and properties, and its Graph Data Science documentation supports analytical projections. Neither source defines the complete metagraph behind this work. That meaning comes from application contracts that add evidence, time, claims, authority, workflow, and operational purpose.
The provenance section uses W3C PROV because it gives public names to a simple chain: an entity is changed by an activity for which an agent is responsible. Derivation, generation, attribution, revision, alternate forms, and collections make a path inspectable. Provenance still doesn't certify truth. It records how a result arrived.
The attention section starts with Simon's information-scarcity argument, then separates delivery from human attention and causal effect. Google's impression-counting definition shows that a counted delivery event can occur when an ad begins to download. Google Ad Manager's viewability metrics add an area-and-time condition. Google Ads Conversion Lift uses treatment and control groups to estimate incrementality. Each instrument answers a different question.
The market-making section uses a literal financial baseline before transferring any language. The Bank for International Settlements describes market-making inventory, risk, capital, and changes in dealer behavior. Financial market makers may quote two sides, trade for their own account, and manage adverse selection. A content company doesn't become a financial market maker by holding drafts or matching ideas to audiences. The analogy supports inventory discipline, spread diagnosis, timing, and risk. The literal regulated functions stay on the trading side.
The multi-tenant section uses architecture guidance from Microsoft to ground shared components, tenant isolation, noisy-neighbor risk, and dedicated deployments. The business inference is local: a shared engine can support many specialist agencies if namespaces, access policy, provenance, contracts, and transfer rules keep customer worlds from bleeding together.
The product and portfolio examples are bounded explanations of the mechanism rather than publication of the engine's private recipes, customer material, scoring weights, or protected strategy. Readers can inspect related public proof in the Content Compiler Reference, AI Agent Systems in Production, Voice Fingerprint Deliverable, and Algorithmic Trading Pipelines.
This public trail stays attached because the argument asks readers to trust a living map. The trail shows which lines come from measurement, which come from a source, which are bounded comparisons, and which remain an inference waiting for a better return.
The next committed act should produce evidence for a correction
The gains begin with better work on one decision. They become credible only when one decision produces a return the system preserves.
A proposal can use the prospect's current language, answer the risk visible in the job post, connect proof to that risk, and arrive while the opportunity is still alive. A Field Note can connect a difficult idea to evidence, animation, and a useful next action. A campaign can learn from its misses because impressions, attention, traffic, conversion, and revenue remain connected without being collapsed.
The next gain is repeatability.
A voice compiler's repeatability target is to preserve a person's reasoning across articles, proposals, scripts and interfaces while exposing drift for an editor to inspect. A creative system's target is to keep a consistent visual world while making the explanation specific to each idea. Those targets need evaluation on actual outputs; the architecture alone doesn't establish them.
The third gain is specialization without rebuilding the factory.
Meme Shaman can use a shared ingest, provenance, evaluation, and production system while specializing in humor, timing, lore, and audience permission. Tesseract Markets can use the same operating discipline while keeping trading data, risk logic, and regulated boundaries separate. Constellation Media can give specialist agencies a common engine while every agency keeps its own sources, language, customers, and taste.
AndyDataGuy can publish the visible edge of the system. Each Field Note becomes a proof surface, a research instrument, a source of audience returns, and a new set of linked assets. The public piece teaches the mechanism. The private graph retains deeper recipes, customer material, correction history, and production leverage.
The fourth gain is scale with a human control plane.
An agent fleet can research more sources, test more lenses, and produce more candidate assets than one operator can hold in working memory. AgentOS can give that operator a place to inspect the profile, evidence, cost, state, receipt, and next action. SuperHarness can enforce the dispatch and lineage contracts beneath the interface. Independent evaluation can reject work before volume turns one weak assumption into a thousand weak artifacts.
Scale becomes propagation of reviewed judgment instead of propagation of output alone.
The final gain is a new way to allocate attention.
Most content systems optimize for production. A cartographic system can optimize for uncertainty reduced, qualified movement created, trust earned, and future decisions improved. It can hold production capacity as limited inventory, place difficult assets where they can create a return, and learn how different audiences price proof, novelty, humor, depth, and risk.
The result is an operating system that can see where attention is flowing, where meaning is scarce, where production is being wasted, and where a useful object can narrow the distance between what a community believes and what a business can prove. It doesn't create a literal exchange for human attention.
A family of specialist companies remains a business hypothesis. Its test is whether the shared engine reduces repeated work while each business retains useful local knowledge, customer boundaries and an inspectable return.
It also changes what mastery looks like. Mastery stops being a warehouse of final answers and becomes the ability to choose a useful probe, recognize a meaningful return, update the model, and move one radius farther without losing the path home. The tools increase reach, the graph increases memory, and the receipts increase accountability, while the world keeps the right to disagree.
A cartographer who accepts that disagreement can keep learning. A system that hides it can only grow more confident.
A trustworthy map stays unfinished. It earns trust by recording the corrections that made the next step safer.
The next act can stay bounded: preserve a set of recent opportunities with their selection rule, classify why each belongs in the archive, score a candidate with visible evidence, choose a supported package and record the expected buyer event before an authorized person sends it. Reopen the model when the return contradicts the score, stage clock, proof choice or selection reason.
That run will produce more than applications. It will show which parts of the map survive contact with a live market and which parts need to change.
The Alpha Is a Compiler follows the larger consequence: the advantage compounds when each committed run improves the engine that prepares the next one.
Keep the next probe and its return in the same record, so another operator can reopen the decision and see what changed.