
A premium menswear brand was sending cold traffic toward $400 to $500 jeans. My CRO work changed the entry offer to a keychain, introduced the jeans along the page, and brought them together in a bundle. The experiment concerned how a stranger became a customer, including what happened at checkout. A different hero image would've left that purchase decision intact.
The site already had an expensive, design-led rebuild. It looked elaborate, but cold-traffic conversion was under 1%. We moved to Shopify Plus, experimented with the checkout flow, simplified the choices and made the bundle easier to understand. The bundle flow eventually converted above 4% on cold traffic.
I handled CRO and site optimization, not the advertising, and the business was already generating revenue. The new flow also changed what someone was buying. A bundle conversion and a standalone jeans purchase aren't interchangeable measurements. I can describe the conversion improvement without treating all the brand's revenue as mine or claiming that a page change alone caused it.
Conversion rate optimization is the work of finding where people hesitate, get confused or lose trust, then testing changes to those points. The diagnosis can lead to clearer copy or fewer form fields. It can also lead to a different offer or a different order of commitments, as it did with the jeans.
A test backlog organized around page elements can miss that distinction. "Try another button color" names an edit. It leaves the reason for expecting a different buying decision unstated. A color change can be worth testing when there's evidence that the button is hard to see. The same edit proposed because somebody prefers orange has a different evidential basis.
I think of CRO as a laboratory. Research helps choose what to test, but it can't tell us in advance which version people will buy from. The useful discipline is choosing experiments that expose an assumption about the buyer and measuring what follows. That starts before either version of the page is built.
Diagnosis separates what people did from why they did it
A recording can show a visitor leaving the pricing section. The recording doesn't establish whether the price was too high, the offer was unclear, or the visitor was interrupted. A diagnosis becomes more useful when the team keeps that observed behavior separate from its explanation.
I start with the customer's problem independently of the thing we're selling. A request for a redesign can hide an unclear offer. A request for more traffic can hide a purchase path that doesn't work for the people already arriving. The evidence should help distinguish those possibilities before the team chooses an intervention.
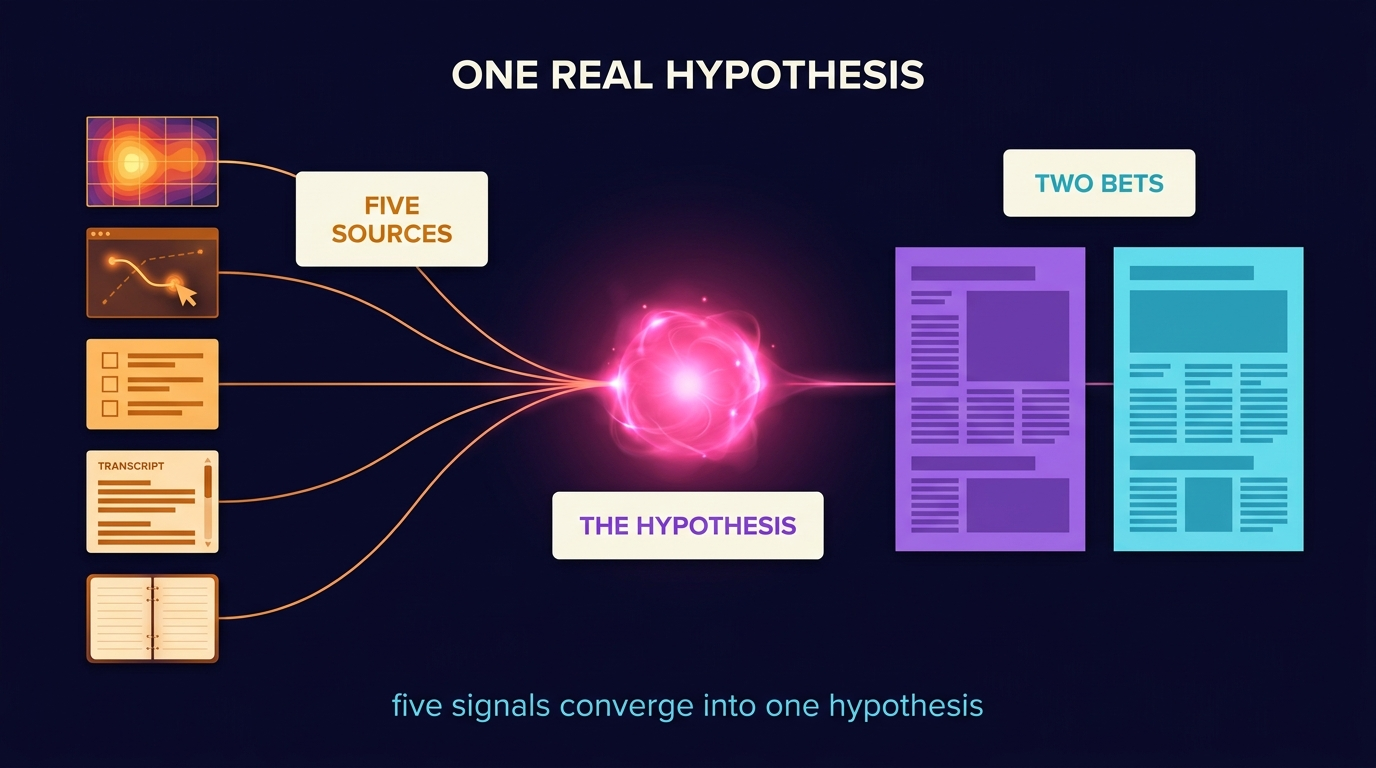
Five kinds of input help locate the friction. Each answers a different question, and each leaves something unresolved.
- Heatmaps and scroll maps show patterns in recorded clicks, pointer movement or page depth, depending on the tool. They help locate neglected sections and repeated interactions. They don't show where someone's eyes went or establish what the person believed.
- Session recordings show sequences. Repeated corrections in a form, attempts to click an inactive element or movement back and forth around pricing can identify a passage worth investigating. The recording supplies behavior; the motive still needs an explanation.
- Exit and post-purchase surveys invite people to describe the obstacle. "What almost stopped you from buying?" is useful for a purchaser, while an exit question needs to fit someone who hasn't bought. Answers reflect the people who respond, so keep their context alongside their words.
- Sales-call transcripts reveal questions that reached a salesperson. An objection repeated across calls may belong earlier on the page, although some questions depend on a buyer's circumstances and still need a conversation.
- A Lexicon of Pain collects the customer's own language from support tickets, reviews and relevant discussions. I use those phrases to understand how people describe a problem. A complaint about a competitor can suggest a question to investigate; it doesn't establish that the business's customers have the same complaint.
Low-traffic businesses need the same distinction between a clue and a conclusion. A handful of recordings can expose a broken form. Those recordings won't reliably establish how common a subtle preference is. Surveys also need respondents, and sales calls represent people who made it far enough to book one.
Combine the inputs where possible. A repeated form correction plus support messages about the same field gives a team a more specific place to look than an unexplained drop-off alone. Record the observation, the proposed explanation and the evidence that would count against that explanation. The test brief can then name a change aimed at something identifiable.
A test brief names what would change the decision
A useful hypothesis connects evidence to an intervention and a result the business can evaluate. It also leaves room to be wrong. A confident interpretation of a recording is still an interpretation.
Consider a hypothetical B2B pricing page. Prospects repeatedly ask sales whether the service fits their budget, and recordings show visitors returning to a pricing section that offers only a sales contact. The team suspects visitors can't tell whether a call is worth booking. That suspicion suggests a specific test: publish a pricing range and explain what changes the price.
The revised page should help suitable buyers decide whether to book. The business would judge the experiment by qualified opportunities per eligible visitor, with qualification defined before the test. Form submissions can remain a diagnostic measure. The team also needs to watch for lost suitable buyers, unsuitable enquiries and eventual sales, because an easier form or a reassuring price can change who enters the pipeline.
The team knows what it observed, what it thinks that means, what it proposes to change and what outcome would support the decision.
A control gives the comparison a reference point. Keeping the existing page as one arm can help answer whether the intervention improves on the current experience. Two newly built pages can answer which of those alternatives performs better, but that comparison alone won't establish that either beats the page they replaced. Each arm needs a reason to be there.
The brief should also name the audience eligible for the test, how people enter each version, how long outcomes need to mature and the rule for making a decision. A broken assignment or tracking process can make a persuasive result uninterpretable. Decide those details before inspecting which version appears to win.
An expected lift needs evidence of its own. The strength of a qualitative diagnosis doesn't establish the size of a percentage improvement. A business can state the smallest improvement worth acting on and ask whether its traffic can distinguish that improvement. Sometimes the proposed experiment can't support the decision.
The brief exposes that limit before the team spends its available traffic. It also makes the eventual result easier to interpret, especially when several parts of an offer change together.
The kitchen-gadget test compared different propositions
My first major CRO experience involved a general store selling kitchen gadgets. I studied Ezra Firestone's material, then built three substantially different landing pages for an avocado slicer. One took a harder sales approach, another appealed to people interested in cooking, and another emphasized visual appeal. We started with an even budget across separate campaigns and then changed spending as results came in.
The page I liked least won. It presented a simple package offer. My interpretation was that the offer appealed to people curious enough about cooking to buy the gadget, while the page aimed at committed cooking enthusiasts didn't work as I'd expected. That was an explanation of the result, with uncertainty still attached. I couldn't observe a buyer's motivation by looking at the sales total.
The winning concept generated roughly $600K in sales in under 60 days, as I remember it. I wouldn't narrow that to an exact duration. I also wouldn't treat that sales figure as profit or as the incremental revenue caused by a single design decision.
The pages differed in more than appearance, and the campaign budgets changed as we continued. The result told us which commercial approach to keep developing in that setup. It couldn't isolate the effect of one headline, prove that uglier pages sell better or supply a general rule about cooking audiences.
Those distinctions affect the next experiment. A business looking for an offer worth pursuing can learn from a broad comparison. A business trying to identify which part of an offer caused an improvement needs a narrower comparison that separates those changes. Both jobs are useful, but they produce different knowledge.
The kitchen-gadget result also depends on its setting. I described that market as forgiving, with room to test and a budget that allowed us to explore. A low-volume B2B business can't assume it has the same conditions. It can still ask a consequential question about its offer, then choose a comparison and a measure that fit the evidence it can collect.
A page that wins the initial purchase decision has answered only part of the business question. What happens to those buyers afterward determines how much the result is worth.
Follow the buyer beyond the page
A form submission is an intermediate event. A sales team still has to qualify the enquiry, hold the conversation and close the work. An ecommerce order can still be returned or cost more to fulfil than it contributes. The conversion rate needs a named action and a defined population before the team can decide what an improvement means.
A B2B pricing test might increase enquiries while reducing the proportion that qualify. Counting qualified opportunities per eligible visitor keeps both parts visible. An ecommerce test might increase order rate while changing order value, refunds or fulfilment costs. Keep the page-level measures for diagnosis, and evaluate the result against the business outcome declared in the brief.
My metal-art work showed why looking beneath an aggregate matters. I exported Facebook advertising data to CSV and organized it in Google Sheets, using macros and comparisons across creative, headlines, age, gender and device. Older women were an important buying group, and iPhone traffic was a useful signal in that advertising environment.
We changed the messaging toward family and home, then separated campaigns so we could manage those groups differently. The account grew from roughly $10K a month to roughly $150K a month over about 90 days. That was a broader campaign and offer change, not a randomized estimate of a page treatment's effect.
The meaning of the buyer evidence also needs care. Gift giving was part of the picture, and many people also bought for their own homes. Reducing the whole audience to grandmothers buying presents would leave useful buyers out of the explanation. The family and home themes mattered across those uses.
The historical device tactic has limits too. I later pointed out that changes in the information iPhone shares with Facebook meant that the old approach wouldn't transfer in the same way. The reusable method is to examine who buys and under what conditions, then test the explanation in the current environment. An old targeting detail doesn't become a permanent instruction.
An experiment needs tracking that connects the version a visitor received to the outcome being evaluated. Campaign tags help describe acquisition, but tags alone don't establish experiment assignment. Preserve the version or assignment identifier through the form, checkout and relevant CRM record, then connect it to qualification, sales or other declared outcomes.
Compare groups after equivalent follow-up. A cohort that has had longer to buy has a different opportunity to produce revenue. A missing identity link or an immature sales pipeline leaves part of the comparison's revenue outcome unknown. Record that uncertainty instead of substituting an immediate click for the outcome the business originally chose.
The remaining question is how much evidence the comparison needs before the team acts. That depends on the decision and the analysis method, as well as the quality of the diagnosis.
Choose a statistical method that fits the decision
A fixed-horizon A/B test plans its sample and decision rule before the result is known. The outcome can be an order, a qualified opportunity or a revenue measure with an appropriate analysis. The method needs to match the outcome. Calling a test "classic A/B" doesn't limit it to a binary conversion event.
Repeatedly checking an ordinary fixed-horizon significance calculation and stopping when it crosses a threshold changes the procedure. The team is making more opportunities to declare a result than the original decision rule allowed. A convenient dashboard doesn't resolve that mismatch.
Sequential testing handles planned opportunities to inspect and stop within the statistical procedure. The particular method sets the conditions under which that's valid. A team can't create a sequential test by watching an ordinary p-value more often, and an early apparent win still needs to satisfy the method's stopping rule. Delayed sales outcomes also have to arrive before they can inform the decision.
A multi-armed bandit tackles a different problem. It adjusts allocation as observations arrive, usually balancing further exploration against sending more traffic to variants that look promising. That can suit an ongoing allocation decision where the cost of exposing people to a weaker alternative matters. It also changes how the resulting data must be analysed.
A bandit doesn't create visitors or completed sales. Sparse feedback, changing audiences and delayed outcomes still constrain what it can learn. An uneven sample can result from the adaptive allocation itself, so a simple comparison that ignores how the algorithm assigned traffic may mislead. Choose an analysis designed for the allocation process, and decide whether the job is to allocate traffic or estimate an effect.
Bayesian analysis expresses uncertainty through a model that combines prior assumptions with the observed data. It can answer a decision-shaped question, such as how probable a useful improvement is under that model. The probability remains conditional on the model, its assumptions and the evidence. The result also needs a decision rule about what improvement matters and what risk the business accepts.
A persuasive customer story doesn't automatically justify a strong numerical prior. Qualitative evidence can help identify the mechanism worth testing while leaving the size of the effect unknown. A prior that dominates sparse data can make a result look decisive for reasons the visitors never supplied.
None of these approaches removes the need for reliable assignment, meaningful outcomes and enough evidence for the decision at stake. A low-traffic site may be better served by fixing an observed usability defect, interviewing suitable buyers or gathering more diagnostic evidence. Label that work according to what it establishes. An informed change can remain provisional until a comparison supports a stronger claim.
Start with the next test brief
Take the next proposed experiment and read its reason for existing. A brief that names only a page element leaves the buyer's obstacle unexplained. A brief that predicts a large lift without evidence leaves the business unable to judge whether the expectation is credible. Both gaps can be found before building the variant.
Use the brief to decide what work comes next. The sequence depends on what's missing, but the questions remain concrete.
- Write down the observed behavior and where it came from. Keep the record close enough that somebody else can inspect it. Separate a customer's actual words from the team's interpretation of them.
- Name the obstacle the change is supposed to address. Explain why the proposed version might alter that obstacle, and what result would make the team reconsider its explanation.
- Define the comparison and business outcome. State what counts as a qualified lead, purchase or other conversion, who belongs in the denominator and what follow-up is needed. Resolve missing tracking before calling the result a winner.
- Check whether the available evidence can support the decision. A traffic or outcome shortage may call for qualitative work, a more consequential intervention or a different question. It doesn't justify lowering the evidence requirement until the dashboard turns green.
- Record the result and the next decision together. Keep losses and inconclusive comparisons alongside wins, with their context. A future team needs to know what was changed and what remained unknown.
The backlog can then be prioritized around identifiable friction. A broken checkout deserves a different response from uncertainty about an offer. An observed defect may be repaired directly, while a disputed proposition needs a comparison. Existing ideas with sound evidence can stay. Unsupported ideas need diagnosis before they receive traffic.
The same process applies after a win. A new entry offer can bring in different customers, create a different order mix and move the next obstacle farther along the purchase path. Keep following those customers through the outcome the experiment was meant to improve.
The jeans experiment changed the commitment being asked of a stranger. That was a useful question because the team could change the offer and observe what followed. Choose the next test with the same care: identify the decision the buyer faces, explain the proposed change and make the business result inspectable.