
A build can pass while an LLM gives a worse answer. The application starts, the request completes, and the response has the fields the code expects. None of those checks establishes that the LLM's answer uses the right evidence or that an agent completed the user's task. Evaluation supplies that comparison. Observability supplies a record of what happened when the comparison fails.
My Python systems work starts with the data objects moving through a system. Pydantic makes their expected structure explicit. Tests exercise the behavior, and LogFire gives me structured records to investigate the sequence of events behind an outcome. A response can satisfy a data model and still contain the wrong fact, just as a workflow can finish without delivering what its user asked for.
I take the same approach to agent systems. The workflow, its failure modes and the operator's ability to investigate belong in the design. A better prompt can help, but an agent also retrieves documents, calls tools and passes information between steps. The quality of its final answer depends on that composition.
A useful evaluation therefore begins with a defined task and an expected result. It gives a team something to compare before a change reaches users. Production monitoring then shows where live behavior differs from the cases the team evaluated. Neither covers every possible input. Together, they let a team explain a release decision and investigate a failure without starting from a successful-looking response alone.
An evaluation case defines what a successful answer must do
A test runner needs more than a collection of questions. Each case needs a reason a result should pass or fail. My preference for starting with data models applies here: define what enters the system, what should come out, and what evidence supports that expectation before choosing a scoring tool.
Consider a document-answering system as a worked example. A user asks a question, the system retrieves passages, and a model writes an answer. An evaluation row should identify which source material supports the model's answer and what the system should do when that material doesn't contain enough evidence. A fluent guess and a supported answer need different outcomes in the test.
Make each case inspectable
A CSV can hold the cases. A more structured dataset works too. The fields need to make the decision inspectable:
- The input records the question or complete user task.
- The reference records the expected facts, supporting material or permitted outcome.
- The criterion states what must hold for the result to pass.
- The task type groups cases that exercise the same behavior.
- The failure consequence identifies which mistakes should block a release.
A structured response might need to parse as a Pydantic object and contain the correct field values. Schema validity checks the shape. Field assertions check the values the case defines. A prose answer needs criteria that allow different wording while preserving the required facts, source support and limits.
Keep the expected behavior specific enough that someone else could dispute a pass. An instruction to produce a good answer leaves that person guessing what good means. An instruction to answer from the supplied evidence, identify the supporting passage and acknowledge missing information gives them separate things to inspect.
Choose cases by the failures that matter
Choose cases for the decisions the system must handle. Include ordinary tasks, missing evidence and failure paths that matter to its users. A small set can establish an initial comparison, but its size alone says nothing about the behaviors it covers. The next question is whether the test reaches the whole workflow.
Test the model call and the workflow that uses it
A prompt can pass its own cases while the assembled system fails. The prompt test may supply the right context directly, even though production retrieval never finds that context. An agent may choose an appropriate tool and then pass its result incorrectly to the next step. Evaluation has to reach those connections.
Give each level a separate question
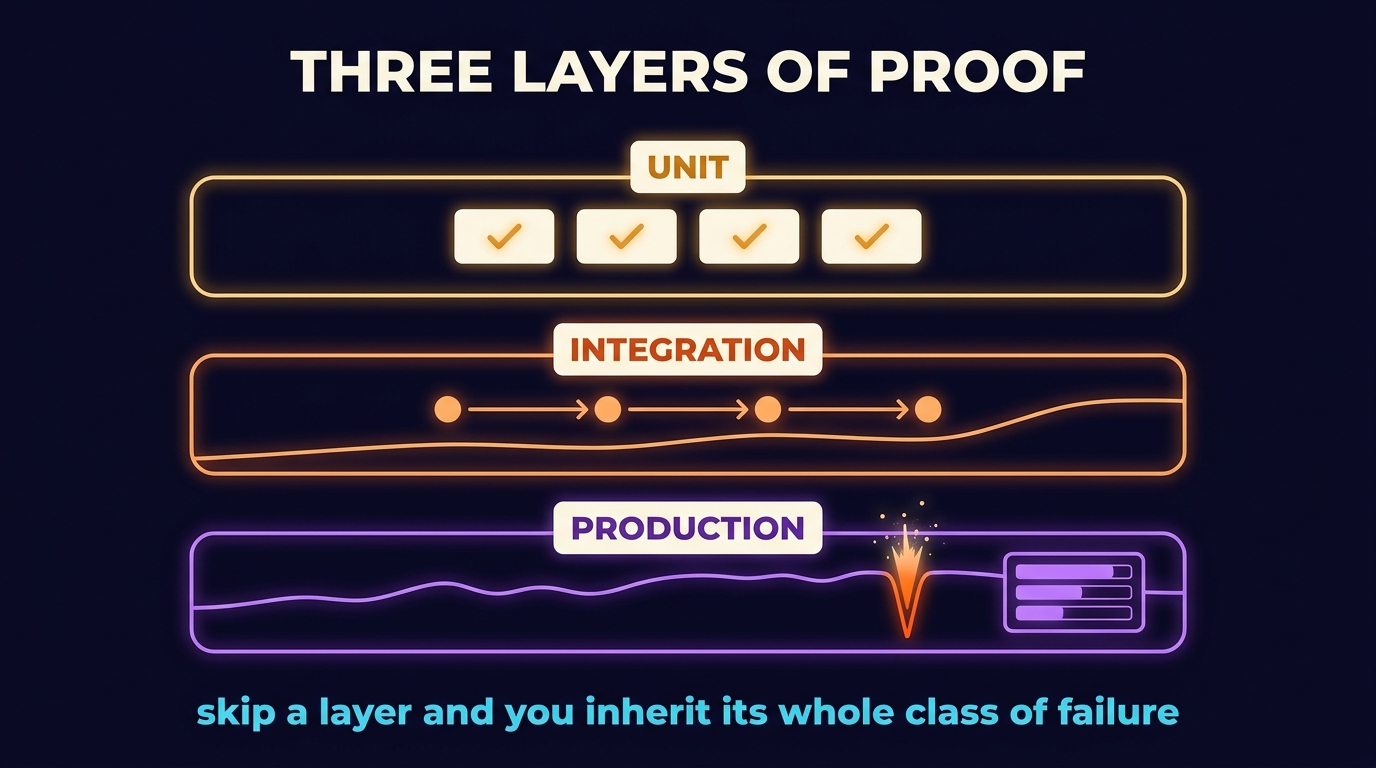
Unit evaluation, integration evaluation and production monitoring answer different questions. The same case definitions can connect them, but the evidence comes from different places.
| Level | Question it answers | Evidence to retain |
|---|---|---|
| Model call (unit) | Does this prompt handle the defined input? | Prompt version, input, output and assertion or rubric result |
| Complete workflow (integration) | Does the composition complete the user's task? | Final result plus retrieval and tool-step traces |
| Live operation (production) | Does behavior on real traffic differ from the evaluated baseline? | Versioned runtime signals, affected tasks and user feedback |
Trace the steps behind a failed task
My local RAG work started from Archon and changed how different document types were chunked and retrieved. A document-answering system includes decisions before generation: how the source is divided, which passages are returned, and what the model receives. A final-answer score alone can't tell an engineer which of those decisions needs attention.
An integration case should run the task through retrieval and any tools, then check the final result. Retain per-step traces so a failure can be followed back through the composition. Check whether the supporting passage was retrieved, whether it reached the model, and whether the final answer used it correctly. Those are distinct possible failures, with different corrections.
LogFire is the structured-observability tool I use in my Python stack. The requirement is a record an engineer can query and follow across the operation. Attach the case or task identifier and the versions needed to connect that record to a test run. Limit captured content to what the investigation needs, with access and retention controls for sensitive inputs and tool results.
A trace makes the sequence inspectable. The evaluation criterion still decides whether the outcome was acceptable.
Review changed cases before releasing a new prompt
A prompt change belongs in the same review process as the code that calls it. Keep a versioned prompt artifact, whether that's a template such as Jinja or another format the team can review. Connect the prompt version to the application, model configuration and reference data used in the evaluation. A pull request can then trigger a comparison against the current release.
Compare the failures as well as the total
Run the candidate and baseline against the same defined cases. Retain the outputs and the reasons for each pass or failure. A total pass rate helps summarize the comparison, but a team needs to see which task types improved and which regressed before accepting it.
A new prompt can perform better overall while becoming worse at a consequential task. A critical failure should block the change under the team's release policy. A tolerable tradeoff needs an owner who records what got worse, why the improvement is worth it, and what users will experience. Make that decision visible in the review rather than letting an average stand in for it.
The cases also need review. An expected answer can become obsolete when reference material changes. Record the source change and the reason for updating the case, so a regression isn't hidden by quietly changing the test to match the candidate.
Separate cached replay from fresh model calls
Begin with a set whose cost the team can sustain on each change. Expand it where coverage is missing or a reviewed production failure exposes a new requirement. The useful size follows the task and its consequences. A fixed row count can't establish adequate coverage.
Caching can avoid paying again for an output already obtained under recorded conditions. Label that result as replayed. A cached response says what happened on the recorded call. It doesn't show how a fresh call behaves. Keep prompt, model, settings and relevant source versions with the result, and run fresh calls when the decision concerns variation between runs.
Save the comparison and the version the team can return to if the release fails in production. Reverting a prompt may be insufficient when retrieval data or a tool changed too. The recovery record needs to identify those dependencies before the team needs it.
Investigate drift by task type
Live traffic can diverge from a fixed evaluation set. New users bring different questions, a reference corpus acquires different material, and a model or its serving configuration may change. Record what the system used so an investigation can distinguish those possibilities instead of assigning every deterioration to the prompt.
Track signals that help locate a change
For model calls, useful signals include input and output length, latency, schema validity, citation count and refusal rate. These describe behavior. They need a task context: a shorter answer might omit necessary detail or simply stop repeating itself. A citation count can increase while the citations remain irrelevant.
For retrieval, use a held-out set of queries with known relevant material. Run these sentinel queries on a defined schedule and check whether the retrieved results include that material among the returned passages. That's the question behind top-K recall: the proportion of known relevant material that appears in the first K results. Retrieval latency and reranking scores add diagnostic context, but a higher score alone doesn't establish a better answer.
For agents, track tool calls, retries, session length and success by task type. Keep the definition of success beside the metric. A session ending and a requested action completing are different events. An increase in retries can help locate task types or tool steps that need investigation.
Use user outcomes to interpret weak signals
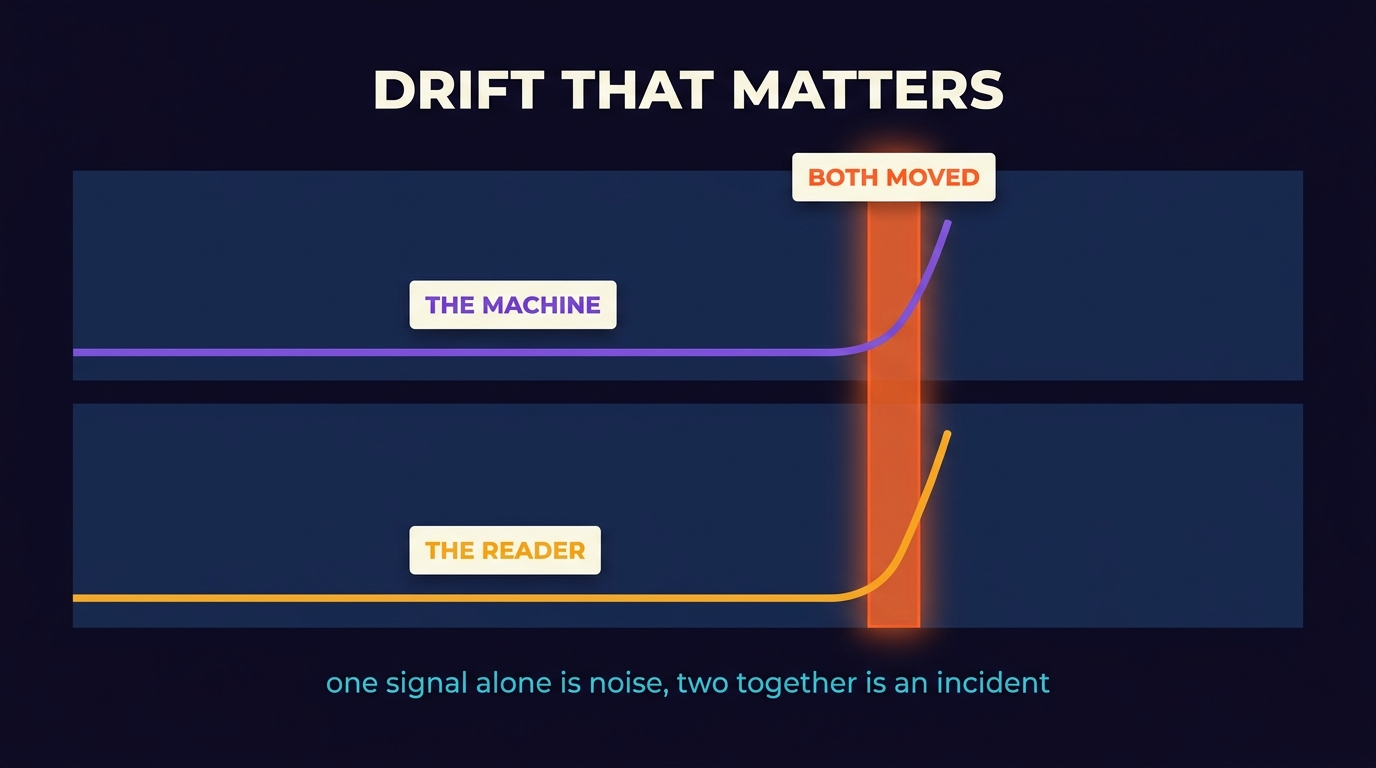
Compare technical changes with outcomes such as negative feedback, follow-up questions, abandonment or citation clicks. Look at the affected task types and the same observation window. A technical change alongside a worsening user outcome gives the engineer a more specific investigation than either aggregate alone.
Those outcomes remain proxies. A follow-up can be a correction or a useful continuation. A citation click can be curiosity or an attempt to check a doubtful answer. Review examples before deciding what movement means. Missing negative feedback leaves the effect of a technical change unverified.
Set alert rules by consequence. A failed schema contract or an unsafe tool action warrants action under its own failure policy. Waiting for dissatisfaction to appear would add no useful evidence. A shift in output length may call for a sample review before an alert. Record the expected response and its owner so weak signals don't generate an unmanageable queue of notifications.
When an investigation finds a real task failure, preserve the relevant trace and turn the reviewed case into an evaluation.
Calibrate a model judge against human-reviewed cases
Exact assertions work when the case has an exact answer. Generative output permits many acceptable answers, so a model judge can score the result against a rubric. Give it the task, candidate output, reference evidence where needed, and criteria that describe separate dimensions of quality. Retain its per-dimension scores and explanations so someone can inspect the reason for a pass.
Establish what agreement means for this task
The judge needs its own evaluation. Assemble examples that humans have reviewed against the same rubric, then hold some apart from the examples used to refine the judge. Compare the judge's decisions with those human decisions. Choose an acceptable level of disagreement according to the consequence of a wrong pass.
Plain match rate records how often the decisions agree. Cohen's kappa is another agreement measure, adjusting for agreement expected by chance. Either can help describe calibration, but the disagreements still need reading. A judge that agrees on ordinary answers and misses the consequential failures would be unsuitable even if its aggregate looks reassuring.
Low agreement calls for diagnosis. The rubric may combine dimensions that need separate scores, examples may leave a boundary unclear, human reviewers may disagree, or the judge may be unsuitable for the task. Resolve the disagreement before using that score to revise the generator. Otherwise, the team could change an acceptable answer to satisfy a scoring failure.
Treat judge choice as part of the comparison
A judge from a different model family is worth considering to reduce dependence on the generator's own preferences. Family choice alone can't establish independence or accuracy. Compare the candidate judge against the held-out human decisions, including cases where style might distract from a factual or task failure.
Version the judge prompt, rubric, model and relevant settings alongside the generated outputs. A changed score needs an explanation of what changed in the generated answer and what changed in the grader. Recalibrate when the scoring setup or the task changes.
Keep the deterministic checks where they apply. A judge's favorable prose assessment doesn't waive a failed schema or an incorrect required value. Human review remains necessary for ambiguous cases and consequential disagreements. The judge helps distribute review effort. Its score is evidence for the release decision the team owns.
A release decision needs cases, traces and a recovery owner
A technical lead can ask a team to walk through one changed task from the latest release. Show the input, expected behavior, baseline result, candidate result and reason for accepting the difference. Then connect that comparison to the versions in production and the runtime record that would help investigate a failure.
Ask how the evaluation set was chosen and what it leaves uncovered. Ask how judge decisions were calibrated, which failures block a release, and who accepts a tradeoff. A dashboard becomes useful when the team can follow an adverse signal to affected tasks, inspect the evidence and decide what to change.
Recovery needs the same specificity. Name who responds, which version or dependency can be restored, and what evidence will establish that the correction addressed the failure. A runbook should let another engineer perform that work without relying on the person who wrote the prompt being available. My approach to technical documentation treats that ability to operate the system as part of delivery.
A throwaway experiment for learning can stop short of this operating setup. A system that performs work people rely on needs acceptance conditions and a way to respond when they fail. The amount of instrumentation should follow that job and its consequences.
The next prompt change gives the team a concrete place to start. Record the expected behavior, compare the changed cases, and keep the production evidence connected to the result. When an answer gets worse despite a passing build, the engineer should be able to reopen the failing task and investigate what changed.