
A correction to a paragraph can make a headline wrong. An editor changes a claim, accepts the new paragraph, and still has to find every summary or excerpt that used the old claim. A useful content system needs to know what depends on that edit. It also needs to leave accepted text alone when the edit has nothing to do with it.
A workflow that sends the entire draft to a model for every revision makes both jobs harder. The model can rewrite passages the editor already approved, change a list into prose, or alter the qualification attached to a result. The editor then has to read the replacement as a new document. Even a better paragraph can come with extra work elsewhere.
My content compiler work starts by giving those parts an identity. A claim, its evidence and the paragraph that expresses it become records the system can address separately. The finished prose comes from those records, so a revision can target the affected part and preserve the rest.
The compiler comparison helps explain the separation. A compiler works on an internal representation before producing an output. For content, that means keeping the intended meaning and its sources available while the wording changes. The stored representation gives the system something more specific to work on than a request to improve a draft.
That still leaves a writing problem. A paragraph can be correct on its own and contradict the paragraph below it. Choosing a smaller unit of generation creates room for closer editing. The assembled document still needs a reader.
My content compiler started as an experiment in longer writing
I described the problem in my portfolio walkthrough after experiments with programmatic writing systems. A model could produce a short passage I liked, yet asking it for a longer piece brought back the generic phrasing and loss of continuity I was trying to remove. My ambition was writing with sustained nuance and structure. Getting an acceptable paragraph was a much smaller achievement.
The browser gave me a useful way to think about the work. A reader sees a page, but the browser represents that page as a tree of elements. Software can change an element without asking someone to recreate the entire page. The document has parts that remain identifiable as the display changes.
Compiler design suggested another part of the approach. LLVM's intermediate representation inspired me to separate the internal document from its eventual output. I could work on a claim or a paragraph, apply a particular editing operation, then assemble the result. A request to change the tone would have somewhere specific to go.
The project record describes a Python system with atomic content nodes stored in SQL and backends for Markdown, PDF and HTML. It describes generating and revising individual nodes, with passes for style and logic before assembly. That's the documented basis for this architecture.
I called the system a working MVP in that walkthrough. I also said it was in its infancy. Personalization across cultures, dialects and different kinds of long-form work was the direction I wanted to take it. Those ambitions need their own evidence before they become claims about what a system delivers.
An internal document can carry the information an editor needs to make a controlled change. The first design decision is what information belongs there.
Store the claim separately from the paragraph that expresses it
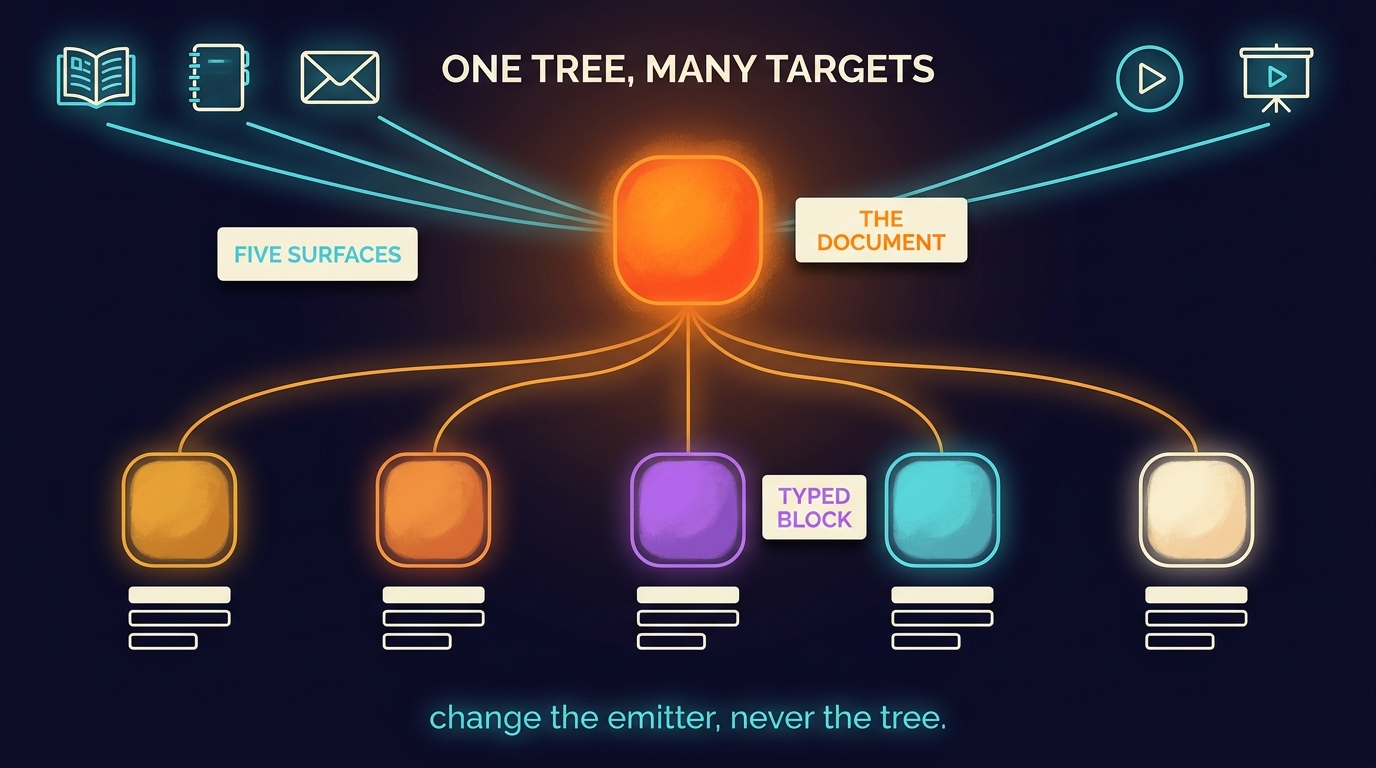
An intermediate representation, or IR, is the structured document the compiler works on. A Document record can hold the audience, tone, length budget and ordered content blocks. Those choices apply across the piece. A block holds the information needed for a particular job, such as introducing an argument, presenting evidence or asking the reader to act.
Pydantic fits this kind of Python design because it lets you describe and validate the fields each record requires. An evidence block can require a source reference and a quoted passage. A narrative block can carry its topic, claim, supporting references and intended length. A list block needs ordered or unordered items; a figure block needs its media reference and the point it explains. Each kind has a different contract.
Keep the source material available during revision
The distinction between an evidence record and a prose record matters when the wording changes. An editor needs to inspect the source behind a sentence and see whether a qualification disappeared. Storing only the generated paragraph loses that separation.
A minimal design could distinguish the following records. This is an illustrative contract, not an export from the working system.
| Record | Information to retain | What uses it |
|---|---|---|
| Document | Audience, tone, length budget, block order | Structure and document-wide review |
| Claim | Proposition, scope, conditions, evidence references | Paragraphs and summaries that repeat the claim |
| Evidence | Source location, exact supporting span | Citation checks and editorial inspection |
| Narrative block | Stable identifier, claim reference, context, rendered prose | The article and its output formats |
Rendered prose is a result of working on those fields. An editor who changes a claim should update both its record and the sentence. Otherwise the next generation can restore the claim they just corrected.
Record which parts depend on the claim
A headline or summary that repeats a claim needs a reference to that claim. The reference tells the revision system which outputs to reconsider when the claim changes. The order of paragraphs also matters when a passage relies on an explanation that came earlier.
These relationships set the boundary of a local edit. A spelling correction can leave the argument alone. A narrower claim can require a new paragraph, a revised summary and another read of the conclusion. The system needs enough structure to tell those changes apart.
Give each editing pass a specific job
A pass takes the structured document and performs a defined operation on it. Separating those operations lets an editor see why a block changed. It also lets the team improve a citation check without changing how the system writes an opening paragraph.
The original architecture divides the work into structure, voice, citation and rendering. Structure checks the sequence against the audience and the argument. Rendering turns structured content into prose. Voice work edits the phrasing against the writing standard. Citation work checks that evidence references resolve and support the claims attached to them.
Those responsibilities need an explicit order. Settle the argument and evidence before polishing its wording. Generate the prose, edit it, then check what the final wording asserts. A citation attached before a rewrite may support the old sentence and fail to support its replacement.
Make a rejected block inspectable
A pass should return either an accepted change or a reason it can't proceed. A missing claim and an inaccessible source are different failures. An operator needs the affected block's identifier, the pass that rejected it and the input that needs attention. Replacing missing evidence with plausible prose would conceal the failure.
The same record should show the before and after when a pass changes text. Logfire is one option for collecting that history. A durable compile log is the requirement. In my general Python work, structured logging helps make an operation inspectable. A content pipeline needs that visibility at the level where an editor can act on it.
A successful lookup proves that a citation resolves. Establishing that the passage supports a claim requires reading the passage. A typed field can require evidence to be present, but it can't make the evidence true.
Keep generation separate from repeatable checks
Keep transformations of the document separate from database writes and logging. A transformation can return a changed IR without altering external state. Some operations can be deterministic. A check for a missing required field should give the same answer for the same record. A model asked to improve a paragraph can return different wording, and another run may change it again. An idempotent operation leaves its result unchanged when repeated. A pass described as idempotent needs evidence that it behaves that way.
Define what each pass may change and preserve its accepted output. Then read the assembled document for repeated explanations, broken transitions and contradictions between blocks. Local edits give the reader a better article only when the pieces still work together.
Reuse a block only while its inputs still match
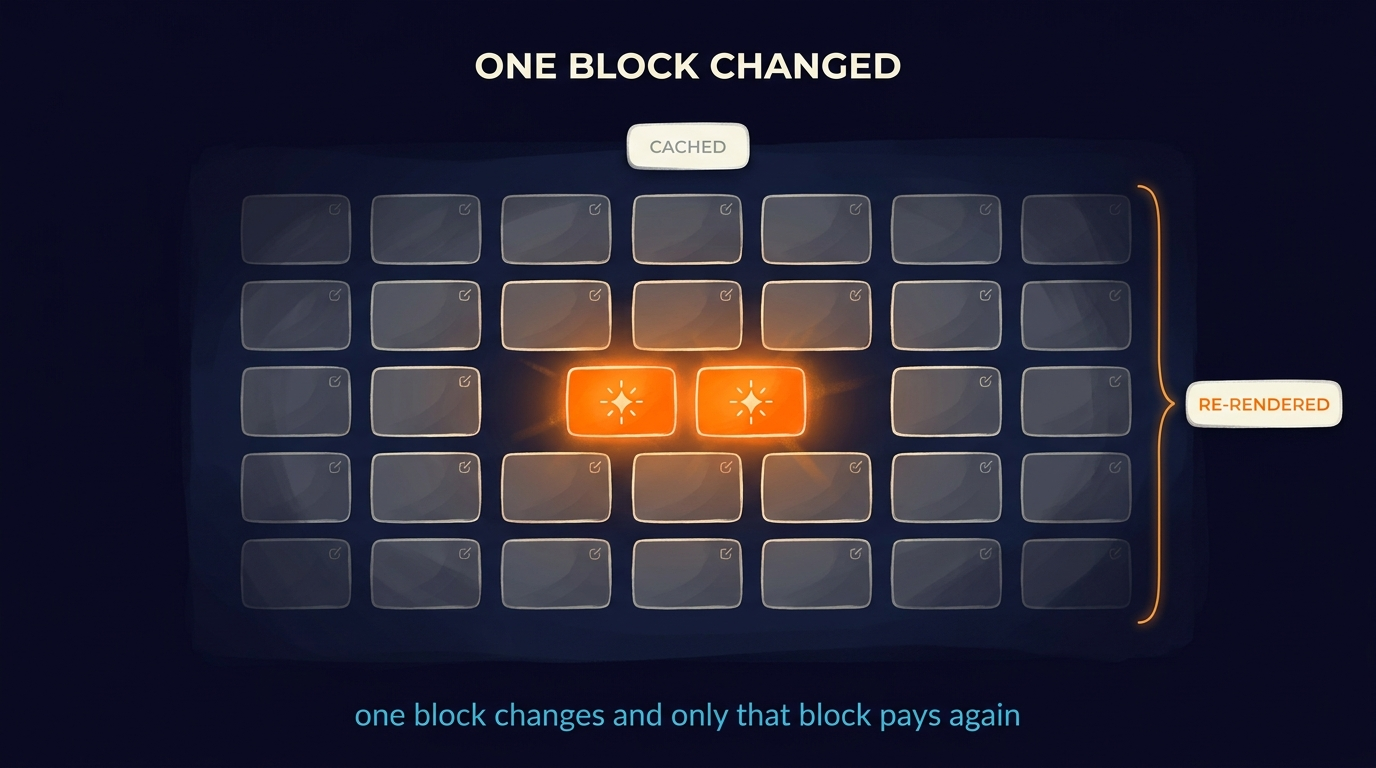
Caching preserves work the editor has already accepted. The original design proposes a cache key made from a block's structured fields, model version and prompt version. When those inputs match a stored result, the system can reuse that result instead of asking the model to write it again.
The difficult part is deciding what counts as an input. A paragraph can depend on a source passage, a style rule, the audience and an explanation in another block. A cache that checks only the paragraph's topic and claim can return text that no longer fits the document.
Include the dependencies the wording used
A spelling correction can leave other blocks' inputs unchanged. A change to the evidence behind a claim has wider consequences. Any block that uses that evidence needs reconsideration, along with summaries that repeat the claim. A document-wide audience change may affect nearly all the prose even though each block still has the same identifier.
A useful cache design therefore records the versions of the sources and document instructions used to produce each result. Include the model and prompt versions too. Reuse becomes a decision about matching inputs, rather than a guess that a paragraph probably hasn't changed.
An expiry time can force a later refresh, but it doesn't identify an intervening source correction. Dependency changes need their own invalidation rule. The editor should be able to inspect why a stored block was reused or rebuilt.
Read the misses as well as the hits
Hit counts show how often stored results were reused. Frequent regeneration calls for an explanation. It might reflect changing instructions, expired entries, prompt revisions or a dependency that legitimately changes. The count alone can't tell you that a block's contract is wrong.
A planned model or prompt change can invalidate affected results before the next publication. Regenerate those results deliberately, compare them with the accepted versions and retain a way to restore the earlier output. Warming the cache is an operational choice with its own cost and editorial consequences.
The compiler analogy holds here because a change can trigger a selective rebuild. The design can miss a dependency between ideas. Dependencies that matter to a human reader must be represented or caught in review. A hash can compare only the inputs recorded in the cache key.
Different outputs can share the same supported claim
A structured document can produce different file formats without requiring the editor to maintain a separate source for each. My compiler case record names Markdown, PDF and HTML backends. Those are different ways to deliver the document while retaining its content records.
Adapting an article into an email or a video script introduces another decision. The new format changes how much context a reader gets and how the argument unfolds. A formatter can convert markup; an adaptation has to decide what to keep and how to explain it.
A claim record gives that adaptation a stable reference. Its supporting evidence, scope and conditions can travel with it even when the wording changes. A shorter output can select fewer claims and still preserve what makes each selected claim true. Dropping a condition because it doesn't fit turns a concise version into a different assertion.
The same principle applies to personalization. A change of vocabulary or cultural reference can help a reader understand an idea. It can also introduce a comparison that doesn't fit or imply an experience the author never had. The adaptation needs review for the audience receiving it, alongside checks against the source material.
Keep the claim and its evidence in one place. The work that remains is choosing and editing each expression of that claim. A shared representation can make a correction traceable across outputs, but every new channel still brings editorial decisions and operating costs.
That distinction matters when deciding whether to build. Adding more destinations increases the opportunity to reuse structured material. It also increases the number of results someone has to inspect.
Build around the revision work you can avoid
A small operation publishing occasional pieces in a single format may do well with ordinary documents, a good prompt and careful editing. The compiler adds schemas, dependency tracking, cache invalidation and pass maintenance. Those have to solve a problem the operation already has.
I start by identifying the problem independently of the tool. I define the future the person needs, then work out what has to change to reach it. For content operations, the problem might be repeated review of passages nobody intended to change. The desired result is a revision an editor can inspect without losing control of accepted material.
Measure that work before making a savings claim. Compare full-draft regeneration with selective revision on the same documents and the same requested edits. Record the input and output tokens, which blocks changed, which cached results were reused and what the editor had to correct afterward. Keep local wording changes separate from changes to evidence, audience or argument, because they invalidate different amounts of work.
A block's share of the document's words doesn't establish its share of the bill. Its generation may need surrounding context and source passages. Checks, retries and adaptations consume resources too. Editorial effort belongs in the comparison alongside model usage.
The case for a compiler strengthens when the same supported material needs frequent revision or appears in several outputs. The result still depends on how much work can be reused and how much dependency tracking costs. A fixed volume threshold or a promised savings percentage would hide that decision.
Start with a representative revision and an inspectable result. Expand the machinery when the recorded work gives you a reason to.
Ask to see a claim change and its consequences
A demonstration should let an editor change a claim in a real document and inspect the result. Start with the source passage and the wording it supports. Narrow the claim, then follow the revision through the stored record, the paragraph and any summary that repeats it.
The useful result is a visible explanation of what changed and why. Unaffected passages should retain their accepted text. Dependent passages should be reconsidered. A rejected revision should identify the missing evidence or broken contract so the editor can decide what to do next. The operator should also be able to reopen the accepted version and compare it with the replacement.
Then read the complete output. Preserved paragraphs can become confusing after an explanation moves, and a corrected summary can still repeat a point the introduction already made. A compile log helps locate the change. Editorial judgment determines whether the document makes sense.
The demonstration should expose its cost alongside its result. Compare what the system regenerated with what it reused, and include the checks and corrections needed to reach the accepted version. A typed schema explains the intended controls. The revision shows whether those controls do useful work.
My original compiler ambition extended into much larger forms of writing. The bounded question is already demanding enough: can an editor correct that paragraph without losing its evidence, leaving its headline wrong or having to approve every unrelated paragraph again? A compiler earns its place by making that correction inspectable and preserving the accepted text it doesn't affect.