
A document-answering system can cite a real passage and still give the wrong answer. Consider a contract set: a schedule names a liability cap, but a side letter changes it. An answer that quotes the schedule has found relevant words. It has missed the document that decides whether those words apply.
That's an illustration, not a client incident. It exposes a problem a citation badge alone can't solve. The reader needs the applicable evidence, its context and a way to inspect how that answer used it.
Retrieval-augmented generation, or RAG, gives a language model passages to use when answering a question. A retrieval system searches a corpus, selects material and passes it to the model. The model then writes an answer from that context and its instructions. Each step can fail. Ingestion can separate an exception from its rule. Search can miss a defined term. Ranking can bury the useful passage. Generation can misread evidence that was present all along.
I start with that evidence path when assessing a RAG system. Which passages reached the model? Which version did they come from? Does the cited text support the particular claim being made? Changing the model may help a generation failure, but it won't restore a missing side letter to the material the model received.
A useful knowledge engine makes those questions answerable. The work begins with the documents going into it.
My corpus needed different treatment for different documents
My local retrieval project started with material I wanted agents to use: my own writing, PDF textbooks and YouTube transcripts and comments. In the portfolio account of that build, I described a knowledge base containing more than five million words across hundreds of mostly Markdown files. That was the corpus described in that account, not a live count of what's indexed today.
The source formats were the engineering problem. An essay develops an argument across paragraphs. A standard operating procedure gives an instruction under a heading. A transcript includes interruptions and spoken references, and a comment thread can contain disagreement between people who are answering different questions. Cutting each into the same fixed windows discards distinctions the answering task may need.
I built on the open-source Archon platform and changed its chunking pipelines. The documented approach used cluster-semantic chunking tuned to the document types, task-typed Gemini embeddings and a locally run Model Context Protocol interface so agents could query the material as a tool. The historical record names Gemini Embedding 001. That identifies the build; it isn't a recommendation to select that model for a new system.
I reported more useful access to passages from the corpus for content creation and agent work. My portfolio account doesn't provide a controlled citation-accuracy comparison. The broader architecture described in this article is a design recommendation. A useful personal system and a measured production claim require different evidence.
Choose passages that preserve what a reader needs to understand them. Then test whether the retrieval task benefits from those choices. A chunking method earns its place through the questions it helps answer.
Chunks need their document context and version
A chunk is a passage selected for retrieval. Its boundary determines what evidence survives the trip from a document to an answer. A sentence containing an instruction may depend on a heading that limits its scope, or on a definition several sections earlier. A chunker that preserves the sentence and drops that context has changed what the passage appears to say.
Preserve the relationships that decide an answer
I'd keep a document identifier, a path through its sections and source offsets alongside each chunk. The offsets identify the passage within a particular source version. A checksum helps detect a change. The section path lets the application recover surrounding context without asking the model to guess where a passage belongs.
The contract illustration needs more than a larger chunk. A master agreement, schedule, exhibit and side letter may be separate documents. The retrieval system needs a way to find their relevant relationships and decide which material applies to the question. That might mean stored links, a structured lookup or graph traversal. Increasing a token window alone doesn't establish an override relationship.
A document-type-specific chunker can respect headings, paragraphs and source boundaries, but it still needs inspection. A boundary that works for an essay may separate a procedure from its warning. Sample the chunks against the questions people will ask, including the exceptions.
Keep the version that supported each answer
Freshness is a second part of context. An index needs a repeatable way to ingest new documents, update changed ones and stop returning superseded material as current evidence. Historical questions may still need historical versions, so deleting every old passage would create another failure.
I'd key updates to document identity and version, reprocess affected chunks and preserve the relationship between an old answer and the source it actually used. An embedding-model change also needs a migration or backfill plan for the affected index. The team must know which representation each candidate uses before comparing retrieval results.
An old answer can remain inspectable while being marked out of date. Reopening it should show the version originally cited and make any newer resolution explicit. Silently substituting today's paragraph would conceal the evidence behind yesterday's answer.
Different questions need different retrieval routes
A question about an exact defined term and a question describing a concept in unfamiliar words ask search to do different jobs. A retrieval design should account for both where the corpus requires them. Corpus size alone doesn't tell you which method will fail.
Match terms, meaning and explicit relationships
Lexical search uses the words in the query. BM25 is a lexical ranking method that can help retrieve a passage containing a defined term such as "Permitted Transferee." It gives the system a route to the wording the user supplied. Exact phrasing, identifiers and names deserve their own evaluation questions.
Dense vector search uses embeddings, numerical representations used to compare semantic similarity. It can retrieve a passage whose wording differs from the question. A user describing a restriction in ordinary language may need that route even though they don't know the contract's term for it. Similarity supplies candidates; it doesn't determine which clause governs.
An explicit relationship can supply the missing context. Graph traversal follows stored connections between records, such as a schedule's link to an agreement or an amendment's link to the clause it changes. A graph can help when those connections decide how a question should be answered. Its usefulness depends on whether the relationships were captured correctly and whether the query follows the relevant ones.
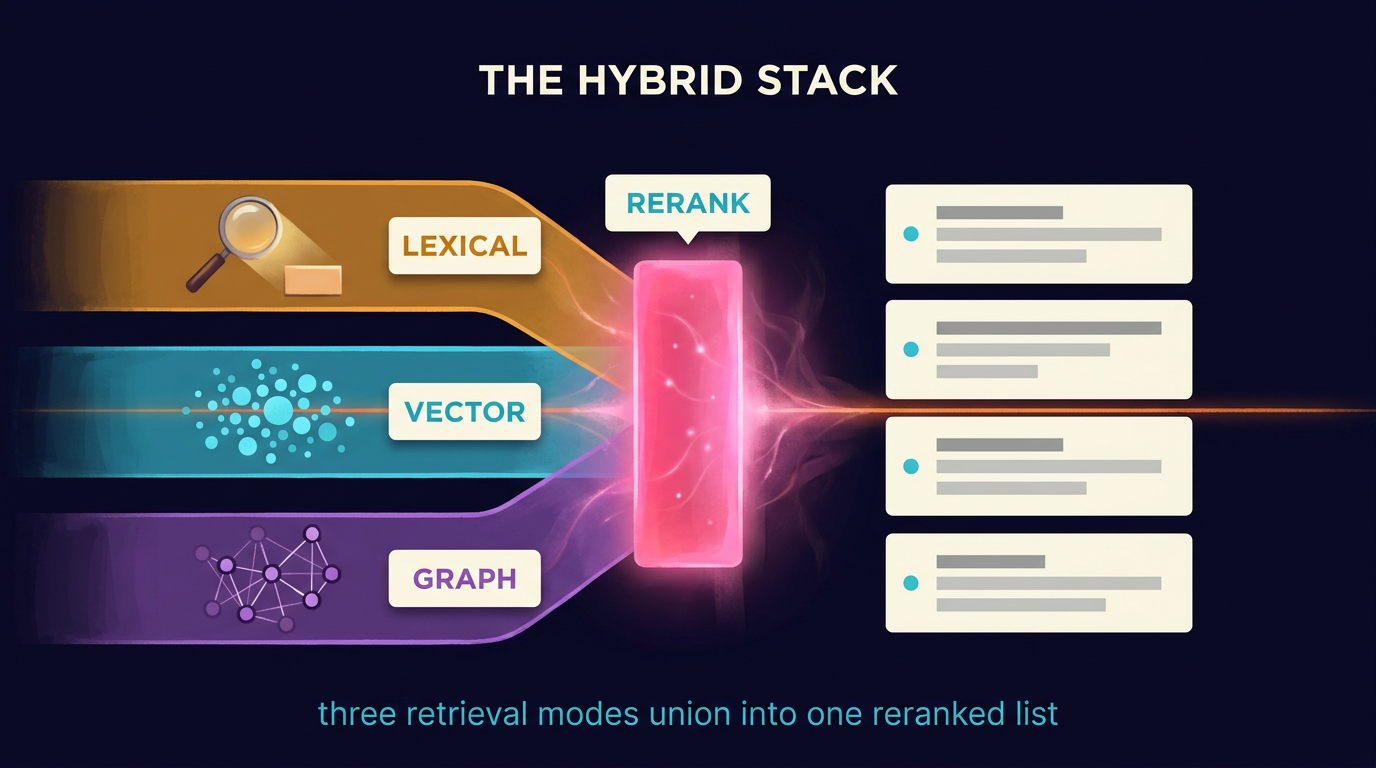
These methods can sit behind one retrieval interface. Their candidate sets can overlap, so the interface needs a defined way to combine and deduplicate them while retaining where each candidate came from. Search scores from different methods shouldn't be treated as interchangeable without a justified combining method.
Rank candidates against the question
A reranker reassesses retrieved candidates against the query and orders the material that will reach the model. A cross-encoder, for example, evaluates a query together with a candidate passage. The team can compare its selected context with the initial retrieval order and measure whether the additional stage helps enough to justify its latency and operating cost.
The three-route diagram describes one possible hybrid design. A corpus may need fewer routes. I'd add a component to address an observed failure, then test the affected questions. A graph database or a reranker in the architecture drawing doesn't establish that the model received the right evidence for its answer.
A citation needs a record the application can resolve
A footnote number is the visible end of a citation. The application also needs to know which claim it accompanies and which passage supports it. Storing only the finished answer text makes that relationship harder to inspect when a user disputes a sentence.
Store the source relationship before rendering it
I'd represent citations as validated records rather than leave their meaning inside generated strings. A citation record can identify an answer claim, one or more chunks, the source document and its version. The chunk record supplies its section path, span and checksum. A persistent citation identifier lets the application retrieve the same relationship later.
Pydantic can validate that shape in a Python system. It can't establish that a cited paragraph supports an answer. The application still has to resolve the references, and someone or something must assess the relationship between the claim and the evidence. A perfectly valid record can point to the wrong passage.
The model generating an answer should use references to the supplied context. The application should reject unresolved identifiers instead of rendering them as credible-looking citations. A model-generated document title or page number needs the same treatment.
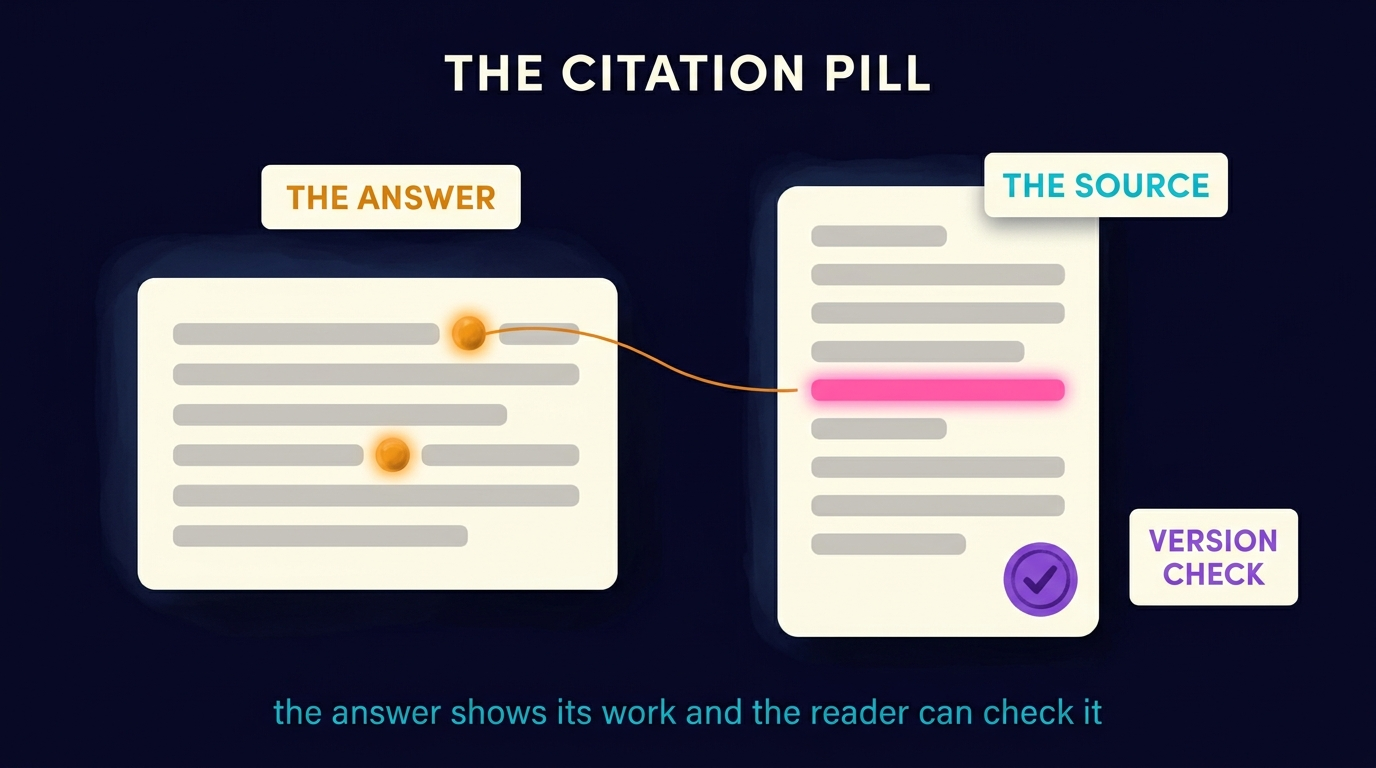
Let the reader inspect the cited version
A clickable citation should open the passage in context, show its source and version, and identify the text used in its associated answer. The reader can then check whether the passage states the claim, supplies only part of it or contradicts it. A badge that opens a document without locating the supporting text leaves that work unfinished.
A version mismatch needs a visible state. The application can show the historical source and offer a new lookup against current material. The result of that lookup should remain distinguishable from the original citation. Access checks belong on the source-opening path too; a citation link must respect the reader's permissions.
The contract illustration now has a concrete diagnostic. Does the generated answer cite the cap alone, or also the material establishing whether it applies? The records let the team locate the evidence used. Evaluation has to decide whether that answer used enough of it.
Measure retrieval and answer support separately
A test question needs an expected result grounded in the corpus. A domain expert can identify the passages required for an answer, the conditions that change it and the questions the corpus can't answer. Those judgments give the team something to compare with the system's output.
Check whether the evidence reached the model
Build a held-out set that reflects the work. Include exact terms and paraphrases. Include questions that require related documents, questions about superseded material and questions with no supported answer. Keep the set separate from the examples used to tune retrieval, and record which corpus version its expected evidence assumes.
Recall@K measures how much of the known relevant material appears among the first K retrieval results. K is the number of results being inspected. A question requiring several passages needs all of its required evidence considered; finding the schedule alone doesn't establish success if the expected answer also depends on a side letter. Record the relevant passage's rank and the retrieval latency too.
Then inspect the context that actually reached generation. A relevant candidate can disappear during reranking or context selection. An answer can also cite a passage that reached the model and still misrepresent it. Retrieval coverage, citation support and answer correctness therefore need separate findings.
A small, carefully chosen question set can expose a failure. It can't justify a universal claim about coverage or statistical significance. The required breadth depends on the question distribution, the consequences of errors and the difference the team is trying to detect. Record those limits alongside the results. Rerun the affected evaluation when the chunker, embedding model, ranking or corpus changes.
Retain a trace that explains a disputed answer
A useful diagnostic trace connects the query to the candidate identifiers, retrieval scores, ranking, selected context and answer citations. LogFire is one platform that can hold structured traces; the important property is being able to reconstruct the path under review.
A disputed answer can then be investigated in order:
- Confirm that the required source existed in the indexed corpus version.
- Inspect whether retrieval returned its relevant passages.
- Check whether ranking and context selection retained them.
- Compare each disputed claim with the evidence available to generation.
The trace needs a data policy as well as fields. Queries and passages can contain private material. Restrict access, set retention and avoid copying sensitive content into broad logs when authorized identifiers will serve the diagnostic task.
Citation clicks, follow-up questions and negative feedback can help select cases for inspection. They don't prove correctness. A reader may open a citation precisely because an answer looks wrong. The team still has to examine that answer and its evidence.
Choose retrieval only when the job needs it
I start with a problem that exists independently of the product being proposed. The same discipline applies to an AI knowledge system. "We need RAG" names an architecture. The useful question is what information a person needs to act, where that information lives and how a response must be checked.
A bounded set of documents may fit into a model's usable context. Supplying it directly can remove a search stage, but the team still has to consider access, input cost, latency and the model's ability to use the material. A page-count cutoff won't answer those questions. A long context window also doesn't settle contradictory sources or make their authority self-evident.
A structured lookup fits a different job. A question asking for an order status, an account field or a calculated total may need a database query with explicit filters. The model can explain the returned fields while the query determines which records and calculations supply an answer to that question. Turning those records into prose chunks may introduce ambiguity the data model already avoided.
Open-ended questions over a changing document collection make retrieval more useful. The system can select relevant material instead of presenting every document on each request. The choice still needs a reason tied to the actual questions, and a source-checking experience tied to the consequences of being wrong.
Permissions constrain every option. The system must restrict which material reaches retrieval results and the model, as well as what a user can open through a citation. Hiding a source panel after an answer has disclosed private content would be too late.
I'd write down the information needed for the decision before selecting the store. A direct lookup, a full-context prompt and a hybrid retrieval system can each be sufficient for a particular job. Additional machinery earns its place when the simpler option fails a requirement the reader actually has.
A metagraph makes provenance part of the relationships
The contract illustration asks for more than similar passages. It asks which document changes another document's effect. That relationship can become part of the knowledge representation instead of being rediscovered from text for every answer.
Represent authority, time and contradiction
I use metagraph here for a model of concepts and their relationships that also preserves where claims came from, when they apply and how they relate to conflicting claims. It's an architectural extension of the retrieval approach, not a claim that the documented Archon build implemented it.
Two passages can discuss the same subject while making incompatible claims. Semantic similarity can put them near each other without resolving the disagreement. A knowledge model can retain the distinction: who supplied a claim, which source supports it, which version supersedes it and what contradicts it. Retrieval can then follow those recorded relationships rather than treat closeness in embedding space as authority.
A question may require several linked steps. A term leads to its definition, the definition to an agreement and the agreement to an amendment that changes its application. A traversal can recover that chain if the links exist and are correct. An answer to that question still needs to show the relevant sources and explain the conclusion at the strength those sources permit.
Check the graph's claims too
Graph structure doesn't make extracted knowledge true. An incorrect relationship can lead retrieval to the wrong conclusion just as a missing passage can. A link labeled as an override needs supporting evidence; a date needs a defined meaning, such as the date a rule applies rather than the date a file was uploaded. Contradiction needs to remain visible where the sources don't resolve it.
The same approach can help organize market knowledge. A customer's situation connects to their own customers, suppliers and changing constraints. Those connections give investigation a direction, but a proposed relationship needs evidence before it becomes a factual claim in an answer.
A metagraph is useful when its recorded relationships help answer the question and remain open to inspection and correction.
Ask a team to trace an answer and its failure
A team evaluating a retrieval system needs an answer it can take apart. Use a question from the actual work, with evidence identified by someone who understands the domain. Ask the team to follow the source through ingestion, retrieval, ranking, generation and the citation the reader opens.
The chunker discussion should produce actual chunks with their parent context. The index discussion should show which document versions are eligible and how changed material is updated. The ranking discussion should show the candidate set and the context selected from it. The citation discussion should end with the relevant passage open at the version used in the response. These are things a team can inspect together, including when the result is wrong.
An evaluation report needs the questions behind its score. Ask what evidence counted as sufficient, whether questions were held out and which kinds of failure the set can detect. An observability discussion needs a trace that connects to a specific answer under review, with an explanation of who may inspect its contents. A tool name on a slide answers neither question.
I'd also ask for one consequential change to that example. Use a superseded source, withdraw a supporting document or ask a question the corpus can't answer. The system should expose the changed evidence or the lack of support. An answer that keeps its earlier certainty after losing its evidence needs correction, even if every citation identifier still resolves.
The original contract illustration has a specific end condition. The reader can locate the stated cap, inspect the material that changes its application and see which source version a generated answer used. A missing side letter should remain a missing source, with the affected conclusion limited accordingly. The system shouldn't supply the absent legal relationship from a confident guess.
My Archon work gave my agents a way to retrieve the corpus I wanted them to use. The broader design here asks what it takes to make that use inspectable. A team can begin with a simpler retrieval system and add components as failures justify them. It should still be able to reopen the evidence behind an answer it has already given.