A working system makes more questions affordable. Once a team can reliably collect evidence, develop alternatives, evaluate results and hand work to the next person, it can investigate ideas that would previously have required too much coordination. The opportunity grows beyond producing a familiar deliverable faster. A team can examine more angles, challenge more assumptions and run a useful experiment before making a larger commitment.
That capacity depends on how the work is organized. An agent can generate a hundred headlines while leaving the audience undefined. A research system can collect hundreds of sources while losing the passages that support its conclusions. A workflow can complete every step while its receiver still lacks something usable. Increasing the amount of activity can make those gaps more expensive.
Mapping connects a desired result to the capabilities, dependencies, commitments and evidence needed to produce it. Data mapping preserves those relationships across people, agents and tools. A bounded unit of accepted work turns the map into a commitment someone can assess. Its outcome supplies evidence for the next comparable decision.
A learning factory is an arrangement built around that cycle. It produces useful work while retaining enough of the attempts, judgments and outcomes to improve how subsequent work is done. Failed experiments and inconclusive results belong in the record alongside accepted outputs. The improvement occurs when those records change a later choice and the change is tested.
This reference develops the method from the ground up: sizing work through acceptance, mapping capabilities, connecting events to purpose, preserving evidence through an intelligence stack, composing reusable operations, and choosing decisions that can survive evaluation. A detailed headline example shows how broad creative exploration can become a defensible shortlist. The later sections extend the method to cooperating specialists, quantitative testing and evolutionary changes, then provide a five-stage operating runbook.
The frameworks have different jobs. A capability map locates dependencies. A data map preserves meaning. A decision method chooses an action. Their connections matter more than making them look like one grand diagram. Begin with a result somebody needs, keep the evidence that bears on it, and make each handoff clear enough for the next worker to continue.
Measure work through acceptance
An agent can produce a draft, report that its task is complete and leave most of the delivery risk with the next person. The sources may still need checking. Someone may have to repair the structure, obtain missing inputs or turn the result into a form the recipient can use. An estimate that ends at the first output leaves that work unmeasured.
Define the accepted result before estimating capacity. State what will exist, who will receive it, which checks it must pass and what evidence will accompany it. Measure the work required to reach that condition. A supported procedure ready for another worker to follow is a different unit from a plausible procedure awaiting review, even if both occupy the same number of pages.
The useful unit is a bounded amount of accepted work under stated conditions. A team can call it a task, a work package or a locally defined digital acre. The name matters less than the definition. It must identify the kind of work, available inputs, tools, permissions, review requirements and support included in the estimate. Without those conditions, two teams can use the same unit while promising very different amounts of work.
Comparable attempts establish a local measure
Begin with work that has already been attempted. Bent Flyvbjerg describes reference class forecasting as taking an outside view from the actual performance of comparable projects. The method asks what happened in the relevant class before concentrating on the new plan's particular story. Applying that principle to agent work starts with a defensible comparison between attempts, rather than a universal conversion from tokens or elapsed time into completed tasks. Flyvbjerg, From Nobel Prize to Project Management
Decide what makes an attempt comparable before selecting the examples. A research brief assembled from accessible documents differs from one whose evidence requires interviews. A draft checked by a specialist differs from one that must pass without that support. A routine export differs from an export whose fields have never been reconciled. Similar-looking final files can conceal different work.
Keep failed, interrupted and rejected attempts in the comparison. A collection containing only accepted outputs describes the surviving work while losing what those outputs cost to obtain. Record the original allocation, what the attempt required, where it stopped and what remained unresolved. A failed attempt can reveal a missing dependency even when it produces nothing suitable for delivery.
Human rescue belongs in the record. If a person supplied the missing reasoning, corrected the factual errors or rebuilt the output, the attempt demonstrates a supported workflow. It supplies weaker evidence for an unaided promise. Recording that assistance preserves the genuine result and identifies the support required to reproduce it.
Consider an illustrative team estimating a short evidence brief. Earlier attempts produced drafts quickly, but acceptance required a source audit, corrections and a receiving editor's check. One attempt also needed help obtaining a document. The team should compare the new assignment with the entire delivery path. If the new brief requires unavailable evidence, adding writing capacity can't remove the access dependency. The estimate needs an effort allowance and a separate condition about obtaining the input.
A project with no comparable attempts has a provisional measure. Choose a bounded trial whose failure the owner can tolerate, state the uncertainty and keep the result. Calling the estimate provisional should change the commitment: a smaller scope, an explicit dependency or an experimental delivery condition. The label alone does nothing to reduce the consequences of a miss.
Preserve capacity for what execution reveals
Leave capacity uncommitted when the record shows that investigation, correction or integration is likely. The allowance must remain available after other work is accepted. Reserving it for one task and assigning it to another makes the first estimate depend on capacity the worker no longer has.
Record how the allowance was used. Investigation necessary to meet the original acceptance condition belongs to the original task. An attractive improvement discovered along the way may need a separate decision and scope. Combining them hides whether the first task was underestimated or the team chose to do more.
Reserved capacity also leaves authority unchanged. An agent may have room to investigate a missing fact while lacking permission to buy a service, change a recipient's access or expand the deliverable. Its instructions need to identify which choices it can make and which require the owner's decision. Independent authorized work can continue while a dependent choice waits.
Unused capacity can remain unused. Filling it with extra deliverables after a favorable attempt changes the scope being measured. Keep the original result distinguishable from any additional work so that the next estimator can recover what the first commitment actually required.
Size and confidence qualify different claims
Size describes the expected work. Confidence describes the evidence supporting a specified claim about that work. A small task can have a highly uncertain estimate because an input or acceptance condition remains unresolved. A large task can have a well-supported estimate because the team has completed comparable work repeatedly.
Write the proposition before assigning confidence: this task can reach this acceptance condition within this allocation, using these inputs and this support. Confidence in an agent's general ability is too broad to answer that question. Confidence that a draft can be produced says little about whether its claims will survive review.
Keep the reasons beside the judgment. Name the comparable attempts and the differences that may invalidate the comparison. A numerical band can communicate uncertainty, but its apparent precision must not conceal a weak evidence base. Where the team has no calibration record, a clearly explained qualitative judgment can be more useful than an unsupported percentage.

Preserve the estimate made before execution. If new evidence changes it, record the revised estimate and the reason without overwriting the original. Comparing the final cost with a prediction rewritten after the result would hide the error the team needs to learn from.
Changes to tools, review standards or access conditions can justify a new local definition. Keep earlier outcomes attached to the definition under which they occurred. A faster workflow may represent a real improvement, a reduced acceptance standard or work shifted to someone else. The record must let the next reviewer distinguish those possibilities before enlarging the next promise.
Map the capability before choosing how to build it
A work estimate needs to identify what the task changes. Start with the person served and the capability that meets their need. Follow the dependencies required to provide it. Choosing tools first makes their available features the definition of the problem and can leave the user's actual difficulty untouched.
Simon Wardley's mapping method anchors a value chain in user needs. Components sit vertically according to their visibility to the user, with connections showing dependencies. The horizontal axis describes evolution through genesis, custom-built, product and commodity forms. These are separate dimensions: an underlying service can be essential while remaining largely invisible to its user. Wardley, Finding a path
Consider a hypothetical operator who needs to inspect whether agent work is ready for delivery. That capability depends on an accessible result, an assessment and the evidence behind it. The assessment depends on criteria and access to the correct output. Evidence capture depends on the operations being observed. Drawing those relationships first exposes questions a list of software names would miss: who can inspect the result, which version was checked and where a missing observation would prevent acceptance.
Give established products and uncertain workflows separate positions
Genesis describes a novel capability. Custom-built work supplies a particular solution. Product provision makes a capability available as an offering, including rental; commodity provision makes it commonplace, including utilities. Assess the component's characteristics and available provision when choosing a position. Wardley, Finding a path
Place each capability at the level being assessed. A purchased document editor and a new method for verifying the documents inside it require different judgments. The editor may be an established product while the proposed verification workflow still needs experimental work. Combining both into one point conceals the question that could prevent delivery.
The same distinction prevents needless reinvention. If a standard service already supplies the required storage behavior, identify what can be reused. Direct custom effort toward the unresolved connection or method. Use the placement to remove unnecessary work from the build plan and identify the remaining custom work.
For each placement, record what is being placed, which observations support it and what would cause a revision. An agent's unfamiliarity with a tool tells the coordinator something about that worker's preparation. It provides little evidence about the tool's evolutionary position. Conversely, familiarity with a product doesn't establish that a new combination of its features will meet the acceptance condition.
Wardley's evolution axis concerns changing forms of provision, driven by supply and demand competition. It doesn't measure elapsed project time. A delivery date on a roadmap supplies no evidence that a component has become more established. Wardley, Finding a path

Keep intended behavior separate from demonstrated behavior. A planned integration remains a proposed capability until the relevant conditions have been tested. A successful test can support a narrower claim about that integration. It can't establish every behavior the underlying product offers or every situation the team hopes to handle.
A map position has a different basis from an effort estimate
Attach work size and confidence to the component without turning them into additional meanings for its coordinates. An established product can require substantial integration work. A small experiment can investigate a novel capability. Moving a component toward a more established position doesn't show that the remaining task has become small.
Confidence also needs separate objects. A team may have strong evidence that a capability is available as a product and weak evidence about the effort required to connect it. It may trust an input's origin while doubting whether that input applies to this decision. One combined confidence score would leave a reviewer unable to identify which claim needs attention.
Ordinal placement is often sufficient. A component can sit near the product region with a note that a particular dependency requires custom work. Decimal coordinates require a measurement rule and evidence that the extra precision changes a decision. A carefully drawn point supplies no such evidence on its own.
Preserve disagreement rather than averaging it out of sight. Two reviewers may be assessing different versions, different users or different component boundaries. Resolve those differences before treating their judgments as competing measurements of the same thing. If they still disagree, retain the reasons and identify the observation that could distinguish them.
Use the map to choose the next action
Wardley places the map within a strategy cycle of purpose, landscape, climate, doctrine and leadership. Purpose establishes what the organization is trying to accomplish. The landscape describes its situation; climate concerns forces acting on that situation; doctrine supplies ways of operating. Leadership chooses a course with those factors in view. Wardley, From purpose to leadership and back again
Apply that cycle to the proposed work. Identify the purpose before choosing an intervention. Examine dependencies and changes outside the team's control. Check whether the team can communicate the task, challenge its assumptions and use an appropriate method. Then make the context-specific choice. A technically accurate map can still support a poor decision if the team overlooks the purpose, a changed condition or its own inability to execute.
The map earns its cost through a choice: reuse a service, connect existing capabilities, investigate an uncertainty, remove unnecessary work or defer a component. Start with the decision currently blocking the promised result. Expand the map when another dependency could change that decision. Stop expanding when the next detail would leave the action unchanged.
For the hypothetical delivery workflow, the team may discover that existing documents and links already let a reviewer inspect outputs. Its uncertain work lies in capturing the correct version and defining the acceptance check. That finding supports a narrow next task. A more elaborate retrieval system can wait unless the present evidence shows that finding the material is the limiting problem.
Different positions call for different work. An unresolved method needs an investigation that can answer a stated question. An ordinary capability needs the checks appropriate to using it. Treating both as research wastes effort on settled behavior. Treating both as routine implementation hides the assumption the experiment was supposed to test.
Record the starting position before acting, then keep the action, observation and revised judgment together. If a test fails because a required input was unavailable, repair the dependency assessment. If it fails because the method can't produce the result, revisit that method. A local failure need not move every component or erase the accepted work around it.
External evidence can also change the map. Check which capability, version and conditions a report describes before applying its result. A recent account of a different situation may contribute less than an older observation that matches the present task. The revision should identify the evidence that changed the choice, so the next worker can challenge the same reasoning instead of inheriting an unexplained coordinate.
Define the result the recipient can recognize
Before choosing a method, establish who faces the problem and what would change for them. A request for an automation, dashboard or document names a possible intervention. The diagnosis needs to survive removal of that intervention's name. Describe what keeps happening, who deals with it, what it prevents and what the consequences are.
In an illustrative research workflow, a manager may ask for a weekly dashboard. The underlying problem could be that project decisions rely on incompatible accounts of completed work. A dashboard might make the disagreement visible without resolving it. A shared acceptance condition and evidence accessible to the decision-maker might address more of the problem. The diagnosis determines which work belongs in scope.
Describe the present situation and an observable future
Record the present difficulty from evidence: conversations, observed behavior, existing records or the results of earlier attempts. Distinguish what a person said from an inference about why they said it. A job title can identify a responsibility; it can't establish a private fear, belief or objection.
Earlier experience can explain why a proposed change will be difficult. Someone may distrust a report because prior versions concealed missing inputs. A team may avoid a new procedure because it requires information they don't possess. Confirm those explanations with the people or records involved. An invented psychological story can make a plan sound perceptive while sending the work toward the wrong cause.
Describe the future in observable terms. Instead of promising that a manager will feel in control, state what they will be able to inspect or decide. They might be able to identify which deliverables passed review, which promises depend on missing inputs and who owns the next decision. Those capabilities give the work a test beyond producing a more attractive report.
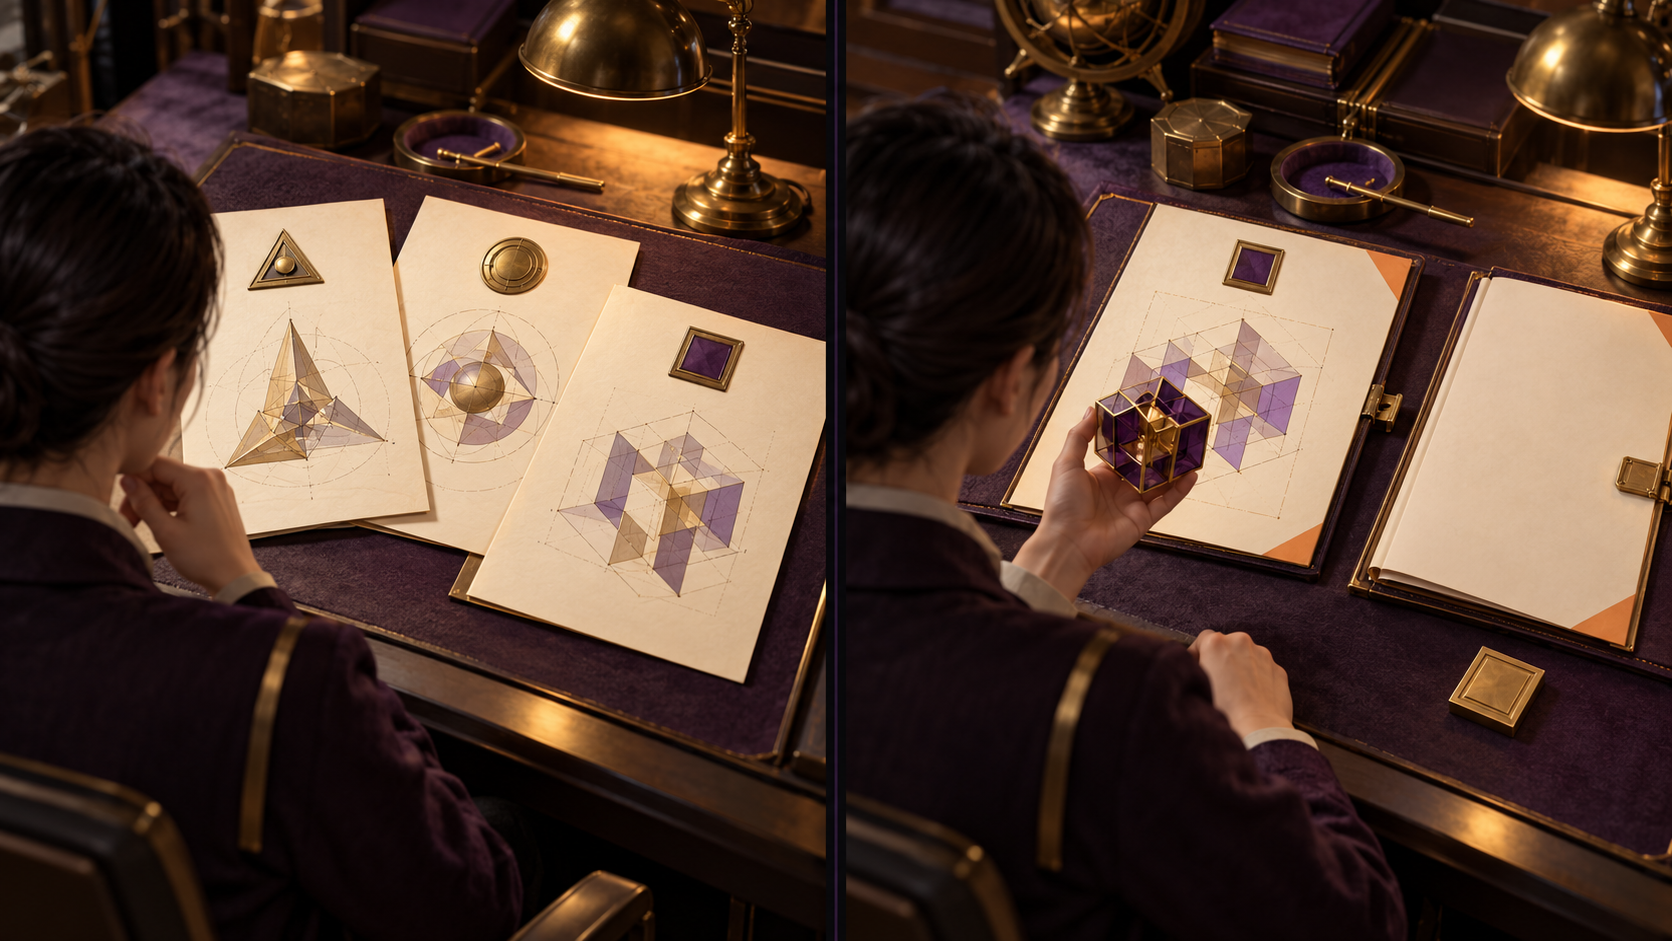
- Left: incompatible handoff records.
- Right: inspectable artifact and source.
- Open folio: next decision remains unresolved. The right side is not automatically approved.
Then identify the change required between present and future. Which behavior must change? Which information or authority must become available? What will support the new behavior during ordinary work? A procedure that depends on contributors supplying evidence must account for whether they can and will supply it. If a necessary participant declines the change, the proposed route needs revision.
Begin where the audience's decision begins
A recipient's existing understanding determines what the explanation must do. Someone still deciding whether a problem matters needs different evidence from someone comparing ways to solve it. Someone ready to implement needs usable instructions, input requirements and failure handling. A generic statement about benefits may answer none of those questions.
Establish this starting point from the exchange or the available audience evidence. Record what the recipient already knows, what remains unresolved and which decision the output should enable. For a handoff to another agent, include the records and constraints it needs to act without reconstructing the conversation that produced the assignment.
Understanding the audience should change the content. A buyer worried about disruption needs an account of the transition and its dependencies. An operator comparing methods needs the conditions under which each method is appropriate. A reviewer needs the claim, its evidence and the acceptance rule. Repeating the audience's language without answering its decision leaves the explanation unfinished.
Give every asset a distinct contribution
Rank the value points that emerge from the diagnosis. Keep the core argument easy to follow, then organize supporting points beneath it according to their contribution and evidence. The number should follow the material and the reader's job. Each point needs a distinct contribution to the future being promised; splitting one claim into several does not create additional value.
For each candidate, state the insight, why it matters to this recipient and what supports acting on it. A claim of superiority also needs a supported comparison with alternatives. Frequency in the source material can suggest a candidate, but it doesn't establish importance. Ask what decision or understanding would change if the recipient accepted the point.
Assign each asset a job in that case. A short explanation can establish the question. A reference document can supply the method and evidence. A worked example can show what the method requires. A visual can make a dependency or comparison easier to inspect. The assets can emphasize different points while contributing to the same promised result.
Check both directions. Every asset should advance a point and add something its format can convey. Every retained point should have enough support somewhere in the package. Repeating a claim across several formats can create apparent consistency while leaving its evidence absent. Remove redundant assets or give them a specific unresolved job.
Write the acceptance contract before execution
The assignment needs an agreed result, failure conditions and an inspectable handoff. Write these while the owner and receiver can still correct a disagreement. A broad instruction to improve quality lets each participant supply a different definition and postpones the conflict until delivery.
Quantitative success requires a defined measure, a baseline where relevant, an observation window and a justified threshold. A request for a double-digit improvement leaves the result undefined until it says what improves and how the change will be measured. A target may express the owner's ambition; evidence must still establish whether the proposed work can plausibly reach it.
Qualitative criteria need comparable clarity. A procedure might have to let an unfamiliar worker identify required inputs, execute authorized steps and recognize the condition for stopping. The receiver can inspect those features and test the procedure. A word such as professional or compelling needs an agreed interpretation before it can bear the weight of acceptance.
Name ways the work could appear successful while defeating its purpose. An evidence brief can be polished yet omit conflicting sources. A dashboard can display complete-looking totals while hiding unresolved records. A procedure can achieve speed by skipping required review. These failure conditions should exclude a method, trigger a correction or require a specific check during execution.

Finally, specify what the receiver will obtain, where it will be available and which evidence accompanies it. State the boundary of the delivery: a proposal ready for decision, a tested component or a completed project. Passing the local check preserves a useful result. It leaves larger claims open until their own evidence arrives.
Trace an event to the mission it serves
A local success becomes meaningful through its connection to a larger result. Use the full chain: event → data → decision → action → task → project → strategic direction or initiative → objective → mission. Purpose runs through the chain, giving each level its reason to exist. Reading downward constrains the work; reading upward tests what the observed work can support.
These levels answer different questions. An event is something that happens. A task promises a bounded result. An objective names an outcome within a defined cycle. Keeping the distinctions allows a team to accept real progress at one level without declaring every level above it complete.
Separate an occurrence from its observers' accounts
An event happens whether the system records it or not. Data preserves what an observer captured about it. Several observers can describe the same occurrence differently because they had different access, captured different parts or drew different inferences. Identify the occurrence and the account separately so that disagreement can be investigated at the correct level.
A reviewer might reject a draft during a handoff. The event is the rejection. The review record might capture the reason, the version examined and the criteria applied. A worker's summary might record only that the draft needed improvement. Those accounts provide different evidence for the next decision. Preserving both makes the missing detail visible.
Record the limits of capture. A dropped response, absent timestamp or partial observation leaves a gap that later reasoning must retain. An opinion can be valuable data about someone's judgment. A fear can be valuable data about what someone anticipates. Neither should silently become an established fact about the event or a verified prediction of what will happen next.
Useful data connects the thing described to its attributes and the process that produces or uses the information. A field labeled status needs to identify whose status, at what point and for which purpose. Otherwise a downstream worker may treat a producer's completion claim as a receiver's acceptance finding.
Connect the evidence to an authorized choice and action
A decision uses the available account of the world to select what to do. Record the alternatives considered, the selection rule, the evidence available and the owner of the choice. That record should let another person identify which new observation would change the decision.
Authority belongs beside the choice. An agent may have sufficient evidence to recommend replacing an input while lacking permission to purchase the replacement or change the project's scope. Keep the unresolved decision with its owner, along with an agreed default or a clear condition for proceeding. Work that doesn't depend on that choice can continue within its existing authorization.
Distinguish an information gap from failure to use information already available. Additional research can address the first. The second may require clearer instructions, a different check or an examination of the decision rule. Preserve what the worker knew at the time; otherwise both failures can disappear into a vague instruction to improve the prompt.
An action puts the choice into effect. It needs an input, an expected output and a failure condition. For the rejected draft, the decision might be to remove an unsupported claim; the action is the edit performed on the identified version. The action record should show whether the change occurred and whether it stayed within the authorized scope.
Actions can contain smaller choices. Revising a paragraph involves deciding which claim remains, how narrowly to express it and which source supports it. Assessment should identify the choice that needs correction. A single score for the whole operation can conceal whether a defect lies in factual support, structure or wording. Keep those judgments separate enough to direct the next correction.

Require composition at the task and project levels
Actions form a task when their combined result can meet an acceptance condition. Removing one unsupported claim doesn't finish a brief that still needs its references checked. The task must preserve the promised whole, including work that may be invisible in the final artifact.
A fresh worker should be able to take the assignment and act. Supply the relevant context, the records it may change, the required output and the completion check. Decomposition is useful when each smaller assignment produces something the receiving task can use. A list of operations with no task-level test leaves the executor unable to establish whether their combined effect is sufficient.
Tasks compose into a project with a concrete deliverable, scope, dependencies and definition of done. The project owner checks how the outputs fit together. Ten accepted components can still fail to produce a usable service if they assume incompatible inputs. A completed-task count can't answer that composition question.
Project scope also separates necessary work from adjacent opportunities. An improvement may be valuable and still belong elsewhere. Conversely, a dependency may reveal a missing task that the promised delivery requires. The owner needs to distinguish those cases before expanding work or declaring the project complete.
Test contribution above the delivered project
A strategic direction, often organized as an initiative, explains which class of projects the team has chosen to pursue and why. It sits between a project's deliverable and the objective that deliverable is meant to advance. Omitting this level hides the strategic hypothesis: why should this kind of work produce the intended outcome?
Suppose a team adopts an initiative to reduce rework through evidence-based handoffs. A project delivers a review procedure and the records needed to use it. Tasks produce and verify those components. Shipping the project establishes that the procedure exists and works under its acceptance conditions. The initiative still needs evidence that using the procedure contributes to less rework.
An objective states the tangible outcome within a defined cycle. Its owner specifies what will be observed and how movement will be judged. A mission supplies the enduring direction that makes those objectives worth pursuing. Achieving one objective can advance the mission while leaving further work ahead.
Follow the example downward as well. The mission constrains which outcome matters; the objective constrains the initiative; the initiative selects projects; the project determines required tasks. Those tasks determine useful actions, authorized decisions and observations worth capturing. If the chain breaks, identify the unsupported connection. More activity below it can't by itself establish the missing contribution above it.
Make commitments assessable by their receivers
A dependency in a plan names something the work needs. It still needs a keeper, a commitment and a way to establish whether the commitment was kept. Assigning a task to another worker doesn't establish that the worker accepted its conditions or has the means to fulfill them.
Promise Theory provides a model for examining those boundaries. Mark Burgess and Alva Couch describe autonomous agents that make and receive promises about behavior. An agent in this model can be a person, service or component; the term doesn't require an AI system. Separating the participants makes their commitments visible even when a coordinator administers the larger system. Burgess and Couch, Modeling Next Generation Configuration Management Tools
Promise what the participant can control
Each participant must distinguish its own behavior from the behavior it needs from others. A coordinator can commit to supplying inputs, forwarding a result or reporting an observed refusal. A worker can commit to a bounded output under stated conditions. Neither gains control over another participant's behavior by putting a desired outcome in its plan.
Carry conditions through the chain. If a researcher can deliver a supported comparison only after receiving two source documents, the editor's dependent commitment must retain that requirement. Omitting it from the next handoff converts a visible dependency into somebody else's surprise.
Write exclusions as clearly as obligations. A research assignment may cover what the available sources establish while excluding a claim about unobserved customer behavior. A review assignment may verify factual support without authorizing publication. These boundaries let recipients plan around what they will actually receive.
Responsibility must match authority and inputs. A worker can't keep a promise that requires an approval it is forbidden to grant or an input nobody has committed to provide. The coordinator should obtain the missing commitment, narrow the promised result or leave the dependent work explicitly unresolved. More emphatic instructions can't supply the missing condition.
Agreement to receive work precedes assessment of delivery
Burgess separates a sender's offer, a receiver's acceptance or rejection and the receiver's later assessment of what arrives. Agreement to participate and judgment of the delivered result are different acts. Burgess, Cooperation in Human and Machine Agents

A producer's completion message is one account of the work. The receiver needs access to the promised output and a check that addresses the claim being made. File existence establishes that a file is present. Assessing whether it contains a supported, usable procedure requires inspecting and, where appropriate, trying the procedure.
Name the observer who can perform each check. A verification plan that requires access the receiver lacks leaves another dependency unresolved. Provide authorized access, assign a qualified assessor or narrow the claim to something the receiving party can assess. The handoff should identify the version checked and the evidence supporting the finding.
Different receivers may depend on different properties of the same output. A writer needs a source note that accurately states what a passage supports. An editor may also need its date, context and limitations. A final reviewer needs to confirm that the sentence in the delivered article still respects those limits. Passing one receiver's check can't silently substitute for all the others.
An illustrative research handoff makes these obligations concrete. A researcher supplies a claim, source location and applicability limit. An editor checks whether the source supports the claim. A writer uses the accepted finding within that limit. A reviewer inspects the final wording against the evidence. Each role contributes a bounded result that the next role can examine; agreement among the roles alone supplies no external evidence that the claim is true.
Record a breach where its effects begin
Local checks can all pass while a workflow fails between participants. A transformation may expect clean records. Storage may assume capture excludes missing values. Capture may assume the source supplies timestamps in the required form. Each step can complete its own operations while relying on a condition that nobody established.
Make input promises visible to their consumers and check the properties on which dependent work relies. If a timestamp is absent, retain that absence. Filling the field with a plausible value supplies downstream decisions with an observation that never occurred. If the consumer can't establish that an input is fit for use, its own report must preserve that uncertainty.
Treat a breached commitment as an event with an owner. Identify the earliest unsupported condition, the affected input and the consumers that depend on it. Repeating the final task won't repair an input no upstream participant promised to provide.
Separate required and optional dependencies. A missing required source can stop a supported comparison. A missing optional illustration may leave the argument usable while reducing the planned presentation. The consequence depends on the consumer's actual acceptance condition. Treating every edge as equally critical hides which failure prevents delivery.
Repair the commitments downstream
A repair must reach the participants who relied on the old condition. The keeper reports what failed, what remains available and which proposed correction is supported. Each dependent keeper reassesses its own promise. The coordinator records what can still be delivered, what needs correction and what requires a new agreement.
Trace consequences to the user value affected. Identify how much dependent work is exposed and whether an accepted alternative exists. A risk weight needs a stated basis in those consequences. Where the effect remains uncertain, preserve the uncertainty instead of inventing a precise score to complete the record.
A dependency diagram can help a larger team inspect this network. Write the participants, commitments, required conditions and dependent actions before drawing it. The diagram should expose an unowned promise, a condition that blocks work or a consumer that needs notification. It can't establish an agreement the participants have never made.
Use a Petri-net model when the question concerns which conditions enable dependent actions. Its places, transitions and markings provide a formal way to represent those relationships. A simpler dependency graph may be enough to identify affected consumers. Choose the representation that makes the unresolved commitment inspectable. Desel, Place/Transition-Nets I, Petri Nets 2000 tutorial
Acceptance of the repair requires more than correcting the source. Check that affected receivers have the revised input and have reconsidered their commitments. An updated document sitting beside decisions based on its previous version leaves the breach active in the work that still relies on it.

Data mapping keeps the evidence attached to the work
A commitment becomes difficult to assess when the request lives in one conversation, the output in a folder, the review in another conversation and the result in somebody's memory. Each piece may still exist. The missing part is the relationship between them. Which request did this output answer? Which version did the reviewer approve? Did the later result concern that version or a revision? Saving more text won't answer those questions unless the records preserve which thing is which.
That is the job of the data map. It carries identity, meaning and evidence across the work so the next decision can use them. A reader should be able to move from a recommendation to the observation supporting it, then back to the attempt that obtained the observation. An agent should be able to make the same trip without reconstructing the relationships from similar filenames.
Different maps answer different questions
A capability map connects a user need to the capabilities and dependencies required to meet it. A workflow map shows which operation can run next and what conditions change the route. A field-level data map explains how a value from one record becomes a value in another. A provenance graph records derivation and dependence: this assessment judged this output, which used these sources. A similarity view places related material near other material according to a chosen representation.
The same records can appear in these views while the links retain different meanings. A dependency arrow says one capability needs another. A derivation arrow says an output used an input. A routing arrow says execution may move to another operation. None of those relationships follows merely because two items appear close together in an embedding plot.
Keep the relationship type explicit. If a diagram combines several types, give them different labels and make each one inspectable. Otherwise an agent can turn “related to” into “supported by,” then carry that unsupported conclusion into a decision. The diagram can then conceal a missing step in the argument.

A small system can express these relationships with linked records and ordinary tables. A graph database, a vector index and a three-dimensional explorer are implementation options. Choose them when the questions and workload justify them. Durable identifiers and source links are useful immediately, including when the present retrieval method is a person opening a record.
Give the request, attempt and judgment different identities
A task describes the result requested under specified conditions. An attempt records a particular effort to deliver it. An output is something that effort produced. An assessment judges an identified output against identified criteria. An outcome records what subsequently happened. A decision records the choice made from the evidence available at the time.
Those distinctions prevent several ordinary errors. Retrying a failed task creates another attempt; it must not erase the failed attempt. Revising a document creates another output version; it must not inherit approval of an earlier version without the required check. A favorable assessment can justify the next step while the eventual outcome remains unknown. Recording “accepted” in a field that also means “worked for the audience” would collapse two different events.
A practical starting record has these relationships:
| Record | What it identifies | Relationships worth preserving |
|---|---|---|
| Task | Requested result, conditions and acceptance rule | Request version, responsible operator, applicable policy |
| Attempt | One execution against that request | Task, workflow version, inputs, tool calls, interruptions and cost |
| Output | Exact artifact or structured result | Producing attempt, source inputs, parent version |
| Assessment | A judgment of that output | Output version, assessor, rubric version, evidence and defects |
| Outcome | An observation after the work | Relevant output or exposure, observation window, collection method |
| Decision | A choice and its stated basis | Available evidence, alternatives, authority and resulting action |
This proposed record can be implemented without six physical tables. A document store, relational tables or linked application records can preserve these distinctions. The relevant test is whether a later reader can reconstruct the relationships without guessing. W3C's provenance model provides an established vocabulary for entities, activities, agents and derivation; the task-specific records above adapt that general concern to agent work. W3C PROV Data Model
Consider a fictional editorial team preparing a guide to document-export workflows. Its question is whether a reader can retain review comments and working source links when exporting a document. A researcher gathers documentation, another worker runs a bounded export test, and an editor prepares the comparison. The example concerns no named vendor and reports no measured product performance.
The task is the comparison requested. A research call is part of an attempt. Its response is an output, separate from the exported sample and the eventual guide. The editor's check applies to one guide version. A later observation that a reader could follow its instructions is a different record again. Keeping those identities separate lets the team discover whether a failure came from the documentation, the test conditions, the writing or a subsequent product change.

Six responsibilities carry evidence into a decision
An intelligence stack can be organized around six responsibilities: capture, storage, transformation, serving, observability and decision interface. They describe duties along the evidence path. They do not require six services, six vendors or six stages of organizational maturity. A small application can perform all six, provided the handoffs preserve meaning. Intelligence Engineering
Design backward from the operator's choice. What will the editor need to decide whether the guide can advance? Which evidence would justify that decision? Which records and checks would supply it? Then build a narrow path through all six responsibilities. Completing a sophisticated collection layer while leaving the editor unable to inspect its result postpones the actual job.
Capture preserves what arrived and what failed to arrive
Capture begins with an event or an observation that the work needs. Preserve its identity, origin, relevant times and context. For a research request, retain the question, provider request identifier when available, returned response, source references and capture status. A successful search returning no relevant result differs from a failed request. A response lost during storage differs from both.
In the export-guide example, capture the documentation passage and its location, the edition it describes, the test settings and the exported artifact. A screenshot alone may omit the setting that determined whether comments were included. An extracted sentence alone may omit the heading limiting it to a particular file format. Capture enough context to test the claim the next worker will make.
Specify duplicate handling. If a connector retries an event after a timeout, the system should recognize that it may be seeing the same event again. Preserve retry evidence while preventing an accidental second business event. A duplicate observation should not become a second independent confirmation simply because the collector received it twice.
Capture also has boundaries. Retain material only within the applicable access and retention rules. Redact secrets, keep a record of deliberate omissions and distinguish redaction from technical capture failure. A request to preserve evidence gives no reason to distribute restricted source content to every downstream worker.
Storage gives the retained record a stable meaning
Storage needs definitions as well as durability. Decide what identifies a record, what creates a new version, which fields are required and how rejected input remains diagnosable. A store that silently accepts two meanings for the same field preserves ambiguity very reliably.
Use a concise work record for the person reviewing the result and a linked execution record for the detail needed to investigate it. Repeated heartbeat events have different retrieval and retention needs from a task's accepted deliverable. They can live behind the same interface without becoming thousands of individually managed tasks.
Keep incomplete and rejected input available to the appropriate investigator. Dropping malformed records may make a dashboard cleaner while hiding the reason its counts changed. Preserve the raw input where permitted, the rejection reason and the validation version. A corrected parser can then be checked against the material it previously mishandled.
Transformation makes the derivation inspectable
Transformation turns the captured material into something another operation can use. It might extract a claim, normalize a date, join a test result to a product version or calculate a cost. Record the inputs, the rule or calculation version and the resulting value. Where a model performs the extraction, retain the extraction instructions and model information needed to identify that attempt.
For the guide, “comments survive export” is too broad a derived field. The underlying claim may apply only to annotated PDF export, with a particular option enabled. A useful transformation preserves those conditions. It can produce a structured observation with an export format, setting, software version, result and supporting artifact.
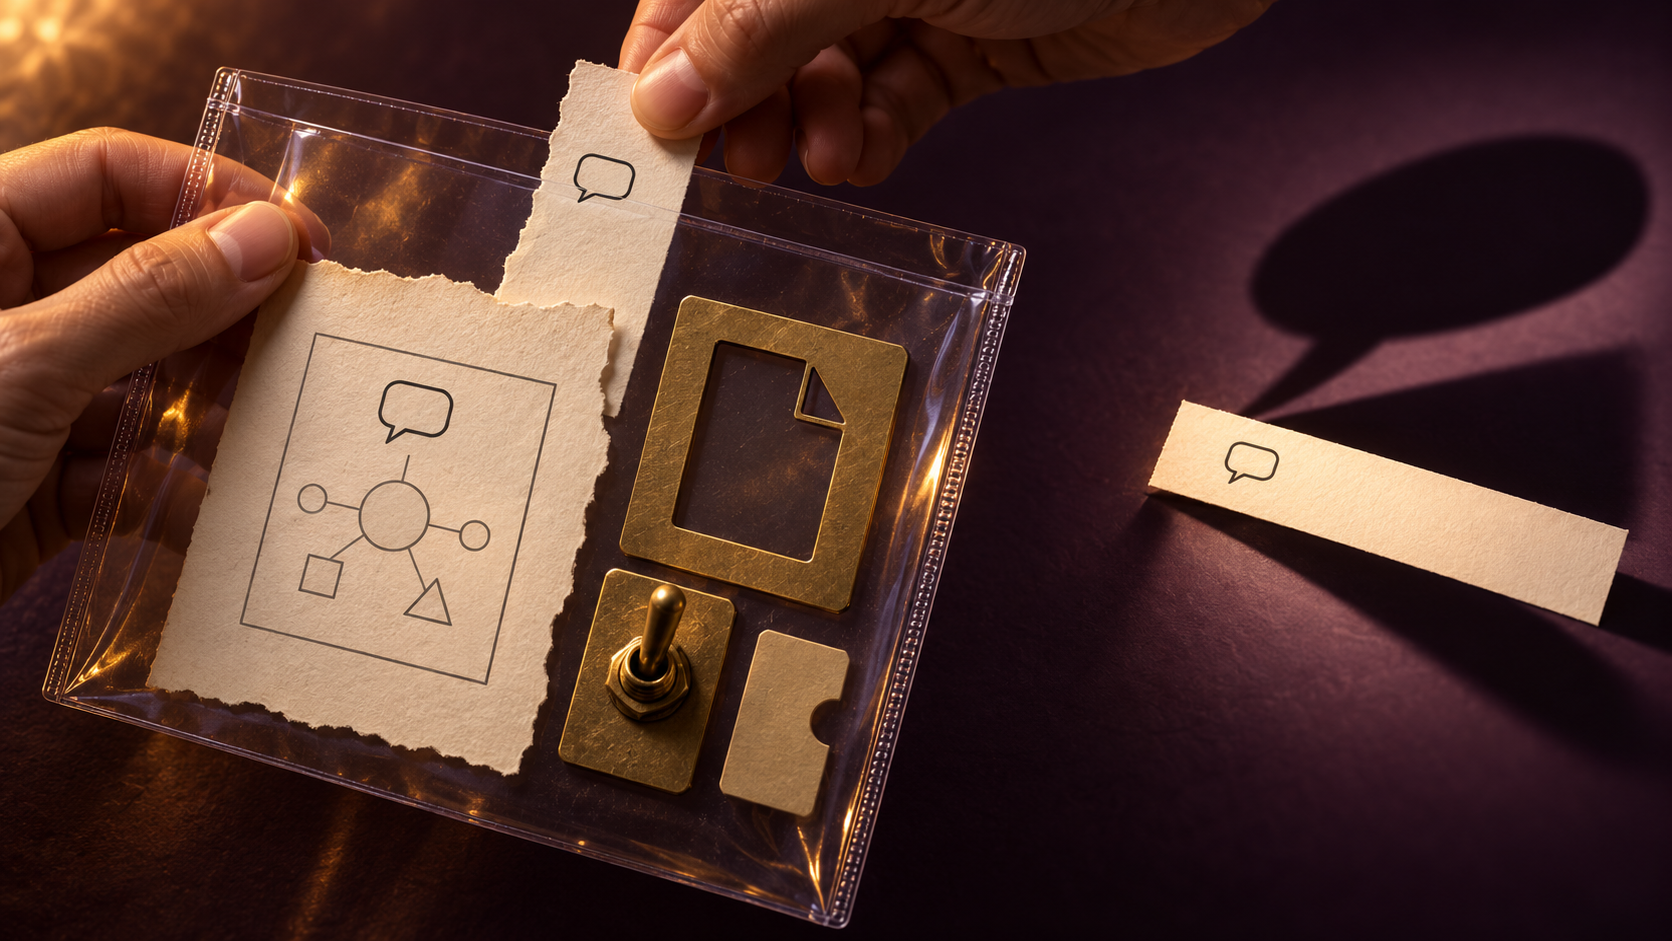
- Claim: the source fragment.
- Source context: conditions surrounding the fragment.
- Export format: the format stencil.
- Enabled setting: the toggle.
- Software version: the notched version marker.
- Illustrative conditions, not vendor test results.
Define what an operation returns when it cannot complete a transformation. An ambiguous product version can enter a review queue instead of joining the first similarly named record. A date that cannot be parsed remains unresolved. An explicit failure state lets the next worker repair the missing input instead of relying on an invented match or date.
Serving gives consumers an explicit contract
Serving makes the result available under agreed meanings. Specify the returned fields, their possible states, the contract version and how changes will be announced. A writer asking for supported claims should receive the relevant evidence packet, including unresolved limitations, rather than every captured document.
A useful response in the example might contain the supported comparison statements, their conditions, source locations, test references and outstanding questions. “Ready for drafting” can mean the packet meets the drafting contract while publication remains unauthorized. Those states deserve separate fields because downstream workers have different responsibilities.
Serve only the information the consumer needs and is permitted to access. A link can lead an authorized reviewer to the full trace without copying that trace into a public-facing artifact. If a summary cannot expose its source, the consumer needs to know the evidence is unavailable to them before relying on it.
Observability explains what the system actually did
Observability connects the work request to execution evidence. It should be possible to see what arrived, which operation ran, what it used, where it stopped and what it returned. Correlation identifiers connect events across tools and services. OpenTelemetry's trace model uses spans and their relationships to describe execution across operations; application-specific evidence still has to be attached deliberately. OpenTelemetry traces
For the guide, a trace might show that source retrieval succeeded, text extraction omitted a table and the claim checker therefore received incomplete evidence. The final answer alone could make this look like poor reasoning. The execution record identifies the missing table as an earlier failure worth repairing.
Record quantities in their own units. Model usage, tool charges, elapsed time, reviewer minutes and retries answer different questions. Mark measurements that were not collected. Observability should expose hidden work without inventing a precise total from incomplete inputs. A later cost comparison can then state which resources it includes.
The decision interface connects evidence to an available action
The decision interface brings the result into the authorized operator's workflow. An editor needs the claim, its support, the unresolved issue and the available next moves. A red status with no explanation forces the editor to conduct another investigation before acting.
In this example, the interface could offer three choices: accept the narrowly supported statement for drafting, request a repeat test under the missing conditions, or omit the comparison. It should show which choice requires additional authority and preserve the chosen action with its reason. The interface can be a task view, a conversation or a form. Its usefulness depends on whether the operator can understand and execute the decision.
Check the whole path with a deliberately awkward case. Submit an ambiguous version, make one source unavailable, retry a successful call and revise a previously accepted claim. Observe whether the editor can still tell what happened. A successful run alone leaves the system's behavior under these conditions untested.
Make the information fit the operator and decision
This is hyper-relevant engineering in practice: the information path and interface are shaped around the specific decision, operator and conditions. A researcher needs source passages and unanswered questions. A writer needs permitted claims and audience context. A reviewer needs the exact output, acceptance criteria and grounds for challenging it. Their views can differ while their records remain connected.
The design should make the relevant discrepancy easier to see. If a claim comes from an outdated product version, show that mismatch beside the proposed sentence. If an estimate is inferred from a conversation, show its origin and estimate status where the operator can correct it. If a task is blocked by a receiver decision, expose that decision rather than another general progress indicator.

The result can be a small interface. Its value comes from helping the operator choose the next useful action with less reconstruction. A sophisticated dashboard that leaves the decision owner searching through separate documents has preserved presentation while losing the handoff the system was meant to improve.
Field-level mappings make assumptions visible
A diagram linking “research” to “draft” still leaves the field mappings unspecified. Which field carries the researched claim? How is a publication date parsed? What identifies the source version? What happens when two sources disagree? A usable mapping spells out how values move and which checks govern that movement.
Start with the decision-relevant fields rather than copying every available field. For each one, name the source location, target meaning, transformation, validation rule and failure behavior. The table below illustrates a small part of the export-guide mapping. These are proposed contracts for the example, not claims about a particular tool.
| Input | Target meaning | Mapping rule | Unresolved behavior |
|---|---|---|---|
| Document identifier and version | Exact source used | Retain source identity; add a capture-version reference | Mark version unknown; do not merge with a confirmed version |
| Passage and page or section | Claim support | Preserve location and relevant surrounding conditions | Route incomplete extraction for recovery |
| Published date text | Source publication time | Parse only supported date formats; retain original text | Keep date unknown and parsing status visible |
| Export test result | Observed behavior under stated conditions | Attach format, settings, software version and artifact | Mark the test incomplete when required conditions are absent |
| Researcher's interpretation | Proposed comparison statement | Link to evidence and label interpretation | Hold unsupported or disputed claims for review |
| Review result | Assessment of an exact draft version | Join by output identifier and version | Reject an assessment referring to a missing output |
Joins need keys, cardinality and a failure rule
A join says two records belong together under a stated relationship. Specify the key and the expected number of matches. One assessment may judge one exact output version; many assessments may judge that version. A source passage can support several claims, and a claim can depend on several passages. Treating all these relationships as one-to-one will either lose evidence or duplicate it unpredictably.
Never use a similar title as an unquestioned identity match. Two documents called “Export guide” might cover different versions. One document might have several titles over time. Prefer stable identifiers and explicit version relationships. Where identity must be inferred, preserve the matching method and confidence as an inference, with a route for correction.

Inspect records with no match or more matches than the contract permits. Suppose the exported sample lacks a software-version identifier. Attaching it to the current release because that is the only release in the store would turn missing context into false certainty. The correct next action may be to recover the test environment or repeat the test. The mapping should make that choice available.
Time fields answer separate questions
An event can occur before a system receives it, and a source can be published long before anyone imports it. Stream-processing systems distinguish event time from processing time for this reason. The same distinction matters when reconstructing an agent's evidence. Apache Beam programming guide
For consequential claims, retain the source's stated publication or effective time, the observation time, the capture time and the time the evidence became available to the deciding worker. Some will be unknown. An exact timestamp in one field does not supply missing precision in another.
For facts or rules whose applicability changes over time, preserve a supported valid-from and valid-to interval when the evidence establishes one. Keep those endpoints separate from capture and availability timestamps, with the basis for each endpoint attached. An unknown endpoint remains unknown; importing a record does not establish when its claim began or stopped applying.
A decision-time snapshot should identify what the operator could actually use then. If a corrected help page arrived later, preserve it as later evidence. Applying that correction retrospectively to the old evidence packet would make the earlier decision look better informed than it was. Preserve the old judgment, then record whether the correction changes it.

Freshness follows applicability, and missing values keep their meaning
A recent source can describe the wrong edition, format or operating conditions. Establish applicability before preferring recency. In the example, a newly updated help page about browser export cannot automatically supersede an older instruction for a desktop application. The question is which evidence supports the claim being made under the conditions the guide specifies.
Set freshness rules around the decision. A frequently changing software feature may need rechecking before publication. The historical fact that an earlier test produced a particular artifact does not expire in the same way. Mark the test's applicability to the current release as unresolved without rewriting the historical observation. Preserve the rule that triggered rechecking so a reviewer can challenge an unnecessarily short or dangerously long interval.
Missing values also need reasons. “Not collected,” “not applicable,” “collection failed,” “withheld” and “not yet observed” should remain distinguishable wherever they change the next action. No audience outcome exists merely because the article has passed editorial review. A zero belongs in the outcome field only when the measurement actually established zero under its defined coverage.
Keep conflicting claims attached to their sources. If a help page promises one behavior while a captured test shows another, retain both and investigate the conditions. The discrepancy might reflect a setting, a version difference, a documentation error or a flawed test. Record the selected interpretation and the evidence that could reverse it. Averaging conflicting facts into a confidence score would conceal the question that needs answering.
Retrieval should lead back to source evidence
Once these records exist, retrieval has a concrete job: find the material needed for the current question without severing its provenance. Broad questions and narrow checks need different routes. “Where have export comparisons failed?” may benefit from summaries across attempts. “Which setting preserved comments in this test?” needs the exact test record and artifact.
Hierarchies provide levels of detail
RAPTOR is a research approach that recursively embeds, clusters and summarizes text to construct a hierarchy. Original chunks sit at the leaves; summaries represent progressively broader groupings. The paper describes tree traversal through selected levels and collapsed-tree retrieval, which searches nodes from different levels together. Its experiments concern question answering on specified datasets. They support investigation of hierarchical retrieval, rather than a universal claim that every operational archive needs this method. RAPTOR paper
In an operating record, a high-level summary can point toward a set of related failures. The next worker still needs the individual attempts that justify the pattern. Preserve the summary's contributing record identifiers, generation version and source locations. Keep the original document's sections alongside semantic groupings so the worker can inspect both the topic relationship and the passage's place in the original argument.
A summary must not quietly eliminate exceptions. If most exports preserved hyperlinks but one failed under a particular setting, a summary saying “exports preserve links” removes the condition that may matter next. The retrieval layer should let the reader reach the exception without already knowing its wording. Evaluate that behavior with questions whose answers depend on limitations, contradictions and minority cases.
Relationships connect material across branches
HippoRAG explores another retrieval route: a knowledge graph searched with Personalized PageRank seeded from query-related information. HippoRAG 2 extends the approach with deeper passage integration and changed online retrieval. These papers investigate retrieval and memory tasks under their experimental settings. They do not establish that graph connectivity proves the truth of a claim or that retaining records automatically improves an organization's decisions. HippoRAG, HippoRAG 2
For the guide, a relationship can connect a feature claim to a release note, a tested setting, a draft sentence and the assessment that questioned it. Those records may belong to different topic clusters. A hierarchy helps find the subject; typed links help follow what depended on what. The two routes can cooperate without becoming the same data structure.
Give each consequential relationship its own evidential basis. An extracted “supersedes” relation needs support for what superseded what. A shared entity name supplies a possible connection, not an instruction to overwrite an earlier claim. When an agent proposes a relationship, retain that origin and its review state. Otherwise generated structure can become trusted infrastructure merely by being stored.
Keep the leaf recoverable after indexing
Each searchable chunk needs a source identifier, source version and recoverable location. A PDF passage needs its page or other usable locator. A transcript passage needs a time range and speaker where relevant. An image-derived observation needs the image and the region or context supporting it. Extraction can make material searchable while still losing a footnote or misreading a table, so the original remains part of the evidence path.
Treat embeddings, summaries and projected coordinates as derived artifacts. Record the procedure and version that created them and preserve the link to the underlying record. If an exploratory display needs three-dimensional coordinates, serve those coordinates and display metadata rather than transferring every full embedding to draw the picture. Selecting a point should open the record it represents.
Assess retrieval against the downstream job. Did it find the applicable version? Did it surface the contradiction? Could the reviewer recover the passage? What did the search cost? A visually persuasive cluster or a high similarity score cannot answer these questions. Compare a proposed retrieval layer with the simpler route already available before making the rest of the workflow depend on it.

Composition lets the same records serve different operators
The evidence model also needs to survive different ways of doing the work. A person may answer a question in conversation. A form may supply the same answer. An import may bring an earlier record. An agent may estimate a missing value. These paths should enter through adapters into one canonical record shape for the thing being described.
Creating separate “human tasks,” “form tasks” and “AI tasks” with incompatible meanings makes later comparison needlessly difficult. Put operator identity and operator kind on the record. Preserve the input path and value origin. The work remains comparable while the system can distinguish a human statement, a directly observed result and an agent estimate.
Entities retain identity while components hold changing evidence
Entity-component-system design separates an entity's identity from attached data and the operations that act on selected combinations of data. Bevy's documentation supplies a concrete implementation of these mechanics, including component-based queries and systems. Borrowing the composition principle for agent work does not require installing a game-engine runtime or imply a particular performance gain. Bevy ECS documentation
An export comparison can carry separately versioned components for its question, source evidence, test conditions, draft text, assessment, cost and observed outcome. A source checker selects records with claims and evidence references. A reproduction check needs test conditions and an artifact. An editorial checker needs the draft and brief. A delivery operation needs the required acceptance and authorization.
Adding a new assessment does not change the identity of the comparison. Changing the draft does create a new version of the text being assessed. A field indicating which text version passed review prevents the delivery operation from treating an old approval as approval of a new draft. Composition makes the needed combinations explicit; the system still has to enforce their dependencies.

Adapters preserve origin instead of pretending all inputs are observations
A conversational adapter can turn “I think this will take about an hour” into an estimated effort value with its speaker and source passage. An agent's estimate should carry the same kind of origin information, plus its basis where available. Neither belongs in the field for measured elapsed time. When the work finishes, actual duration becomes another observation that can be compared with the estimate.
The adapter must also preserve what it could not resolve. If a form omits the export format, it should produce a record with a missing-format state. If a transcript contains two inconsistent answers, it should retain the conflict for resolution. Filling the gap with an attractive default changes the evidence while concealing the change from the next operator.
Use one logical authority for each record, even when several applications display it. A task interface can show a projection of the record while an event store retains execution detail. Those are different views and record types, with explicit ownership. They should not become independent lists in which incompatible versions of the same result can each claim to be current.
Define who may update each component and how concurrent updates are resolved. An agent should not overwrite a reviewed value merely because its research finished later. It can propose a replacement, identify the earlier value and supply new evidence. The accepting operation checks the current version and records the resulting change. This keeps correction possible without turning completion order into authority.
Reuse the model across writing and visual explanation
Creative work can consume the same identified evidence while applying medium-specific rules. An animation beat might carry text, a source reference, timing, position and style as separate data. A layout operation uses the text and available space. A timing operation determines when a relationship becomes visible. A rendering operation turns the resulting state into pixels. The evidence reference remains available when the displayed claim changes.
This makes reuse more substantial than copying a visual effect. A scene that explains a branching decision can accept a different set of choices while preserving the mechanism that makes the branch understandable. A source-to-output animation can retain the same transformation logic across new examples. Each reuse still needs an assessment of whether the mechanism serves the new value point.
Remotion offers a React-based rendering model driven by frame number and composition data. Its Three.js integration synchronizes a React Three Fiber scene with that frame model. A web application may host the result, but a specific web framework is not a prerequisite for the composition. Remotion core idea and ThreeCanvas
The same composition discipline applies whichever renderer is selected. Keep content, evidence and timing inspectable; reuse compatible components and assets under their licenses; and make the final display work at the size where a reader will see it. Choose a still image, diagram, animation or interaction according to the relationship it explains. Motion earns its place when change over time makes that relationship clearer.
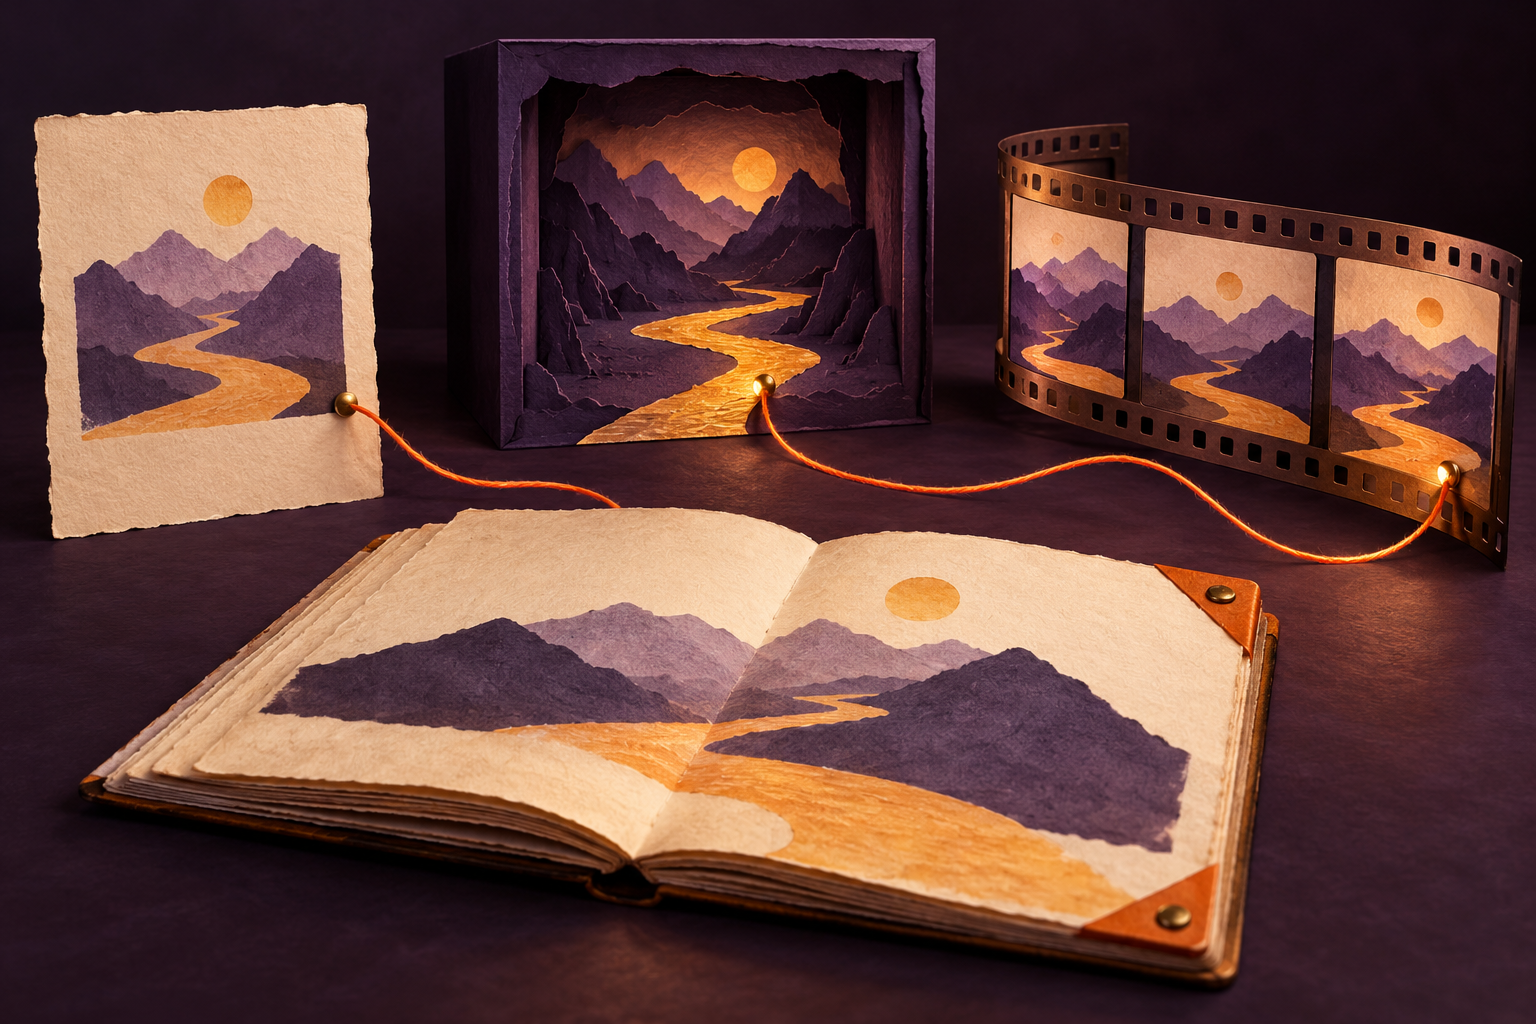
- Shared content and evidence.
- Print: arranged for reading.
- Spatial scene: arranged to show relationships.
- Film: arranged in time.
- The still illustrates shared content across media, not an implemented ECS runtime.
The production sequence follows the same principle. First establish an accepted article whose claims, structure and wording have passed the relevant checks. Then extract and rank the reader value points: decisions clarified, relationships explained, misconceptions resolved and procedures made usable. Keep the core argument visible while allowing as many supporting value points as the material warrants.
Choose creative density and rhythm from those priorities. A diagram may explain a stable dependency; an animation may reveal how a correction propagates; an interaction may let a reader compare policies under changed assumptions; an illustration may provide orientation or a memorable concrete example. A fixed quota for a medium would make the form decide the lesson before the lesson has been examined.
For each selected value, write what the creative should help the reader understand and what its behavior will demonstrate. Storyboard the change, compose the scene and test the actual output at its delivered size. An animated decision tree should reveal which condition changes the route. A decorative pulse around an unchanged diagram contributes little to that explanation.
Assemble a complete tested release, then use human critique to improve the next round. Evaluate each creative against its intended contribution as well as its craft: can the reader recover the relationship, distinguish evidence from illustration and use the insight? A beautiful scene can fail that test; a precise but unreadable diagram can fail it too. The record should identify the defect and the next repair rather than restart the whole article whenever one figure needs work.
Reusable operations need contracts and bounded effects
Composition becomes operational when a worker can select an identified record, read the required components and return a result another worker understands. The unit can be a deterministic function, a retrieval call, a model interaction, a human decision or a whole workflow. Use an agent where its judgment is needed; keep simpler operations explicit.
A node states what it consumes, returns and may change
For a reusable evidence-checking operation, specify:
- Inputs: the question, exact claim, applicable context, source references and contract version.
- Preconditions: required source access, known output version and enough context to assess applicability.
- Outputs: support status, supporting passages, limitations, conflicts and unresolved questions.
- Permitted effects: read approved sources and append an assessment; no alteration of the source or publication of the draft.
- Failure routes: recover an inaccessible source, request missing context, return an unsupported finding or stop at the budget limit.
- Completion: a result meeting the output contract, including a valid unresolved result when the evidence cannot settle the question.
This contract makes “unable to establish support” usable. The parent workflow can seek more evidence, narrow the claim or omit it. A worker forced to return a positive result has an incentive built into its interface to conceal uncertainty.

Typed outputs help enforce the structure. A support status can be restricted to allowed values, required references can be checked, and application validators can reject inconsistent combinations. Pydantic AI supports structured output and output validators. The implication for this design is limited: a well-formed source reference still needs a check that its passage supports the claim. Schema validation cannot supply that semantic judgment on its own. Pydantic AI output documentation
Keep routing separate from the wording of a model's answer. The controller should read an explicit status and policy, rather than search a paragraph for “looks good.” A supported claim with an expired applicability check may route to revalidation. A disputed claim may route to an authorized reviewer. A source-access failure should not be treated as evidence that the claim is false.
Subgraphs package a bounded job for reuse
The evidence check can itself contain several operations: retrieve, extract, resolve identity, compare claims, inspect support and package the result. A parent workflow should be able to call that group through an input/output contract. LangGraph explicitly supports a subgraph used as a node in another graph, with shared state or a wrapper mapping between different schemas. LangGraph subgraphs
The same evidence subgraph can serve a comparison guide, a proposal or a training document. Its callers supply the applicable question and policy. Reuse should preserve the contract while allowing the evidence requirements to differ. A casual internal note and a consequential public claim need not accept the same source quality or unresolved uncertainty.
Keep private intermediate state inside the subgraph unless a parent needs it. Return the evidence packet and references necessary for inspection. Passing every intermediate message into every other worker increases context volume and can blur the distinction between a tentative interpretation and an accepted result. An explicit handoff makes that distinction visible.
Runtime adapters connect the contract to an implementation
A workflow graph describes operations and routing. LangGraph provides state, nodes and edges, including conditional execution. Pydantic's graph facilities provide typed control-flow structures. These are implementation examples, not requirements of the standard. LangGraph Graph API, Pydantic Graph
Visual automation tools also support reusable workflows, code and AI capabilities. n8n, for example, documents sub-workflows, JavaScript and Python code nodes, and workflows using LLMs, agents, tools and memory. The design principles cross tool boundaries, while runtime behavior, testing, access controls and operating constraints still need examination. An input adapter does not make two engines interchangeable. n8n sub-workflows, Code node and AI workflows
Separate the decision about an effect from the adapter that performs it. This follows the functional-core and effect-performing-shell distinction discussed in Objects Are a Position, Not a Religion. An operation can return a proposed action with the required authority, target identifier and version precondition. The effect-performing adapter checks those conditions and records what the destination confirms. This gives tests a way to inspect the decision without performing a real publication or external write.
Recovery deserves an explicit contract too. LangGraph documents that interrupted nodes can restart from their beginning, with earlier effects executing again. A checkpoint therefore does not by itself guarantee one external write. Use durable idempotency protection where supported, preserve destination identifiers and reconcile uncertain writes before retrying them. Record the workflow and contract versions used by suspended work so resumption has a defined compatibility policy. LangGraph re-execution and idempotency
Corrections have to reach the decisions that used the evidence
Updating a source record finishes one repair. The dependent draft, assessment or recommendation may still contain the old claim. Use the preserved relationships to identify what consumed the earlier version. Mark the affected conclusions for rechecking, then record whether the new evidence changes each one.
In the export-guide example, a corrected test condition might invalidate one comparison sentence without invalidating the whole guide. The source record should retain the original test and its correction. The draft history should identify the sentence changed. The earlier assessment stays attached to the text it actually judged, and the revised text receives the required review. The reviewer can then check the repair without reopening unrelated conclusions.
The same path reaches operating decisions. If the missing condition caused repeated rework, the next evidence-checking contract can require that condition before accepting a test result. Preserve the proposed rule change and compare subsequent work under the revised contract. The archive now supplies an identifiable change to test: a particular failure led to a particular requirement, applied to comparable work with its consequences recorded.

Use five lenses to make and test a decision
A map, a promise and a database each answer part of an operating question. A decision requires joining them. The general method is to move through five lenses: the capability map, the commitments, the participants who can respond, the beliefs supported by evidence, and the policy used to choose an action. Then take the proposed action back through those lenses in reverse.
The forward pass builds a decision from the conditions in which the work must happen. The return pass tests whether that decision still fits those conditions. This provides a repeatable way to use strategic ideas without turning every task into an essay about strategy. Each lens should change a choice, establish a necessary condition, or record why no additional analysis is needed.
The first two lenses have already supplied the capability and its dependencies, the result being promised, and the receiver who can assess it. The next three ask what other participants might do, what the available evidence supports, and how to choose among the remaining actions. These questions apply equally to a human team and an agent workflow, although the evidence needed to answer them differs.
Account for the people who can change the result
A plan can be technically executable and still fail because someone else chooses differently. A prospect declines an offer. A reader ignores a headline. A reviewer refuses a handoff. A competitor responds to a new claim. A worker satisfies a narrow completion metric while leaving the intended result unfinished.
Name the participants whose responses could change the decision. For each, record the relevant objective, available actions and information. “The market” is too broad to be useful. “A new visitor deciding whether this product addresses overdue-invoice follow-ups” identifies a particular decision. The visitor can continue, leave, compare an alternative or seek more information. The page has to supply enough relevant evidence to make continuing worthwhile.
Treat those objectives as hypotheses grounded in the situation. A buyer may care about saving time, reducing confusion or avoiding a change in familiar procedures. Research can help determine which matters. The analysis should preserve competing explanations until observations distinguish them, rather than assign motives that conveniently support the proposed offer.
A competitor matters when a plausible response changes the value of the work. If differentiation rests on a phrase any rival can copy, better wording alone may provide little durable advantage. The more useful move could be a narrower audience, a demonstrable capability or evidence a competitor cannot readily reproduce. Conversely, a competitor may have little reason to react to a small experiment. Trace the response that could affect the choice instead of constructing an imaginary contest around every action.
Agents can be examined in the same way without attributing private desires to them. Here, incentives mean the behavior the surrounding process rewards or accepts. If a research agent is judged by the number of sources collected, it may produce a large pile of repetitive material. If acceptance requires answering defined questions with traceable support and identified gaps, the same role has a different completion target.
The resulting action tree shows who can move, what information is available at that point, and which later operations depend on the response. A request for approval is an available action; the approval itself belongs to someone else. A planned audience experiment can be scheduled; its result remains unknown. Keeping those distinctions visible prevents a plan from treating another participant's cooperation as already supplied.
- Our action: request.
- Their action: accept or reject.
- Delivery does not automatically trigger acceptance.
Extend the response analysis only while it can change the choice. If a plausible objection would require a different offer, another source or a smaller commitment, it deserves attention. If an additional speculative branch leaves the same action preferable under every relevant condition, record the uncertainty and proceed. The reasoning consumes resources too.
Make useful behavior easier to assess
The participant lens also improves workflow design. A producer benefits from knowing exactly what the receiver needs and what evidence will establish delivery. A reviewer benefits from a narrow assessment question and an artifact they can inspect. A decision owner benefits from seeing disagreements before they become a public commitment.
Consider a research handoff that returns twelve links with a confident summary. The writer can spend another hour reopening the sources, or trust the summary and inherit its errors. A better contract returns the claim, supporting passage, applicability and uncertainty. The receiving writer can then assess whether the material supports the intended sentence. That change removes duplicated work and makes unsupported interpretation easier to catch.
Evidence of successful delivery has a second use: it helps later participants judge a similar promise. Keep the work, its conditions and the receiver's assessment together. A polished demonstration shows what was produced in that demonstration. A history of comparable accepted work supplies a stronger basis for estimating future delivery. The strength of the signal depends on comparability, not on the confidence with which the producer describes it.
The completion rules should preserve this relationship. An agent that saves a file has completed a storage action. An agent that supplies an inspectable, source-grounded brief has completed a larger obligation. A process that marks both as the same success makes it difficult to learn which capability is actually reliable.
Arrange to see evidence that could change the plan
Before acting, state the belief the action depends on. In the invoice example, one belief might be that buyers value knowing which follow-ups remain outstanding more than seeing another broad promise about efficiency. Another might be that the present evidence is sufficient to write a clear, defensible headline. Those are different claims and need different observations.
Record where each belief came from. Comparable past work, a customer interview, a published study and an unsupported assumption supply different kinds of support. A remembered conclusion needs its origin and scope just as a newly retrieved source does. Otherwise accumulated experience can become a collection of rules whose conditions have been forgotten.
Then ask which observation would distinguish the live explanations. If every candidate fails a claim check, the problem could be an unsupported angle, a generator that ignored the constraints, or a reviewer applying the wrong standard. Another batch of text does little to distinguish them. Inspecting the rejected claim against the brief may identify the cause at much lower cost.
- Possible cause: unsupported angle.
- Possible cause: ignored constraint.
- Possible cause: wrong standard.
- All remain hypotheses; the magnifier means a discriminating check.
Formal Bayesian inference expresses updating through a prior, a likelihood and a posterior. The likelihood asks how compatible an observation is with a hypothesis under the model. Evidence that is similarly expected under competing hypotheses has little power to separate them. These are identifiable modeling commitments, rather than another name for keeping documents. Stanford Bayesian inference notes
For many operating decisions, a qualitative evidence ledger is sufficient. Preserve the original expectation, the observation, the remaining explanations and the action that changes. For a problem with suitable repeated outcomes and a specified model, Bayesian updating can make that record quantitative. The method should match the decision and available evidence.
Arrange for the observation to arrive. A delivery promise cannot be evaluated if the receiver's assessment remains in an unread thread. A headline hypothesis cannot be tested if exposure data cannot be linked to the variant shown. A revision cannot be judged if the system overwrites the baseline before the comparison occurs.
An unresolved outcome remains an open question. It may justify follow-up or a smaller next commitment. Keeping that state visible preserves the opportunity to learn later; filling the gap with an optimistic explanation removes it.
Choose a decision method that fits the work
A decision policy is the procedure used to choose an action from the current situation. It might be a fixed rule, an allocation calculation, a learned function or a search through possible futures. Warren Powell's work provides a useful way to distinguish these methods by what they compute. Powell on policies
Start by writing a small decision model. Powell identifies five parts: state, decision, new information arriving from outside the decision, the transition to the next state, and the objective. Reinforcement Learning and Stochastic Optimization
For a headline operation, the state includes the brief, available evidence, candidates, reviews, remaining time and permitted budget. Available decisions might include generating within an existing angle, researching another angle, submitting finalists, requesting clarification or stopping. New information could be a product correction, a reviewer response or an audience result. The transition records how an action consumes resources and changes what is known or available. The objective concerns the result the receiver needs under the stated constraints.
Writing these elements exposes omissions. A model that tracks candidate count but omits reviewer capacity may recommend generating work nobody can assess. A model that treats audience response as already known will prefer an option using information the operator does not yet have. A model that rewards only immediate output can consistently postpone the research needed for a better offer.
Apply a rule when the relevant condition is already settled
A policy function approximation, or PFA, maps state directly to an action without solving an embedded optimization at the moment of choice. It can be a simple rule or a learned function. Powell on policy function approximations
An editorial example is a rule that returns a candidate to revision when a numerical promise lacks approved supporting evidence. The team has already decided that this condition prevents acceptance. Reopening the entire strategy whenever the condition appears would add cost without improving the immediate decision.
The rule still needs inputs that mean what it expects. A field marked “verified” must identify the check that established it. A source that supports faster identification of overdue invoices cannot satisfy a rule requiring evidence of faster payment. Making the gate deterministic can make behavior consistent; the evidence extraction and claim interpretation still need assessment.
Separate the cost of developing or tuning the rule from the cost of applying it. A learned router can be computationally cheap at runtime even if it required substantial development work. This distinction helps compare alternatives on the timescale that matters to the operation.
Solve an allocation when competing demands matter
A cost function approximation, or CFA, chooses an action through a parameterized optimization. Its adjustable costs, allowances or constraints are tuned to work usefully across situations. Powell on cost function approximations
Suppose several research questions compete for a limited review budget. Each has an estimated decision impact, a resource requirement and dependencies. An allocation procedure could choose a feasible set under the budget, with an allowance for uncertain completion costs. The result depends on the competing choices, rather than a separate rule applied to each question in isolation.
The values used in that calculation need visible origins. Estimated impact can remain a judgment, but it must be marked as one. Otherwise a numerical optimizer gives an undocumented preference the appearance of measured precision. Sensitivity checks can show whether a small change in an uncertain estimate would reverse the allocation.

A fixed lookup that routes every product brief to a particular model is still a direct rule. Calling its settings “dials” does not make it an optimization. The distinction helps the operator understand which computation runs, what it needs, and where an unexpected choice could come from.
Estimate future value when today's work changes later capacity
A policy based on a value function approximation, or VFA, includes an estimate of the value of a future state in the present choice. Powell on value function approximations
A team may have to choose between finishing one more deliverable and repairing a recurring evidence-mapping failure. The repair consumes capacity now. Its expected value depends on how many later tasks use the same path, what the failure costs them, and whether the repair will actually reach those tasks.
Name those future uses. A reusable claim-checking component is more valuable when a queue of comparable work already needs it than when its only justification is an unspecified future scale. Include maintenance and migration costs as well as the anticipated savings. A component that creates a second incompatible record format can make later work harder even if it speeds up the current demonstration.
A qualitative comparison may be sufficient to make the investment decision. A formal VFA implementation requires the corresponding model and estimation procedure. The useful operating habit is to state the future benefit, the evidence behind it and the work being forgone now. That makes the investment testable after the future work occurs.
Model paths when their order changes the commitment
A direct lookahead approximation, or DLA, chooses a present action by evaluating an explicit model of future decisions and outcomes over a planning horizon. Powell on direct lookahead
For a content operation, an explicit path might compare researching an unfamiliar audience before committing to a campaign with starting from existing material and correcting later. The paths have different costs, delays and points at which new information becomes available. Modeling them can reveal that an apparently cheap start creates an expensive commitment before the most important uncertainty is resolved.
Use observed inputs where available and label assumptions elsewhere. Include delayed feedback, failed actions and scarce human review. A simulation that assumes immediate perfect feedback may select a policy that cannot work in the real process. Vary assumptions that could reverse the choice instead of decorating a single preferred scenario with more detail.
Act on the next authorized step, observe what happens, and replan from the updated state. The model supports a sequence of decisions; it does not eliminate the information arriving between them. Keep simulated outcomes distinct from observed outcomes so later analysis can test whether the model transferred.
Take the proposed action back through the lenses
Once a method selects an action, return through the reasoning in reverse. Begin with the action, then inspect the beliefs it relies on, the responses it invites, the commitments it creates and the capabilities that must support them.
For the headline example, suppose the chosen action is to run another generation pass. The belief check asks what this pass is expected to resolve. If the missing information concerns buyer motivation, generating more language may leave the actual uncertainty untouched. The participant check asks whether a reviewer or decision owner can use the additional variants. The commitment check identifies who will assess them and when. The map check confirms that the necessary evidence and review capability exist.
This return can change the action before more work is spent. The better next step might be a targeted research question, a clarification about the audience or a smaller shortlist built from existing candidates. The selected decision method earns its place by helping make that distinction.
After execution, repeat the return with observed results. Preserve the original expectation beside the outcome. A missed deadline may arise from an underestimated task, an unavailable dependency or an unaccepted handoff. Those causes imply different repairs. A capability can remain in the same evolutionary position while its effort estimate changes. A source correction can improve a decision without requiring a new architecture.
The forward and reverse passes therefore localize learning. They show which belief, commitment, method or map entry needs revision and which can remain intact. More analysis is useful when it changes one of those decisions. Once the relevant choice is supported, the next obligation is to act and obtain the result.

Use a capability lens to choose what to build next
The five decision lenses organize a choice. A different lens helps inspect the capabilities available to the operation. Lewis Jackson's 7 Levels of AI Trading offers a useful starting lens. His explanation moves through conversational assistance, executable rules, historical testing and costs, learning from examples, source research, portfolio-level risk and connected agent roles. He repeatedly connects each new capability to an additional test or operating responsibility. Lewis Jackson
Applied to other work, those capabilities raise a series of practical questions.
| Trading lens | A question for an operational system |
|---|---|
| Prompt guessing | Are we asking for an answer without specifying how it should be developed or checked? |
| AI-written scripts | Can we express the work as a repeatable process with explicit inputs and outputs? |
| Backtesting and costs | Can we evaluate results and account for the resources consumed? |
| Machine learning and regimes | Can we detect conditions in which a previously useful approach stops working? |
| Research and alternative data | Can we improve the evidence and assumptions the process draws on? |
| Portfolio construction and risk control | Can we allocate limited resources across alternatives while containing losses? |
| Autonomous multi-agent systems | Can specialized systems cooperate through dependable handoffs? |
The six intelligence-stack responsibilities describe the information path, while these capabilities describe different things a system can do. They can develop separately. A small deterministic workflow may be the right solution for years. An operation can have excellent research and poor cost accounting, or sophisticated agents and weak acceptance criteria. Choose the next capability according to the constraint on the work.
- Prompt guessing.
- AI-written scripts.
- Backtesting and costs.
- Machine learning and regimes.
- Research and alternative data.
- Portfolio construction and risk control.
- Autonomous multi-agent systems.
- Proposed extension: evolutionary operations.
- Seven video capabilities plus the article-authored extension, not a mandatory staircase. Risk and authority apply throughout. The illustrated tool shapes have no assigned scientific meanings.
Risk controls apply throughout this progression. Jackson explicitly explains that the portfolio stage adds attention to how positions affect each other, while limits were needed from the beginning. Jackson at 8 minutes
The fourth row concerns a different distinction. A market regime is a description of conditions under which relationships or behavior differ. Detecting a change in conditions is distinct from improving a system. In an editorial operation, a different audience, distribution channel or level of subject familiarity may change which headline works. Monitoring should help identify those differences before a team treats all movement in results as evidence that its latest prompt was better.
An eighth capability proposed here extends the framework to evolutionary operations that propose and test changes to their own procedures. Evaluation, authority and version control keep a promising modification separate from an accepted replacement.
Bring quantitative testing discipline into creative work
Quantitative marketing is a useful name for an approach that combines creative hypotheses with explicit evidence, cost accounting and outcome measurement. It leaves room for strategic judgment while making the consequences of that judgment easier to compare. A team can investigate which angle is worth developing, how much to spend on it, and whether the resulting work helped the intended audience take the intended action.
The relevant transfer from quantitative trading concerns how to test a proposition under operating constraints. A historical pattern, a polished backtest or a winning score can each be misleading for different reasons. JJ Simon describes how searching many variants on the same data can produce an attractive winner while an incomplete search record hides how that winner was found. Later, he distinguishes evaluation environments from actual external outcomes and explains how different operating constraints change the objective. These observations transfer directly into questions about search history, acceptance and context, without importing his financial claims into a marketing result. Simon on repeated tests and evaluation versus outcomes
A seven-pattern framework in Unified Architecture identifies look-ahead bias, survivorship bias, overfitting, transaction-cost error, regime ignorance, capacity error and distributional misspecification. These are the author's cross-domain organizing categories. The marketing examples below apply that framework to agent work; their value is in locating different failure mechanisms and choosing a corresponding control. Unified Architecture
Preserve the information available at the time
Look-ahead bias enters a replay or backtest when the decision procedure receives information that was unavailable at the decision time being simulated. A team may reconstruct an old headline test using a corrected product brief or a customer insight collected after the campaign. The reconstructed system then appears to have made a choice it could not have made from the evidence available then. Evaluating an earlier forecast against a later outcome is legitimate; the error is giving that outcome to the procedure before it chooses.
Keep event time, information-availability time and decision time distinguishable. Preserve the brief and evidence snapshot used for the original decision. A later correction can improve the next attempt while leaving the earlier record intact. This allows a fair question: given what was available then, was the choice reasonable?

Retain the attempts that disappeared from the final portfolio
Survivorship bias appears when learning draws only from published work, successful clients or completed runs. The operation sees what remained and loses the cost and characteristics of what failed. A library of excellent final headlines can conceal the rejected angles, abandoned research and human rescues required to produce them.
Define the population whose results inform the next estimate. Keep rejected, canceled, interrupted and unresolved attempts, with their different statuses. A cancellation caused by changed scope differs from a technical failure, but both may matter to resource planning. The final portfolio can remain selective while the operating record remains complete.
Separate broad search from confirmation
Overfitting becomes a concern when a system repeatedly adapts to the same evaluation material. A generator can learn to satisfy a particular judge's preferences. A team can test many variants, select the luckiest-looking one and overstate its expected effect. Research on two-stage online experiments distinguishes screening from validation partly to address selection and winner-related bias. Deng, Li and Guo
Retain the search history, keep some cases outside development, and confirm important claims under an appropriate independent comparison. The number of candidates explored belongs in the record. A winner selected from a large search requires a different interpretation from a single prespecified comparison.
Count the whole cost of reaching acceptance
Transaction-cost error has an operational analogue whenever a calculation counts model generation and ignores the work around it. Research, retrieval, review, correction, coordination, deployment and human rescue all consume resources. A cheap candidate that requires extensive repair can cost more than a carefully grounded first pass.
Attach costs to attempts, including the unsuccessful branches. Track time and service spend in their actual units. Token usage can help explain model cost; it is not a measurement of electricity consumption. If energy matters to the decision, use measured consumption or a clearly stated estimation model appropriate to the infrastructure.
Record the conditions in which a method works
Regime ignorance appears when an approach is carried into changed conditions without examining applicability. An angle effective for returning customers may confuse a first-time visitor. A message that works in a search advertisement may fail in an email subject line. A product change can make an old claim obsolete.
Context detection, drift detection and improvement are distinct operations. The first can route a known type of work to an existing procedure. The second identifies changes worth investigating. Adaptation changes the procedure and tests whether the change helps. Record the audience, channel, offer, timing and other conditions that could explain a result before attributing all movement to a revised prompt. Concept drift review
Test the bottleneck at the proposed scale
Capacity error appears when success at a small volume is assumed to survive a much larger one. Generating more candidates can overwhelm review. Publishing more messages can exhaust audience attention. A successful promotion can create fulfillment or support work the business cannot absorb.
Measure the whole path at the tested scale and identify the next constraint. A team with ten times the generation capacity may gain little accepted throughput if one decision owner still has to reconstruct every handoff. The next useful investment could be clearer evidence packets, a better sampling procedure or another qualified reviewer.

Examine consequential variation rather than only the average
Distributional misspecification appears when the model of outcomes hides variation that matters to the decision. A high average quality score can conceal rare unsupported claims. An average response rate can conceal poor results for an important audience segment. A convenient assumption about errors can understate the chance of an expensive failure.
Retain the relevant distributions, extreme cases and subgroup context. Choose measures that expose the failure the operator needs to control. A single composite quality number makes a poor substitute when one factual defect can invalidate an otherwise polished deliverable.
These seven checks lead to different repairs. A stale audience assumption calls for an applicability review. Hidden review costs call for better accounting. A leaked evaluation set calls for a new validation design. Treating every failure as “the model needs a better prompt” erases the distinctions that make a correction useful.
Work through the headline search
A concrete headline process makes the architecture easier to inspect. The following example is illustrative. Its candidate counts describe one possible exploration budget, not a validated formula or a requirement for every piece of copy.
Suppose a small software company wants a landing-page headline for a tool that helps service businesses track overdue invoices. The objective is to attract appropriate prospects without promising results the product cannot guarantee. The approved product evidence establishes that users can see overdue invoices and record follow-up activity. Customer research suggests that some buyers struggle to know which follow-ups are still outstanding, but the sample is too limited to estimate how common that problem is.
That evidence changes the search. “Get paid twice as fast” would require support the brief does not contain. A message about visibility or follow-up control is more defensible. The team still has to decide whether either angle is important enough to lead with.
Establish the objective and the angles
Before generating headlines, specify the audience, the desired response, the available space and the claim boundaries. Is the headline meant to help a qualified visitor recognize the product, encourage an article click, or distinguish an offer from alternatives? A candidate can be effective for one purpose and poor for another.
Then identify materially different hypotheses. One angle might emphasize seeing overdue work clearly. Another might emphasize coordinating follow-ups between team members. A third might emphasize reducing the need to reconstruct activity from scattered notes. Each angle needs its own support and a reason to believe the reader might care.
If the evidence supports only the first angle, the system should say so. It can propose research for the others rather than quietly treating plausible language as established product value.
Explore broadly enough to reveal the failures
After choosing an angle for the assignment, a first pass might generate around 100 candidates across meaningfully different expression strategies. Other viable angles can remain explicit alternatives if the selected one fails. The purpose of that breadth is to discover useful possibilities and expose patterns. One hundred synonyms for “streamline your invoicing” provide little additional information.
Label candidates by the hypothesis they express, the evidence they depend on and the intended reader response. Variation might concern specificity, reader awareness, emphasis, tone or the relationship between a headline and its supporting line. It should not be measured only by different words.
Early screening can remove clear violations: unsupported claims, factual errors, unreadable constructions and failures to fit the placement. Keep the rejected examples and reasons in a compact form. If most candidates promise faster payment without support, the failure points to the generation instructions or the angle brief. Asking for another hundred without addressing that cause would repeat the expense.
Use the findings to build a better second round
An evidence-reviewed set of perhaps 20 to 30 candidates can combine survivors with new work informed by the first pass. This is more useful than merely taking the highest-scoring quarter of the original list. A rejected candidate may contain a promising idea expressed badly. A polished survivor may depend on the same weak assumption as ten others.
The next brief should state what changed. For example: retain the visibility angle; avoid implying payment acceleration; make the action a buyer can take concrete; stop using grandiose control-room language; distinguish individual use from team coordination where the evidence allows it.
A candidate such as “See which invoices need a follow-up” may now be worth keeping because it states an inspectable function in familiar language. That does not establish that it will win. Its weakness may be that it sounds ordinary or fails to explain why this product is preferable. The review should preserve that objection rather than convert a defensible claim into a performance prediction.
Narrow through comparison and challenge
A further round might produce five to twelve serious contenders. Review them against the same objective and claim boundaries, with short reasons tied to the text. Ask what each candidate does better than its nearest alternative, what it gives up, and which uncertainty remains.
Then select perhaps three to five finalists that preserve meaningful differences. A shortlist containing the same promise in five sentence structures leaves the eventual test with little to distinguish. A shortlist can instead retain competing views of what the audience needs to notice first, provided each is grounded.

For every finalist, retain the angle, evidence, main objection and selection rationale. “This scored 8.7” is less informative than “This names the overdue-invoice problem directly, stays within demonstrated functionality, and sacrifices some distinctiveness for immediate comprehension.” Scores can support sorting. They should not replace the argument.
Allow a return to the brief
Sometimes no candidate is good enough. The system needs a route other than forced selection. It may request better product evidence, reconsider the audience, revise the offer or ask a human to resolve a strategic ambiguity. A weak set can reveal a weak underlying proposition.
When a deadline requires choosing, preserve the distinction between “best available under the present constraints” and “validated as effective.” A team can make a provisional decision without laundering necessity into confidence. It can also offer additional exploration as a bounded choice: another research pass, a new angle, or a small test, with the likely information gain and cost made explicit.
The resulting record is richer than a final headline. It explains what was tried, why options failed, which tradeoffs survived and what evidence could change the choice. That record gives the next project a starting point while leaving room for a different audience to produce a different answer.
Preserve the difference between a repair and a new hypothesis
The iteration record should identify the parent candidate and what changed. Replacing a vague noun with a concrete action is a wording repair. Changing from individual visibility to team coordination is a change in the promise being investigated. Adding a numerical outcome is a claim change that may require new evidence. These moves have different costs and should take different routes through the graph.
An illustrative review log could contain the following entries. These are invented examples for the fictional product, not measured audience results.
| Candidate | What the review establishes | Useful next action |
|---|---|---|
| Get paid twice as fast | The evidence contains no payment-speed comparison | Reject the claim or commission appropriate research |
| Streamline your invoicing | The promise is broad and leaves the product's relevant function unclear | Replace the abstraction with an observable action |
| See which invoices need a follow-up | The wording matches the demonstrated visibility function | Retain and test whether the audience finds it important |
| Know the next step for every overdue invoice | The wording implies guidance and completeness beyond the supplied evidence | Narrow the promise or establish those capabilities |
A failed candidate can contribute a useful diagnostic without contributing usable copy. The first row identifies a claim boundary. The second identifies an expression failure. The fourth suggests a product question. Recording all three as “bad headline” would lose the difference and encourage a generic rewrite.

The second round should therefore be generated from a changed brief, not simply from the first round's highest scores. It might retain the visibility angle while asking for greater specificity, shorter syntax and clearer distinctions between seeing a problem and resolving it. A request to “make it more compelling” leaves those choices implicit and may invite the unsupported promises the review just removed.
The same principle applies when the system changes its own instructions. If a recurring rejection suggests a new rule, preserve the cases that motivated the rule and look for cases it might harm. Banning all outcome language would remove unsupported guarantees but could also eliminate a well-supported benefit in another brief. A local repair should retain the condition that made it necessary.
Make the final comparison understandable without the generator's sales pitch
A finalist packet should let a decision owner understand the choice without reconstructing the tournament. Include the objective, selected angle, exact text, supporting evidence, main objection and nearest credible alternative. Show which failures have been ruled out and which uncertainties remain.
The headline and supporting line also need separate tests. Read the headline alone and ask what a reader could reasonably infer about the subject and promise. Then read the pair and ask what the supporting line adds. A subheadline can add specificity and scope; it should not be required to rescue an unintelligible main line. Check the actual placement as well, because a line that works in a document can become confusing when wrapped on a small screen.
Have an independent judge make the initial assessment before seeing the generator's ranking or rationale. Preserve that first assessment. The rationale can then be revealed and challenged, allowing the reviewer to distinguish a sound argument from a persuasive explanation attached after selection.
A finalist may still be rejected because the underlying offer is weak. That result should reopen the appropriate decision rather than trigger indefinite polishing. If the product's meaningful difference cannot be expressed from the evidence, the next useful work may be product research or positioning, not another word choice.
Measure the audience result at the level the decision needs
After exposure, headlines can produce quantitative observations. A team might measure qualified clicks, trial starts, completed purchases or another outcome tied to the page's purpose. It can also monitor misleading expectations, unsubscribes or downstream support burden. The metric should reflect the actual objective rather than the easiest event to count.
A causal A/B test requires randomized assignment of the chosen units to variants, along with a baseline or incumbent, an outcome window and an analysis plan. When randomization is unavailable, an observational comparison needs its causal assumptions stated and cannot automatically establish lift. The information needed depends on baseline rates, variability, the smallest useful effect, allocation and the cost of mistakes. Repeated comparisons and repeated inspection of results affect how evidence should be interpreted. A fixed-horizon design or a suitable sequential procedure should be chosen accordingly. Practical Guide to Controlled Experiments on the Web
The three to five finalists are candidates for testing, not an instruction to divide every small audience among five simultaneous treatments. Available traffic and decision stakes may favor screening first, comparing fewer variants, or gathering qualitative evidence about a narrower question. A thin experiment should return an uncertain estimate instead of a ceremonial winner.
Record the exposure result against the exact candidate and context. If a clear headline attracts more qualified visitors but produces fewer total clicks, the primary objective determines how to interpret the tradeoff. If a stronger click rate is accompanied by disappointed users, the result may indicate that the promise exceeded the delivered experience.

The loop ends with a decision: retain, revise, investigate further or stop. Its record should show what changed because of the observation. That is the point at which an evaluation becomes useful to the next attempt.
Evaluate the work and the evaluator
A useful evaluation specifies its object. The object might be a claim, a headline, a research packet, a complete task or the resulting state of an external system. An assessment of one should not silently resolve the others. Anthropic's agent-evaluation guidance distinguishes a trial's transcript from its actual outcome: what an agent says it accomplished and what changed in the environment require different checks. Demystifying evals for AI agents
Match the check to the claim. A length limit can be checked deterministically. Source support requires inspecting the relationship between a statement and its evidence. A visual artifact needs inspection in its rendered form. A claim about audience behavior requires the relevant audience observation. Combining these checks can provide a stronger assessment than assigning every question to the same judge.
The evaluator also needs tests. Research on LLM judging has documented position, verbosity and self-enhancement biases alongside useful agreement with human preferences in the studied benchmarks. This supports examining the judge's behavior under changed ordering and checking its judgments against qualified human review. It does not establish that an agent preference predicts a particular audience's conversion behavior. Zheng and colleagues
For the headline tournament, anonymize candidates and vary or swap their order where useful. Give the judge the objective and approved evidence. Collect its assessment before revealing the generating agent's preference. Retain both the decision and the specific passage or criterion behind it. A disagreement can then be investigated instead of reduced to a vote count.

Two agents using similar models and context can share a blind spot. Their separate names provide organizational separation, not independent ground truth. A human can also overlook a claim or reward a familiar style. The practical response is a mixed evaluation design with explicit objects, relevant evidence and calibration on the actual work.
Use a five by five rubric to keep defects distinct
A five by five rubric contains five relevant categories and five defined ordinal levels for each. The categories should represent different obligations. A research brief, a headline and a software change need different definitions even if the same rubric format is reused.
The following example is an authored operating rubric for an evidence-backed knowledge-work deliverable. It illustrates the structure rather than declaring universal quality criteria. Level four is ready for the agreed acceptance decision. Level five requires additional demonstrated evidence; it is not a standing instruction to keep polishing after the work is ready.
| Category | Level 1 | Level 2 | Level 3 | Level 4 | Level 5 |
|---|---|---|---|---|---|
| Purpose and fidelity | Requested result is absent or contradicted | Some requested elements appear, with major scope errors | Core request is met but a material ambiguity remains | Agreed result and scope are satisfied, with exclusions explicit | Level four plus successful use in an additional relevant setting |
| Evidence and accuracy | Consequential claims lack support or contain known errors | Some support exists, with important gaps or mismatches | Support is mostly adequate, but a defined correction remains | Consequential claims are supported and limitations preserved | Level four plus independent corroboration or replication where appropriate |
| Decision quality | Choice has no inspectable basis | A reason is supplied without examining a consequential alternative | Relevant alternatives are considered, with an unresolved tradeoff | Choice follows the criteria and evidence, with tradeoffs recorded | Level four plus later evidence confirms the reasoning's useful prediction |
| Usability and handoff | Receiver cannot access or use the result | Result opens but requires substantial reconstruction | Result is usable after specified minor repairs | Receiver can use the result and inspect its evidence without reconstruction | Level four plus demonstrated reuse by another qualified receiver |
| Execution and boundaries | Required checks or authority conditions were violated | Execution record omits material steps, effects or costs | Most conditions are met, with a documented closure gap | Required checks, costs, versions and authority conditions are established | Level four plus repeat delivery under comparable constraints |
Award a level only when its stated conditions are met. Use whole levels and report the five values side by side. Do not let a strong style or usability score compensate for an unsupported consequential claim through a weighted average. Define the acceptance rule before reviewing the work, including any permitted exception and who may accept it.

A score must link to the exact output version, rubric version, evaluator and evidence. If a sentence changes after assessment, the relevant check needs to be repeated on the new text. A copied score from an earlier version can give a revision an acceptance it never received.
Compare reasons when people and agents disagree
Have a person and an agent assess the same work independently against the same definitions. Read the disagreements by category before adjusting the numbers. The agent may have missed evidence, applied an irrelevant criterion, interpreted a requirement differently or treated a plausible claim as established. The human may have done the same.
A useful repair changes the cause. If a criterion rewards decorative completeness instead of the receiver's actual job, revise the criterion and version the rubric. If the criterion is sound but the evaluator overlooks a required condition, improve the evaluator's instructions and test it on comparable cases. Merely changing the score to match the human loses the lesson.
Agreement also needs interpretation. Two assessors can award the same level for different reasons. A short reason tied to the artifact makes that visible. Keep unresolved disagreement where it could affect acceptance, especially when it concerns a strategic tradeoff rather than a clear factual defect.
A lower score is useful when it identifies the next repair. A high score is useful when its evidence supports proceeding. Either becomes bureaucracy if it cannot change an action.
Keep forecasts separate from quality scores
A rubric level evaluates delivered work against criteria. A forecast assigns a probability to a specified event before its outcome is known. “This brief meets level four for evidence” and “there is an 80 percent chance this brief will be accepted without rework by Friday” are different records. The first needs an artifact and criteria. The second needs a resolvable event, a deadline and a later observation.
Write the forecast so another person can resolve it. Identify the receiver, the relevant output, what counts as rework and where acceptance will be recorded. If the receiver has not yet responded, the result remains unresolved. Treating silence as success would change the event after the prediction was made.
Calibration concerns the relationship between forecasts and observed frequencies across a collection of predictions. A forecaster who repeatedly assigns a probability near 80 percent should, over suitable repeated cases, see the event occur at roughly that rate. One successful forecast provides no such calibration curve. Proper scoring rules support evaluating probabilistic forecasts against outcomes. Gneiting and Raftery
For a binary event, one common Brier-score convention averages the squared difference between the predicted probability and an outcome coded as zero or one. An 80 percent forecast produces a squared error of 0.04 when the event occurs and 0.64 when it does not. This makes a confident miss more costly than a tentative miss under that score. Scikit-learn Brier score documentation
The arithmetic does not decide which tasks are comparable. A forecaster can appear to improve by switching to easier questions. Preserve the questions, conditions and task mix so comparisons can be made on the same cases or a defensible reference set. Also examine whether the forecasts distinguish stronger prospects from weaker ones. Assigning the same cautious probability to every task may avoid dramatic mistakes while contributing little to allocation.
Quality and probability can disagree legitimately. Excellent work can emerge from a weakly justified forecast. A reasonable forecast can miss. The repair should address the appropriate object: the deliverable, the evaluator, the prediction method or the estimate of work required.

Update the unit only where the evidence applies
An accepted result can strengthen the next estimate when its conditions are comparable. A result completed with extensive human rescue supports a different capacity claim from an unaided completion. Preserve both rather than excluding the rescue from cost or treating it as evidence that the original automation was self-sufficient.
A missed estimate needs a cause. The task may have been larger than expected, a source may have been missing, a dependency may have failed, or the acceptance criteria may have changed. Increasing every future allowance would hide these distinctions. A missing permission is not solved by reserving more tokens. A misunderstood claim is not solved merely by adding another reviewer.
State the correction narrowly. For example, future research packets in this domain require a source-version check before writing begins; estimates now include that operation. Or this class of brief needs an early receiver review because late clarification repeatedly caused rework. The revised estimate cites the attempts that support it and retains the earlier estimate for comparison.
Then test the correction in the next comparable run. A new instruction is an intervention, not an observed improvement. If the expected failure disappears but another cost rises, preserve the tradeoff. If the evidence is inconclusive, continue using the best-supported procedure while keeping the question open.
Use new evidence to improve the questions available
Research expands what a system can investigate. Customer interviews may reveal a problem the existing brief never named. Support records can expose a misunderstanding that confident copy would amplify. Product demonstrations can establish a narrower but more defensible promise. Academic research can suggest a mechanism worth testing in the actual setting.
The evidence map keeps these contributions distinguishable. A published experiment can support a causal effect within its design. An interview can expose a hypothesis or explain a particular person's experience. Operating data can show a pattern while leaving its cause unresolved. A team gains more from matching evidence to the question than from ranking every source on a single scale of prestige.
Alternative data is useful when it observes something relevant that the standard record misses. For a content operation, that could include where readers stop, which questions a sales team repeatedly answers, or which claims trigger support corrections. Collection still needs an appropriate basis, permissions and context. More data becomes useful through a decision it can change.
A research node should therefore return the question, findings, applicability, conflicting evidence and remaining uncertainty. It should also identify whether the new information changes the current action. If a finding merely repeats an existing source, the record can preserve the relationship without inflating the apparent number of independent observations.
The expanded capacity to ask questions is the economic promise of the learning factory. Once retrieval, evidence review and handoff become reusable operations, the team can afford a more targeted investigation before committing to an angle. The gain should be assessed through the resulting work and resource use. A larger research archive alone does not reveal whether decisions improved.
Allocate a portfolio of investigations
A team usually has more plausible questions than it can fully investigate. It can devote the whole budget to polishing the first promising angle, spread its attention thinly across everything, or allocate effort as evidence arrives. A portfolio view makes that choice explicit.
In the headline example, inexpensive exploration can examine several angles. A selected angle receives a broader expression search. Promising alternatives remain available if the leading approach fails. Deeper evidence review and audience testing receive separate budgets because they answer different questions and consume different resources.
Preserve diversity at the level of hypotheses. Ten agents proposing versions of the same unsupported promise do not provide ten independent opportunities. Record shared assumptions and evidence dependencies so the portfolio shows where many apparent alternatives could fail together.

Resource allocation should also include the cost of being wrong. An internal draft is easy to replace. A misleading public claim can create customer expectations and downstream work that survive after the wording changes. A test that spends a small amount of media budget can still be expensive if it directs unsuitable prospects into a constrained service operation.
A useful allocation record states what each investigation could change, what evidence it is expected to produce, and when further work would stop being worth its cost. The system can then transfer resources from exhausted wording variations to a better-supported question. That is a practical way for more capable automation to increase useful exploration rather than merely increase output volume.
Give specialists responsibilities they can finish
Specialized cooperating systems become valuable when different parts of the work require different tools, context or acceptance rules. A researcher retrieves and qualifies evidence. A writer develops angles and expression. An evaluator challenges candidates. An operator maintains versions, budgets and handoffs. A decision owner resolves tradeoffs and authorizes consequential action.
The design starts with those responsibilities, then chooses whether each needs an agent, deterministic code, a human or a combination. A specialist role should be judged by the work it can reliably finish. Calling an agent an expert does not establish the relevant capability; a tested task record can.
Give each role a focused input and a bounded result. The research node returns an evidence packet tied to the brief. The writing node returns candidates and their claim references. The evaluation node returns decisions, reasons and unresolved disagreements. The receiving operation can request additional context when a particular gap matters.
Broadcasting every conversation to every participant makes coordination harder. It increases the material each role must interpret and can spread an early mistaken assumption through the whole team. A compact artifact with provenance and explicit limitations gives the receiver a clearer starting point while preserving access to the underlying record.
- Evidence inspection.
- Composition.
- Evaluation.
- These are responsibilities; each depicted specialist is not necessarily an autonomous agent. The compact artifact retains reachable deeper evidence.
Conflict needs a route. If the writer considers a promise essential and the researcher finds no support, the system can return to research, narrow the promise or ask the decision owner to choose a different angle. It should preserve the disagreement and resolution. Silently editing the evidence to accommodate the copy would make later review unreliable.
Parallelism follows dependencies. Several agents can investigate independent evidence questions at once. An evaluator of the final text must wait for that text to exist. A visual producer can research possible forms early, while final scene design depends on an accepted manuscript and its actual explanatory needs. Running a dependent stage too early produces rework; running independent stages serially wastes available capacity.
This also requires a coordination owner. Someone must preserve the task's scope, decide which conflicts need escalation and determine whether the assembled outputs satisfy the receiver's result. A collection of locally completed subtasks can still leave a gap at their interfaces. The coordinating role owns checking those connections.
Authority belongs in the same contract. Researching, editing an internal draft, changing an operating procedure and releasing work publicly are distinct actions. Each node should know which it may perform and when it must return a proposed result for acceptance. This keeps a reusable specialist useful across settings with different permission boundaries.
Anthropic's engineering guidance distinguishes predefined workflows from agents that dynamically direct their own processes and recommends adding complexity when it serves the application. Applied here, a specialized system earns its place when it improves a measured responsibility or handoff enough to justify its coordination cost. Building effective agents
Let operating records support evolutionary changes
The evolutionary extension begins when a system can inspect its operating record and propose a change to how work is done. It might find that most rejected headlines fail the same claim check, suggest moving that check earlier, and construct a revised workflow for comparison. It might propose a different retrieval query, a narrower generation brief or a new allocation between research and review.
Keep the proposal separate from the accepted procedure. Record the parent version, the modification, the failure it addresses and the expected effect. State which other behavior could regress. Moving a check earlier may save generation cost while rejecting rough ideas that would have become useful after development. The evaluation needs to examine both sides.
Variation, selection and retention can operate over prompts, graph structure, tool choices, component combinations or resource settings. GEPA provides a concrete research example of reflective prompt evolution using execution trajectories, proposed changes and evaluation. Its benchmark results establish that this is an active technical approach. A new application still needs an objective and evidence relevant to its own task. GEPA
A fair comparison preserves the baseline and evaluates candidates under suitable common conditions. Development examples reveal how to improve the procedure. Held-out cases test whether the change extends beyond the examples that shaped it. Repeatedly consulting the holdout can turn it into another development set, so the evaluation history needs to show which information influenced which revision. Dwork and colleagues
Jackson makes a related distinction when he describes proposed improvements passing checks and required approval before replacing an earlier version. Jackson on replacement approval
The acceptance procedure must remain outside the candidate's authority to redefine success. A proposed workflow should not be able to weaken its own claim checks, remove hard cases and announce an improvement. Promotion can depend on independently maintained tests, qualified human review, real operating outcomes or a suitable combination.

Use composition to build a bounded simulation
The entity and component model described earlier provides a practical foundation for simulation. A candidate, task or resource retains its identity while systems update selected data. A simulated review queue can use the same definitions of ready work, required evidence, reviewer capacity and acceptance state as the live workflow.
Start with a particular decision. For example, should a team add a review specialist, reduce candidate volume or move a deterministic check before human review? Define the initial queue, permitted actions, transition rules, arrival assumptions and outcome measures. Include waiting time, missing evidence, failed actions and correction work wherever they can change the result.
Then compare the policies. One might review every candidate in full. Another might screen hard failures first and send ambiguous cases to a person. A third might preserve more candidate diversity while reducing repeated wording variations. The simulation can expose which assumptions make each policy attractive and which bottleneck limits the expected benefit.
A world model describes expected consequences of actions. Its credibility comes from comparison with observations at the level the decision needs. A model of review time can be checked against review records. A model of audience response needs audience evidence. Simulated customers who share the generator's assumptions can suggest hypotheses, but their preferences remain simulated observations.
Keep the simulation's outputs in a separate evidence class. A chart showing projected throughput should retain the model version and assumptions. When a limited live trial becomes appropriate, compare its observations with the predictions made beforehand. A useful mismatch identifies where the model needs revision.

This process can use evolutionary search without training a model through reinforcement learning. Reinforcement learning concerns learning behavior through interaction and reward to improve expected return. Prompt revision, graph search and workflow selection may change the operation while leaving the underlying model parameters untouched. Name the mechanism actually used so the reader knows what evidence would establish improvement. Sutton and Barto
Promote a change at the level its evidence supports
A candidate that improves a narrow test may deserve a limited trial rather than immediate use across every task. Identify the contexts in which it was evaluated, preserve a rollback route and watch the outcomes that could reveal a regression. A change to writing instructions can be reversed quickly; correcting an external action may require a different recovery plan.
Retain rejected changes too. Their records prevent the same attractive but unsuccessful idea from being rediscovered without its history. A rejected change can become relevant when the context changes, so preserve the reason for rejection rather than attaching a permanent label of failure.
The endpoint is an accepted revision with a known scope, evidence and owner. The next task then uses that revision and supplies another observation. This is how a working system can improve its own operations while remaining connected to results outside its own explanations.
Turn conversation into a map someone can correct
Useful context rarely arrives in the order an operating system wants to store it. A person may describe a frustrating result, mention a possible tool, recall an earlier attempt and add a constraint halfway through the explanation. An agent can turn that material into a structured draft without requiring the person to complete a long questionnaire first.
The intake operation should preserve the original conversation and distinguish what the person said from what the agent inferred. A requested outcome, an example, a preference and a firm constraint have different effects on the commitment. Treating every mentioned idea as an instruction can enlarge the scope without the person's agreement.
Start by extracting the person served, the problem, the observable result, known constraints and the decisions still open. Attach each proposed field to its source passage where possible. Mark derived values as inferences or estimates. An unknown field remains unknown until evidence or a decision supplies it.
A form, transcript, import and agent research result should feed the same identified record through their adapters. The person can answer a few questions directly and let the agent assemble the rest from available context. A later correction updates the relevant field while preserving the earlier interpretation and its origin. The system can then learn which inferences repeatedly required correction.
Ask questions that change the commitment
A useful intake question changes an action, resolves a consequential ambiguity or helps establish whether the work is a fit. “Who will use this brief to decide what?” can change the research and format. “Which claims must be supported before release?” changes acceptance. A request for information already stated clearly in the conversation consumes attention without improving the record.
Prioritize questions by their consequence. A missing audience may block writing because it changes the whole angle. A preference for a particular visual treatment may remain open while evidence research proceeds. A choice about publication authority can wait until the release step if earlier work is independently authorized and useful.
Present the draft map so the person can confirm, edit or leave fields unresolved. Show the proposed answer beside its basis when the inference matters. This lets someone correct the interpretation directly instead of retelling the whole situation. It also makes the remaining question more specific.

Skipping a question records that it remains unanswered. It does not turn an estimate into an instruction. The next operation can proceed with a stated assumption when the uncertainty is non-blocking and reversible, or wait when the missing decision determines the commitment itself.
The intake result is a usable starting record with known gaps, not a claim that all uncertainty has been removed. Its receiver should be able to identify the next action and the conditions that still govern it.
Make the offer fit the delivery record
The same mapping discipline changes what a team can promise to a customer or an internal sponsor. A demonstration supplies inspectable evidence of a particular capability. A history of accepted work supplies information about repeatability, cost and the conditions required for delivery.
A proof package should connect each claim to something the receiver can examine. If the claim concerns a research brief, show a brief and its evidence trail. If it concerns a reusable workflow, show the inputs, result and relevant checks. If it concerns reliable delivery, include comparable attempts and the work required to reach acceptance.
A finished artifact can conceal a labor-intensive path. Human rescue, late clarification and repeated correction may be entirely appropriate, but they belong in the capacity estimate. A promise based only on the final file assumes a cleaner production process than the team may actually have.
Include the last handoff in the estimate
A price and date refer to the receiver's usable result. The estimate should include review, correction, packaging and the handoff that makes the result accessible. Producer completion can occur before those obligations are satisfied.
Separate active effort from elapsed time. A short operation can wait days for a required response. The producer may control the request and follow-up but not the receiver's decision. Preserve that dependency in the commitment instead of hiding it inside a precise-looking date.
A reserve covers ordinary uncertainty within the agreed work. It should state what kinds of discovery or correction it allows for. A newly requested audience, another deliverable or a different outcome changes scope and needs a separate decision. This distinction makes it possible to learn whether an estimate was wrong or the work itself changed.
When evidence is weak, choose a bounded first piece that can establish the next commitment. It might verify source availability, produce one representative deliverable or test an integration. Give that first piece its own acceptance condition and explain which larger result remains open. The receiver can then judge the offer with a clear view of what is and is not being supplied.
The supplier still owns composition. Several individually accepted pieces may fail to produce the intended result when connected. Verify that one operation's output meets the next operation's input needs and that the assembled result serves the original purpose. A package of completed task records is useful evidence, but the promised outcome needs its own assessment.
- Delivered parts.
- Retained connector and guide.
- Receiver assembly.
Let completed work inform the next promise
Retain the offer, estimate, delivered result, assessment and correction history together. The next estimate can cite a comparable attempt rather than inherit a broad claim that the team has become more capable.
An increase in available agents changes possible generation capacity. It may leave research access, qualified review or customer-side approval unchanged. Before enlarging the offer, compare the entire delivery path with the proposed volume. This keeps expansion tied to the constraint that actually limits accepted work.
A good proof package helps both parties. The receiver can assess the capability before relying on it. The producer can see where the demonstration required more effort than expected. The next commitment becomes more specific because the record supports a better comparison.
Run the work through five inspectable stages
The method can be operated through five stages: scope, plan, strategy, action and complete. The following twenty-five checks are a runbook, separate from the five-category quality rubric. They describe what the work should leave behind at each stage. Reuse established answers when conditions match, and investigate only the differences that could change the result.
The sequence is meant to produce a finished piece of work. A newly discovered defect should reopen the affected assumption or operation, rather than automatically restart the whole project. Keep the throughline and repair the part the evidence identifies.
Scope establishes the result and its boundaries
- Name the receiver and observable result. State who will use the work and what they will be able to inspect or do when it arrives. Describe the problem before selecting a method or tool.
- Connect the result to its purpose. Trace how the proposed deliverable contributes to the task, project, initiative, objective and mission where those levels are relevant. Remove work whose contribution cannot be explained.
- Define acceptance and misleading success. Record what counts as a usable result and how the work could appear successful while failing its purpose. Name the receiver's check before production begins.
- Record the boundaries. Preserve scope, exclusions, budget, timing, access, authority and open questions. Mark estimates and assumptions so they remain distinguishable from confirmed instructions.
- Resolve the blocking ambiguity. Use available context before asking another question. If a missing answer changes the commitment, obtain it or propose a smaller bounded result whose acceptance is clear.
The output is a brief that another worker can act on without reconstructing the commissioning conversation. The stage is ready when the receiver, result and acceptance condition are clear enough to plan. Other uncertainty can remain visible and be addressed in the appropriate later operation.
Plan maps capabilities and the work required
- Map the dependencies. Start from the receiver's need and identify the capabilities that support it. Distinguish established tools from uncertain work required to connect or adapt them.
- Size against comparable attempts. Include review, correction, rescue and handoff in the estimate. State the reference class and the differences that could invalidate it. With no comparison, make the estimate provisional and define a test.
- Assign bounded operations. Give each node its inputs, result, state, failure route and receiver. Use a function, person, agent or subgraph according to the work it must finish.
- Connect records before execution. Preserve task, attempt, output version, evidence, assessment, decision and outcome identities. Establish how the next worker will find the exact material a result depends on.
- Separate parallel work from dependent work. Start independent research or preparation together. Keep assessments and downstream production behind the specific inputs they require. Name the owner of each handoff.
The output is an executable plan with visible commitments and evidence paths. A dependency that has merely been requested remains unresolved. The plan can include a bounded investigation to resolve it without pretending the larger delivery is already assured.
Strategy chooses how to act under uncertainty
- Examine relevant participant responses. Identify who can change the outcome, their available moves and what they know. Follow a response only while it could change the choice.
- State the live hypotheses. Record the prior expectation, its basis and an observation that could disconfirm it. Arrange for that observation to reach the decision record.
- Choose the sufficient decision method. Use a rule, allocation, future-value estimate or lookahead model according to the computation the decision needs. Include the method's preparation, runtime and maintenance costs.
- Allocate the investigation. Preserve meaningful alternatives, their shared assumptions and the budget each receives. Define when another research or generation round would stop adding useful information.
- Return through the five lenses. Test the proposed action against beliefs, participant responses, commitments and the starting map. Repair contradictions before relying on the action's expected benefit.
The output is a selected action with an inspectable rationale, expected result and relevant uncertainty. It should explain why this action is worth taking now. If another round of analysis would leave the choice unchanged, the stage has supplied enough to proceed.

Action produces and checks the actual work
- Execute within the accepted contract. Record the versions, inputs and effects that matter. Protect external writes from unsafe duplication, and preserve failures rather than replacing them with a clean-looking final log.
- Review the object that will be used. Check exact text, rendered artifacts, resulting system state or other evidence appropriate to the claim. A successful tool call is one observation within that assessment.
- Keep evaluation sufficiently independent. Where judgment matters, separate initial assessment from the producer's preference. Record criteria, evidence and disagreement; use deterministic checks for conditions that can be tested directly.
- Correct the diagnosed cause. Link a repair to the failure it addresses and retain the earlier version. Recheck affected conditions on the revised output without reopening unrelated accepted work.
- Stop or escalate at a defined condition. A budget limit, unavailable dependency, unresolved authority decision or failed acceptance condition needs a recorded next action. Continue useful independent work that remains within scope.
The output is the submitted deliverable and its verification record, including any bounded limitation. The next transition depends on the receiver's assessment of that result. A producer's completion message can report what was done without assuming the receiving obligation is closed.
Complete closes the accepted unit and informs the next one
- Obtain the relevant acceptance. Preserve who assessed the result, what they inspected and what remains open. Acceptance of a component does not silently close the outcome above it.
- Compare expectation with observation. Retain the original estimate, confidence and predicted effect beside what happened. Identify whether the difference concerns capability, effort, dependencies, execution, evaluation or context.
- Record the narrow update. State which instruction, estimate, evidence relation or decision rule changes and why. Preserve the earlier version and avoid generalizing a local correction beyond its supporting cases.
- Leave unobserved outcomes unresolved. Record the required observation and who can establish it. Audience performance, long-term reuse or downstream business effects may remain pending after artifact delivery is complete.
- Use the result in the next comparable attempt. Check applicability before reusing the lesson. A later run should reveal whether the change helped, whether it introduced a tradeoff, or whether the original uncertainty remains.
The output is an accepted unit, a usable record and a defined next state. Completion can include a decision to stop, a smaller next experiment or a larger commitment supported by the evidence. It does not require inventing another task merely to keep the system active.
Preserve a minimum record across the stages
A practical schema can hold the runbook together. The fields below are a proposed starting point; teams should adapt them to their work while preserving the relationships that make an assessment reopenable.
| Record group | Minimum meaning to preserve |
|---|---|
| Identity | The task, attempt, node, artifact and exact output version |
| Action and result | The operation attempted, its permitted effects and the artifact, blocked or inconclusive result returned |
| Execution versions | The workflow, model, instructions, tools and data versions needed to interpret or reproduce the attempt |
| Objective | Receiver, intended result, purpose and scope |
| Inputs and evidence | Source identity, location, applicable version, transformations and limits |
| State | Planned, running, submitted, accepted, rejected, blocked or unresolved |
| Assessment | Criteria version, evaluator, decision, reasons and disagreements |
| Resources | Usage, elapsed time, human work, relevant costs and remaining budget |
| Authority | Allowed actions, approval owner, escalation and reversal conditions |
| Outcome and update | What was observed, when it became available and which next decision changed |
The record should be easy to use at the point where the work happens. A form can collect the same information as a conversation. A review interface can show the exact output beside its evidence. An agent can retrieve the relevant failed attempt without loading every historical document. These are applications of the shared data model and adapters, rather than separate stores that later need reconciliation.
Keep explanations proportionate. A routine action can reuse an established contract and record only the facts that changed. A new dependency, consequential public claim or unfamiliar task may require a fuller account. The test is whether the next receiver can reconstruct the decision that matters, not whether every field contains a long paragraph.
Make the next serious question affordable
A working system changes the cost of investigation. Reusable research, evidence review, generation, evaluation and handoff operations let a team ask questions that would otherwise require rebuilding the process each time. The benefit is concrete: another hypothesis can be examined, a hidden dependency can be tested, or a failure can be traced to the assumption that produced it.
Mapping makes that work connect. The capability map shows what the result depends on. Data relationships preserve which observation belongs to which attempt and decision. The intelligence stack carries meaning into the operator's workflow. Composed records and graph boundaries let specialists cooperate without requiring every participant to reconstruct the whole system.
Learning occurs when a result changes a later comparable choice and the change is tested. Some attempts will fail. Some will establish that the current method is sufficient. Some will reveal that a more ambitious question has become affordable. Keeping those outcomes distinct gives the next worker a better starting point than another prompt and a folder of polished examples.
The useful next step is a bounded piece of work with a receiver, evidence and a result that can be assessed. Finish it, preserve what happened, and let that record determine what can reasonably come next.