LLVM has a dead-code elimination pass. It walks the IR (the compiler's intermediate representation), finds instructions whose results are never read, and removes them. Modern compilers run that pass dozens of times across a single compilation unit. The cost is microseconds. The benefit is binaries that don't carry around code nobody calls.
I ported the same idea to my content compiler this morning. It parses a draft into nodes and runs passes over them the way LLVM does.
In the compiler, every paragraph in a draft is a node. Every node has inputs (claims it depends on) and outputs (claims it makes that get used downstream by other paragraphs or by the conclusion). A node whose outputs nothing else reads is dead. A node whose inputs are already provided by a more direct path is dead. A node that restates a claim the reader has already accepted is dead.
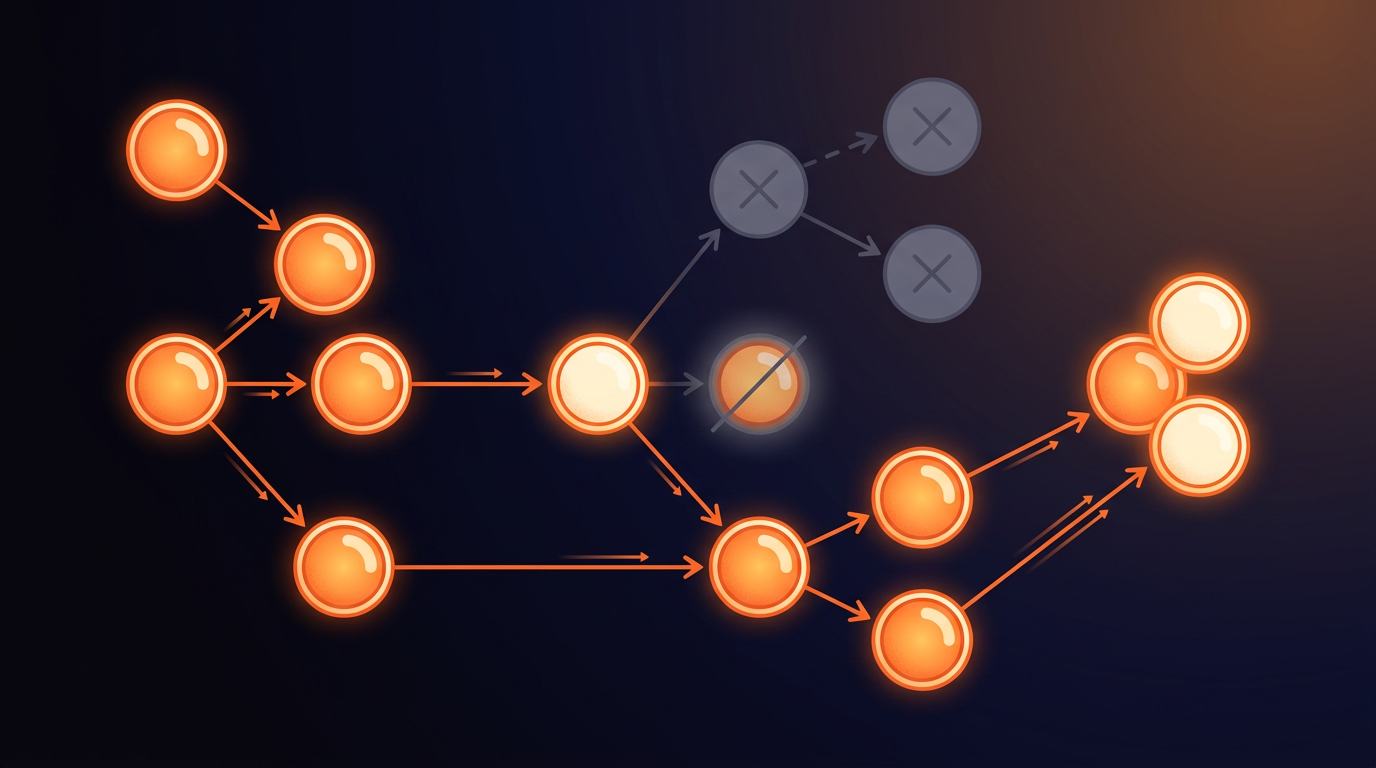
The first run on a draft of my People Product Process essay killed fourteen paragraphs.
I read the surviving version back to myself. The essay was tighter, and it made the same argument. The cuts included a paragraph I'd been particularly proud of, where I wandered into a metaphor about cathedral architecture. The metaphor was lovely, and it was also a node nothing read.
The compiler has an opinion about what's load-bearing, not about what's lovely.
I'm taking two lessons from that run before I keep building.
First, every writer has dead paragraphs, and what varies between writers is whether they have a tool that finds them, not whether they care about quality. The most dedicated writer in the world will defend a paragraph they wrote on a Sunday morning when the light was good. A pass that operates on the dependency graph rather than the prose surface doesn't have feelings about Sunday mornings.
Second, the dead-code analogy ports cleanly only if the content has a dependency graph in the first place. Most content doesn't. Most content is written linearly, paragraph by paragraph, each one continuing where the previous one left off, with no formal record of which claim depends on which. That's why most content can't be compiled, and why most editing is vibes.
The Pydantic-as-IR architecture I wrote about earlier is what makes this pass possible: the compiler's IR is a set of Pydantic data models. Each node carries its claims and its dependencies in structured form. The compiler walks the graph, and the graph tells the truth.
The next pass to port is common subexpression elimination, which finds two paragraphs that make the same claim with different sentences. The compiler picks the stronger one and deletes the other. I expect it to be brutal on every essay I've ever written.