
I committed the screenshots because I wanted the pictures and the code that produced them to stay together. Later, a full drive broke a build. Git had retained the old media in history, and each linked worktree had another checked-out copy of the files its branch contained. I'd evaluated the convenience of committing them and the convenience of parallel work separately. I hadn't accounted for their combined disk use.
That distinction changes which fix helps. History, checked-out files and downloads consume different resources. A smaller repository transfer can still leave the same pictures in every working directory.
I had good reasons to keep the pictures beside the code
The files included diagnostic captures, rendered figures and PDFs. Putting them beside the code gave me a versioned pair. I could return to a commit and find the figure alongside the implementation that existed when I saved it. A chart that looks wrong later raises an ordinary question: did the code change, or am I looking at an old render? Keeping both in a commit made that question easier to answer.
Portability was another benefit. A person cloning the repository received the tracked assets along with the source. They didn't need a separate download or a message asking where I'd put the pictures.
One repository removed a coordination problem
I also wanted one source of truth. A folder of assets somewhere else can drift away from the code that expects it. A filename can stay the same while somebody replaces its contents. The build still finds a file, which makes the mismatch harder to notice than a missing-file error.
Keeping the assets in Git avoided a separate storage service, its credentials and its retention policy. There was less to configure and less to explain to the next person working on the project. A single repository could describe the state I intended to preserve.
Those benefits survived the disk problem. Any replacement had to preserve enough of them to keep the work usable. Moving files somewhere harder to recover would have solved one storage problem by creating a reproduction problem.
The cost appeared after the decision had become a habit
The build failed on a step that had worked before. Its error didn't identify a full drive. Working back to storage took longer than reading an obvious out-of-space message would have, and the growing collection of checkouts had been consuming disk before the build exposed it.
I wrote the original note from a fresh worktree and watched its checkout counter write 12,800 files. That was a file count, not a measurement of how many bytes belonged to screenshots. It made the physical operation visible: creating an isolated working directory meant writing files into another directory on the same machine.
A few gigabytes of media and many open checkouts were enough to matter in my workflow. I don't have a disk inventory in this note that separates every retained object, generated file and dependency directory. The account explains what I found; it doesn't supply a measured attribution of the whole drive.
The useful correction was to the review I had performed. I could name why versioning the media helped, and I could name why separate worktrees helped. I hadn't asked how much media each worktree would materialize as both practices grew.
Git was preserving the files I'd asked it to preserve. Understanding where those bytes lived was the next part of the job.
Git retains the versions an old commit still needs
A commit identifies a recoverable file tree. Git stores that state as a collection of objects. A blob holds file contents; trees associate names with objects; commits refer to trees and to their parent commits. Several commits can refer to the same unchanged contents. Git doesn't need another full physical copy of a file merely because another commit includes it.
Changed contents create a different object. How much space that object occupies is a separate question from whether it exists in the version history.
Packing can save space on binary objects too
Git's git-pack-objects manual describes a packed object as either a compressed whole or a difference from another object. That difference is a delta. The packing process compares candidate objects to see whether a delta saves space.
Text often gives that process useful similarities to work with. A changed sentence can leave much of a document's byte sequence intact. Already-compressed media can offer less useful similarity between encoded versions, so repeated exports can accumulate substantial storage. The amount saved depends on the actual files and on how Git packs them.
My original explanation made this categorical: change a pixel, re-encode, and Git has to keep a full-sized file. That overstates what follows from compression. Git can delta-compress binary objects. Neither a filename ending in .png nor the fact that the file is compressed proves the result of a delta search.
The storage decision still needs scrutiny. Repeatedly exporting a figure and committing each version can retain a growing set of contents, with no guarantee that packing will make the collection cheap. A compression assumption is a poor substitute for measuring the repository carrying those particular files.
Deleting a tracked file changes the current tree
A later commit can remove the screenshot from its tree while an earlier commit continues to refer to it. Returning to the earlier state must still recover the picture. That retention is useful: it was one of the reasons I put the picture there.
The deletion can reduce what a checkout writes for the newer commit. It doesn't by itself remove the old object from repository history. These are different savings, and a successful deletion in the working directory doesn't demonstrate a smaller object database.
Git's garbage-collection documentation makes the boundary explicit. Git tries to keep objects referenced by branches, tags, the index, remote-tracking branches and reflogs. Packing can change their physical representation. Removing unreachable objects is another housekeeping operation. A picture that an earlier retained commit references doesn't become disposable because the newest commit no longer shows it.
History is therefore persistent under ordinary use, with a more precise limit than the word permanent suggests. Rewriting history and managing the remaining references can make old objects unreachable, but that's coordinated migration work. Other clones, retained refs and backups may still contain the old data. Publishing a deletion is no promise of erasure everywhere.
I wouldn't turn an article about a full drive into instructions to force a history rewrite. The person responsible for the repository has to decide which history may change and how collaborators will recover. That decision has consequences beyond the machine needing space.
Hosting limits answer another question again. A host can accept each file and the repository while local checkouts consume more disk than expected. Current vendor limits need checking against the relevant service and account. Passing them doesn't account for all the directories on a developer's machine.
Git's object store explains why old versions remain. It doesn't yet explain why creating a new working directory writes another set of current pictures. Worktrees add that second term.
Linked worktrees share history and materialize their own files
A linked worktree is another working directory attached to the same repository. It lets a stream of work have its own checkout and index while sharing the repository's objects. Git's worktree documentation describes both the common repository and the administrative state specific to each worktree.
I use that separation to keep parallel work from changing the same on-disk files underneath another task. Each task gets a path containing its own working set. Integration can still produce merge conflicts later. Separate directories isolate the work in progress, not the meaning of the changes.
That isolation is worth keeping. It also identifies what to count.
The shared store and the directories grow differently
Adding a linked worktree doesn't duplicate the whole history. It creates another place to materialize the files for the revision being checked out. A tracked image present in that revision can therefore exist both as stored content in Git and as a file in the new directory.
The same image can appear in every other full checkout that contains it. Sharing the object database doesn't make those working-directory files share the same physical storage by default.
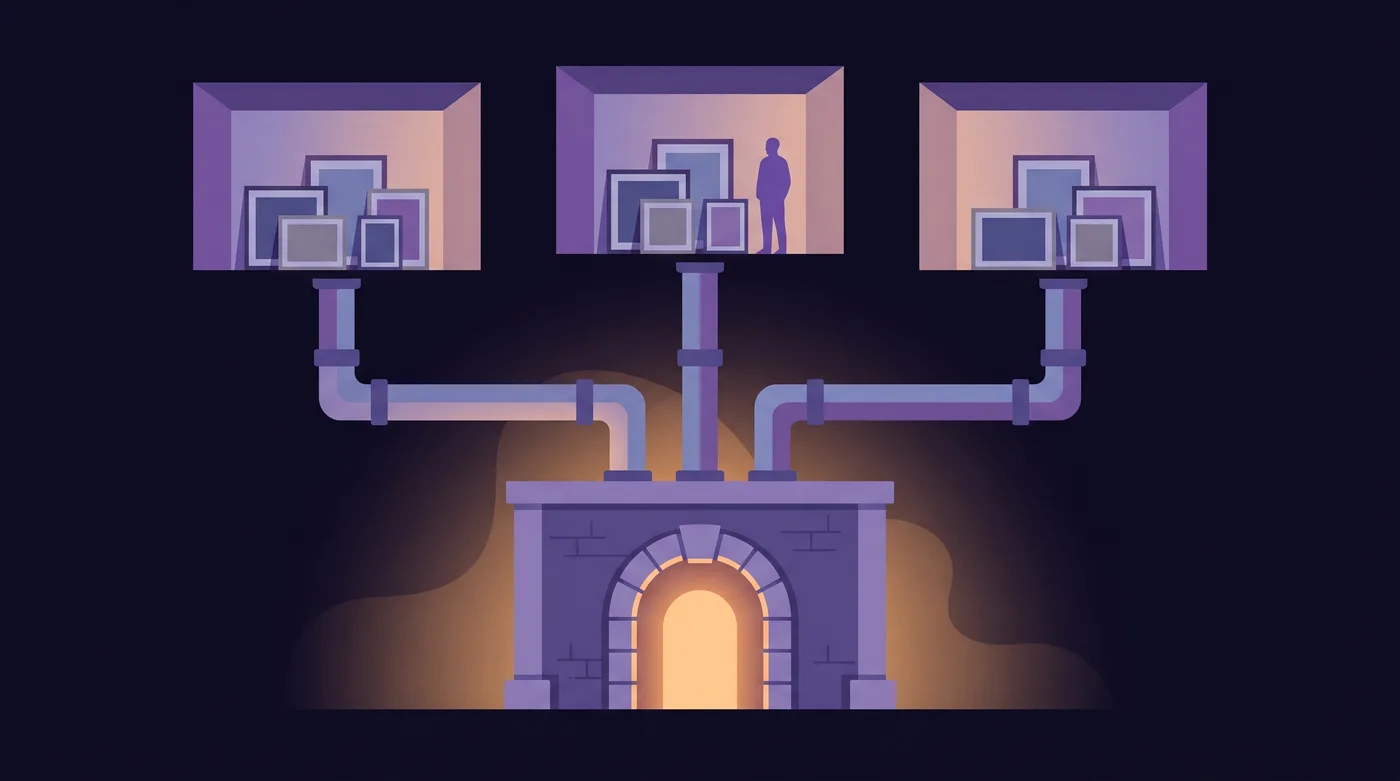
The useful accounting model is one common object store plus the files materialized in each working directory, with per-worktree metadata alongside them. A real development folder can also contain dependencies, build output and caches. Those need their own accounting; Git's sharing arrangement says nothing about whether a build tool shares its outputs.
This is why counting the visible .git entries in linked worktrees can mislead. The administrative pointer in a worktree isn't a second copy of the whole object database. Counting the common store again for each path exaggerates history. Ignoring the rest of each directory understates the checked-out files.
The model also needs the branches actually in use. Worktrees on different revisions may contain different media. Sparse checkouts may materialize only a subset. Multiplying one directory's size by the number of worktrees is an estimate whose assumptions have to be checked, not a disk inventory.
Adding media raises the cost of every checkout that includes it
Hold the media collection fixed and another full checkout adds another collection of materialized files. A fixed number of full checkouts consumes more storage as the media collection in each one grows.
Both quantities can grow together. That interaction was missing from my review. A worktree was inexpensive when the tree was small. Keeping many worktrees open became a different storage decision as the tracked tree grew heavier.
Calling the interaction superlinear without saying what varies is loose. For a fixed set of files, storage grows with the number of full working copies. For a fixed number of copies, it grows with the files each contains. The product changes when both grow. No unusual Git behavior is needed to explain it.
A review of the worktree practice should therefore include what the practice repeats. A review of committed assets should include where those assets will be materialized. Reviewing both decisions together would have exposed a question that neither list of benefits answered.
Measure the directories as well as the repository
Git can help locate the working copies. These are read-only starting points for an investigation, not output from a new measurement of my incident:
git worktree list --porcelain
git count-objects -vH
The first lists worktrees associated with the repository. The second reports object-storage information. It doesn't add up the screenshots, dependency directories and generated output under every listed path.
Use a disk-usage tool to measure those paths and distinguish tracked media from the other large directories. Keep the common object store separate and count it once. Be clear about whether a reported size means logical file bytes or allocated disk space, especially if the filesystem uses compression or deduplication.
The investigation should end with a located quantity. Large historical objects, repeated current assets and repeated build output invite different changes. A repository-size number alone can't choose among them.
Choose the remedy for the bytes that caused the problem
Git LFS is an understandable first response to a repository full of media. It stores small pointer files in Git while a separate LFS server stores the large contents. Code and pointer versions can move together in a commit. Git's ordinary object history no longer has to carry each new large file as a normal blob once the file is managed through LFS.
Enabling LFS for future work doesn't remove ordinary blobs from existing history. A migration of those old contents is a separate decision.
LFS can put full assets into each checkout
The Git LFS manual describes downloading the actual contents when needed, including when checking out a branch containing the large file. A repository with tiny pointer files can therefore produce a working directory with full-sized images.
That behavior is useful. The renderer expects a picture, and LFS can deliver it without requiring somebody to fetch it by hand. It also means that switching to LFS alone doesn't establish that my many-working-directories problem has gone away. The relevant question is whether every checkout will contain the full assets again, and which jobs can operate without them.
LFS hosting introduces its own storage and download accounting. A CI job that downloads assets repeatedly creates a different usage pattern from a developer keeping a working copy. How much is charged depends on the host, the account and what actually gets fetched. Check current billing and quota behavior before choosing it.
LFS can be the right home for source assets. Evaluate that choice with the checkout behavior included. Moving large contents out of normal Git objects and choosing which contents to materialize solve related but separate problems.
Shallow and partial clones change what arrives from the remote
A shallow clone truncates the history fetched. It can suit a job needing a recent revision and no older ancestry. A full checkout of that revision can still contain all its tracked media. Shortening history doesn't make the current pictures smaller.
The missing history can also change the behavior of work that depends on ancestry. A release calculation, comparison or investigation may need commits the shallow clone doesn't have. The job's actual requirements determine whether the smaller initial fetch is useful.
A partial clone asks for a subset of objects. With a blobless filter, Git can defer file contents until needed. Commits and trees can remain available while an operation needing a missing blob fetches it later.
That deferral helps most when the workflow doesn't eventually request everything. Checking out a complete tree can request the files that tree needs. Reading older contents can request more. The remote has to support the arrangement, and operations needing absent objects depend on access to it.
Sparse checkout changes which files appear in the working directory
Sparse checkout directly addresses the materialized-file term. It selects a subset of tracked paths for the working directory. A task that never needs the media directory doesn't have to populate that directory as part of its normal working set.
Sparse checkout alone doesn't purge old blobs or turn an existing full clone into a partial one. Combining sparse checkout with a supported partial clone can avoid both fetching and materializing files the workflow never needs. The combination is useful precisely because the mechanisms control different quantities.
This comparison starts with those quantities rather than with a preferred product:
| Option | Quantity it can reduce | Boundary to check |
|---|---|---|
| Git LFS | Large contents in ordinary Git objects | Full assets may still be downloaded into every working copy; old history needs separate migration |
| Shallow clone | History initially fetched | Current-tree assets remain; ancestry-dependent work may need more history |
| Partial clone | Objects initially fetched | Missing contents need fetching on access and a supporting remote |
| Sparse checkout | Files materialized in a working directory | Selected paths must cover the task; history already stored remains |
| External asset store | Assets carried by Git | Recovery now depends on the store and a durable code-to-asset reference |
None of these rows is a universal winner. Each makes a claim about a different part of the workflow. Match that claim to the measurement before changing how the team gets its files.
Preserve the code-and-asset relationship when the bytes move
An external asset store removes large contents from Git's normal storage path. It can also remove a useful guarantee I had been relying on: a checkout containing everything needed to inspect that saved state.
A reference in a commit can identify an asset elsewhere. Recovering the pair then depends on the asset still existing, access still working, and the reference still identifying the intended contents. Code history can preserve a pointer after another system has deleted or replaced its target.
A filename alone doesn't preserve a version
Consider an illustrative arrangement, not another incident from my work. A commit names a picture in an external bucket. Somebody replaces the picture at the same address. Checking out the old commit recovers the old address, but the bytes now returned by that address belong to the replacement.
That's the coordination risk the single repository had avoided. Keeping an immutable asset version or content identifier with the code can preserve a precise relationship. The store still needs a retention policy that keeps the identified version available and a recovery path the people doing the work can use.
The trade therefore isn't accurately described as Git having atomicity and every external store having none. A commit can preserve a versioned manifest. An asset-management system can provide versioning. The question is what has to work for the pair to be recoverable and who maintains that behavior.
Put that responsibility into the choice. Which process writes the asset reference? What happens if the upload fails? Can an old revision recover its inputs after credentials change? Can someone distinguish a missing asset from a valid empty result? Those are operational requirements, not reasons to reject external storage before examining it.
A narrower workflow can avoid unused files
I initially pushed the argument toward every mitigation moving an unchanged cost somewhere else. That claim is too tidy. Disk bytes, transfer bytes, latency and maintenance effort don't have a common unit that makes them conserved quantities.
A job that needs only a narrow part of a repository can genuinely benefit from partial clone and sparse checkout. The unused files may never need to cross the network or exist in that working directory. Maintaining the selection still takes care, but it can cost far less than repeatedly transferring and writing irrelevant assets.
The boundary is the job. A source-only check and a complete visual build can require different paths. Giving both the same checkout policy because they live in the same repository may materialize files one of them never uses. Conversely, a sparse selection that omits a real input produces a broken job rather than an efficient one.
The declared working set has to support the work people actually perform. A workflow that starts narrow and later begins building the full site has changed. Its storage and fetch assumptions need revisiting at that point.
Compare the replacement with the benefits it must preserve
The original decision bought version pairing, portability, one place to find the files and fewer systems to maintain. The replacement deserves the same concrete review.
LFS can retain versioned pointers and automate asset delivery. An external store can separate a large collection from routine code checkouts. Sparse checkout can leave the repository's storage model intact while giving one task a smaller working set. Each can preserve enough of the original convenience to be a better choice for a particular workflow.
Some trades reduce total work. Others exchange local capacity for an ongoing service dependency. I want the accounting to show that difference, with the old benefits still visible, rather than requiring the story to prove that every remedy is another trap.
Total cost of ownership includes what happens after adoption
The Git incident doesn't need a new named framework. Total cost of ownership already asks a broader question than the immediate price: what resources does a choice require over its useful life? Storage, maintenance, support, integration and migration belong in that account alongside acquisition.
A command with no purchase price can still start a process that consumes capacity. Committing a file asks a version-control system to retain recoverable contents. Opening worktrees asks the machine to materialize working sets. Neither needs a vendor invoice to have a cost.
A useful benefit can coexist with a growing operating cost
My first review established real benefits. It didn't establish an affordable lifecycle. Those are separate conclusions, and an adoption decision needs both.
The distinction also limits the original picture of a flat benefit line and an ever-rising cost line. Version pairing was available as soon as the media was committed, but its value can change as a project and its collaborators change. Storage can shrink when working copies are removed or no longer contain the assets. The particular incident had delayed cost visibility. It doesn't prove a universal shape for every tool's benefits and costs.
Total cost of ownership is useful here because it keeps the deferred work inside the decision. A storage choice that looks inexpensive during setup can demand a coordinated history migration later. A separate asset service can introduce maintenance earlier and make everyday checkouts cheaper. Comparing those lifecycles is more informative than comparing the setup commands.
Cost ownership determines whether someone will act
The person receiving a benefit and the person absorbing its cost can differ. A developer may get a convenient checkout while an infrastructure team manages the storage or a finance team receives a service bill. That split is an accountability question even inside one company.
The original note called this an externality. The economic term needs care: a cost moving between internal budgets doesn't by itself demonstrate an externality in the strict sense. The question survives without stretching the label. Who can create the usage, who sees it and who has the authority to change it?
Unit economics makes the question repeatable by attaching cost to an observable unit of work. For this case, useful units include materialized bytes per working directory and bytes downloaded per CI job. FinOps belongs in the wider conversation about understanding and owning technology spend. Naming the discipline doesn't substitute for deciding which local quantity the team should inspect.
A warning sent to somebody who can't change checkout policy may produce no action. A report showing only the hosted repository can miss the developer's disk altogether. Assign the measurement where the resource is consumed and the decision where the consumption can change.
Jevons and technical debt answer narrower questions
Jevons paradox concerns a rebound in total consumption when efficiency makes a resource cheaper to use and encourages more use. Worktrees made parallel checkouts convenient in my workflow, which makes rebound a useful possibility to consider. My account doesn't measure how many checkouts I'd have maintained under another arrangement. It can't establish that causal comparison.
The direct storage explanation needs less: the working copies that existed contained files, and those files occupied disk. That mechanism holds without proving why I chose that many working copies.
Technical debt can help describe an accumulated obligation to change a system. It doesn't identify the missed storage term on its own. I had evaluated why the tools helped and omitted how their costs combined. Calling the result debt would still leave the reader needing to distinguish history, current files and transfer.
Use the established vocabulary where it clarifies a decision. Keep the physical accounting underneath it. The next tool may have a different storage model, and the units will tell you more than the resemblance of its story to mine.
Caches and telemetry need their own accounting too
The Git problem makes a useful question available for other engineering decisions: what quantity does this feature retain or repeat? The answer changes with the tool. Assuming every cost follows the same curve would repeat the original mistake of leaving the units unspecified.
Docker layer caching, bundled dependencies, CI caches and observability all provide useful benefits. Their costs need separate descriptions, including where the retained data lives and which operations move it.
Faster builds can retain more data
Docker layer caching reuses prior build work. A useful review asks which layers remain locally, which are stored in a registry and which must be pulled by another machine. A local build cache and a registry are different storage locations. Their cleanup behavior and any hosting charges need checking in the actual setup.
Dependencies copied into an image also become part of the image delivered to its consumers. That can support repeatable execution while increasing the bytes stored and transferred. .dockerignore and multi-stage builds address particular parts of that process; a recommendation only helps when it changes what the build actually includes.
A CI cache trades repeated computation for saving and restoring data. The worthwhile comparison includes restore work, upload work, cache usefulness and retention. A cache that exists but rarely helps is a different case from one that avoids substantial repeated work. Cache correctness is another boundary: reusing stale state can produce a bad build even when the storage charge looks acceptable.
The relevant counters differ. Retained layers, image bytes and cache contents aren't interchangeable just because all of them occupy storage. Locate each collection and the operation that grows it before choosing a cleanup policy.
More debugging detail can create more telemetry
I use structured observability in my Python work because reconstructing a failure requires evidence of what happened. Understanding an earlier sequence of events is much harder when the records can't be queried usefully. That benefit is worth preserving when reviewing storage and retention.
The observability argument is developed separately. Here the storage question is narrower. Collecting records, indexing them, retaining them and recording metric series can have different usage measures. Watching one measure doesn't establish that the others are stable.
A metric label carrying a user identifier or a URL can increase the number of distinct label combinations recorded as time series. That's a cardinality question. Whether the change creates a particular charge depends on how the chosen system measures and prices it. Neither the usefulness of the label nor an assumed vendor bill is enough to decide the trade.
Removing detail blindly can destroy the evidence needed to investigate a real failure. Define the questions the team needs to answer, then choose the collection and retention that support those questions. Put the usage created by that choice where somebody can inspect it.
A repeated incident total still needs an original source
The original research for this note couldn't trace a widely repeated metrics-overage story back to a primary account. That's a limit on the evidence available for that story. It doesn't establish whether the event happened, what caused it or how common similar incidents are.
A vendor's documented billing mechanics can support a claim about the meter. An invoice or a first-hand postmortem can support a claim about what happened to a particular team. Several articles repeating a total don't replace either one, especially when their references lead back to each other.
I don't need an unverified bill to explain why repeated downloads or distinct metric series deserve inspection. The mechanism already gives the reader a quantity to examine in their own system. A dramatic total would add authority only if its source and circumstances could be checked.
Review what grows and who can change it
Adoption is a useful point to ask about cost because the workflow is still being chosen. The first result may be small, but the operation that will repeat is already visible. A test checkout reveals that files are materialized. A CI design reveals which jobs fetch assets. A retention setting reveals that records will remain after their initial use.
The unknown is often the future quantity. Treat it as an assumption to examine, with its driver named, rather than filling in a confident forecast.
Start with the resource and its driver
Write the unit beside the benefit. Versioned screenshots consume retained-object storage and working-directory space. Asset delivery can consume transferred bytes. An observability choice can create ingested data, indexed records or distinct series.
Then identify what changes each quantity. Media exports create versions. Open checkouts create materialized copies. Jobs that download assets create transfer. Keeping a record longer creates a retention requirement. Some drivers follow deliberate content changes; others follow automation that keeps running after the initial setup.
A scenario can test the relationship without pretending to be a forecast. Ask what happens as the working set grows, as more tasks run in parallel or as CI performs more clean checkouts. Keep the assumptions visible. Don't multiply a rough asset estimate into an apparent measurement of the whole machine.
An alert needs a measured quantity and an action
A warning on hosted repository size wouldn't have described the sum of my local working directories. A warning on one file wouldn't have described repeated copies of a collection. Set the alert against the resource whose exhaustion would hurt the workflow.
Name who receives it and what they can do. A useful local disk warning could trigger an inspection of active worktrees and large generated directories. A download-budget warning could trigger a review of the jobs fetching assets. Those are different responses because they control different quantities.
Automation can give an artifact class a mechanical owner, but a notification isn't the whole owner. Somebody must have authority to respond, preserve unfinished work and decide what can change. A warning with no response path only documents that the limit was crossed.
Inspect the exit before shared history makes it expensive
Reversibility has stages. Staging a file, committing it locally and sharing a history containing it create different recovery work. Describing the whole sequence as either reversible or irreversible hides the part a team must coordinate.
An old binary can remain recoverable after a new commit deletes it. Removing it from retained history can require changing commit identities and handling copies elsewhere. The operation that introduced the file may have been simple while the later migration is shared work.
The original note used a one-way-door comparison to make that difference visible. Keep the question the comparison asks: what must change to leave this choice, who else is affected, and which parts of the cost grow with continued use? A history rewrite isn't literally impossible. It's a different class of action from undoing an unshared edit.
A compact adoption record can follow this order:
- State the benefit the workflow needs and the quantities it will retain or repeat.
- Name the driver of each quantity and the assumptions behind a larger-usage scenario.
- Choose a measurement, a response threshold and someone authorized to act on it.
- Describe the exit work, including references, retained copies and people who depend on them.
- Scale the review to the consequences of the choice and how much of it can be reversed safely.
For a consequential choice, add a premortem: assume it failed later and describe a plausible mechanism. In this case, asking what repeated full checkouts would do as media grew would have been enough to expose the missing interaction. The exercise is useful when it produces a quantity or dependency the review omitted. It doesn't guarantee that every failure has been anticipated.
The record should stay short enough to use. Its value is that the next person can see what was assumed and recognize when the workflow has changed.
Decide where the first binary belongs
A binary arrives in a repository for a reason. Before making its storage a habit, identify what role it plays. A rendered chart, an original photograph and a diagnostic screenshot can all be image files while requiring different preservation decisions.
The filename extension doesn't answer whether the file can be regenerated. That question depends on the inputs and the process that created it.
Derived output needs a reproducible source
A figure produced from committed code can be derived output. Keeping the renderer and its inputs can make checking in every export unnecessary. The fresh checkout then needs a documented way to produce the output before someone can inspect it.
Rebuilding the old figure requires its inputs as well as its renderer. A renderer that reads changing remote data doesn't recover an old picture merely because its source code is in Git. The required data, configuration and environment have to be recoverable too. Otherwise, a new render may produce a new answer while everyone assumes it represents the old state.
My original reason for versioning pictures still applies. Someone investigating a chart needs to know which code and inputs produced it. A derived-asset policy should preserve that relationship, whether it stores every output or gives the team a reliable way to rebuild the one they need.
A diagnostic screenshot can be a source record in its own right. The screen may depend on a transient state that no renderer in the repository can reconstruct. Treating every screenshot as disposable build output would discard the evidence that made saving it worthwhile.
Source assets need a versioned and recoverable home
A file that can't be regenerated from preserved inputs needs storage that reflects its value as an input or record. LFS and external asset storage are options. Ordinary Git may still be proportionate for a small collection whose retention and checkout costs are acceptable.
Choose the home with retrieval in mind. The version must be identifiable, the contents must survive the retention policy, and the people or jobs needing them must have a supported way to obtain them. A reference that nobody can resolve doesn't reproduce the convenience of a repository containing the file.
Ignoring derived files prevents future accidental additions only if they're untracked. Git's ignore documentation is explicit that ignore rules don't affect files already tracked. Adding a directory to .gitignore is therefore no claim that existing history or current tracked contents have been cleaned up.
Handle an existing collection as a migration. Preserve the work, decide which future files belong under version control, and separate changes to current checkouts from any proposed changes to history. The owner of that history has to authorize the latter.
Existing worktrees need a working-set decision
Sparse checkout is worth examining when tracked media is replicated across worktrees that don't need it. A task editing source can have a different working set from one checking rendered assets. The chosen paths must still support the task's real commands and inputs.
The same inspection may find generated output or dependencies rather than tracked media dominating a directory. That finding changes the remedy. Removing historical blobs won't remove an unrelated build cache. An asset-store migration won't decide which unfinished worktrees are safe to retire.
I still commit media in some repositories. A small collection with a limited checkout pattern can justify the original convenience. The lesson would be weaker if it required pretending the benefits had disappeared or that every repository needed a separate asset system.
What changed is the question I write down before taking that convenience. Which bytes will history retain, which files will each working directory materialize, and which jobs will download them? I can then choose a measurement and a remedy for the relevant quantity.
I wanted the screenshots beside the code so I could recover the pair later. I still want a recoverable pair. Now the decision includes what retaining and checking out that pair will require as the work grows.
Source notes: the storage mechanisms above can be checked in Git's git-worktree, git-pack-objects, git-gc, git-clone, git-sparse-checkout, git-count-objects and gitignore manuals, and the Git LFS manual. The incident and checkout observation are my original field account, without a reconstructed disk inventory. Service-specific limits and billing rates need current provider documentation before a migration decision.